> ## Documentation Index
> Fetch the complete documentation index at: https://arize-ax.mintlify.site/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Decision Judge
> Score traces with a decision model from TypeSafe AI or OpenAI. Typed boolean, choice, and score questions answered in one call, with confidence instead of free text.
Decision Judge is an experimental feature. The in-product UI and workflow may change as we continue to improve the experience. It was previously called **Jev-as-a-Judge**.
A **Decision Judge** evaluates traces with a **decision model**: a model built for classification, scoring, and routing rather than text generation. You send one shared **state** plus typed **questions**; the model returns a structured label and a confidence (or rubric) score for every question in a single call, with no free-text explanation.
Decision Judge is provider-neutral. The same evaluator definition runs on any supported decision model; you pick the provider when you choose the AI provider in the editor.
For when to choose a decision model over an [LLM-as-a-judge](/docs/ax/evaluate/evaluators/llm-as-a-judge), see [Can decision models replace LLM judges?](https://arize.com/blog/typesafe-jev-llm-judge/).
 ## Supported providers
| Provider | Model | How to connect |
| :- | :- | :- |
| [TypeSafe AI](/docs/ax/security-and-settings/integrations-playground/typesafe) | `jev-latest` | Add a TypeSafe AI key under **Settings → AI Providers**. Eval-only. |
| [OpenAI](/docs/ax/security-and-settings/integrations-playground/openai) | `gpt-6-luna` | Reuses your existing OpenAI integration. The integration must use the default OpenAI base URL (or the US or EU regional endpoint) and have `gpt-6-luna` enabled. |
Each provider exposes one decision model. The **AI Provider** dropdown in the evaluator editor lists only the integrations in your space that can run Decision Judge evaluations. Each result row records the serving model in its metadata, so you can tell which provider scored it.
TypeSafe AI integrations are **restricted-use**: they power Decision Judge evaluators only and do not appear in the prompt playground, LLM-as-a-judge model pickers, or the `/v2/ai-integrations` REST API. OpenAI keys keep all their other uses.
## Question types
Each question needs a **name** (used for the published column only) and **instructions** (what the model actually judges). An evaluator can hold up to 64 questions. Results land on:
`eval. .{label,score,...}`
| Type | Returns | Score |
| :- | :- | :- |
| **Boolean** | `true` / `false` | Confidence in the winning answer |
| **Choice** | Selected option (2–255 options) | Confidence in the selected option |
| **Score** | Rubric position (2–10 levels) | Position on your levels, with a maximize or minimize direction |
## Create a Decision Judge evaluator
Go to **Settings → [AI Providers](https://app.arize.com/account/ai-providers)** and add a [TypeSafe AI](/docs/ax/security-and-settings/integrations-playground/typesafe) key, or confirm you already have an [OpenAI](/docs/ax/security-and-settings/integrations-playground/openai) integration with `gpt-6-luna` enabled. You can also add a TypeSafe AI provider inline from the evaluator form.
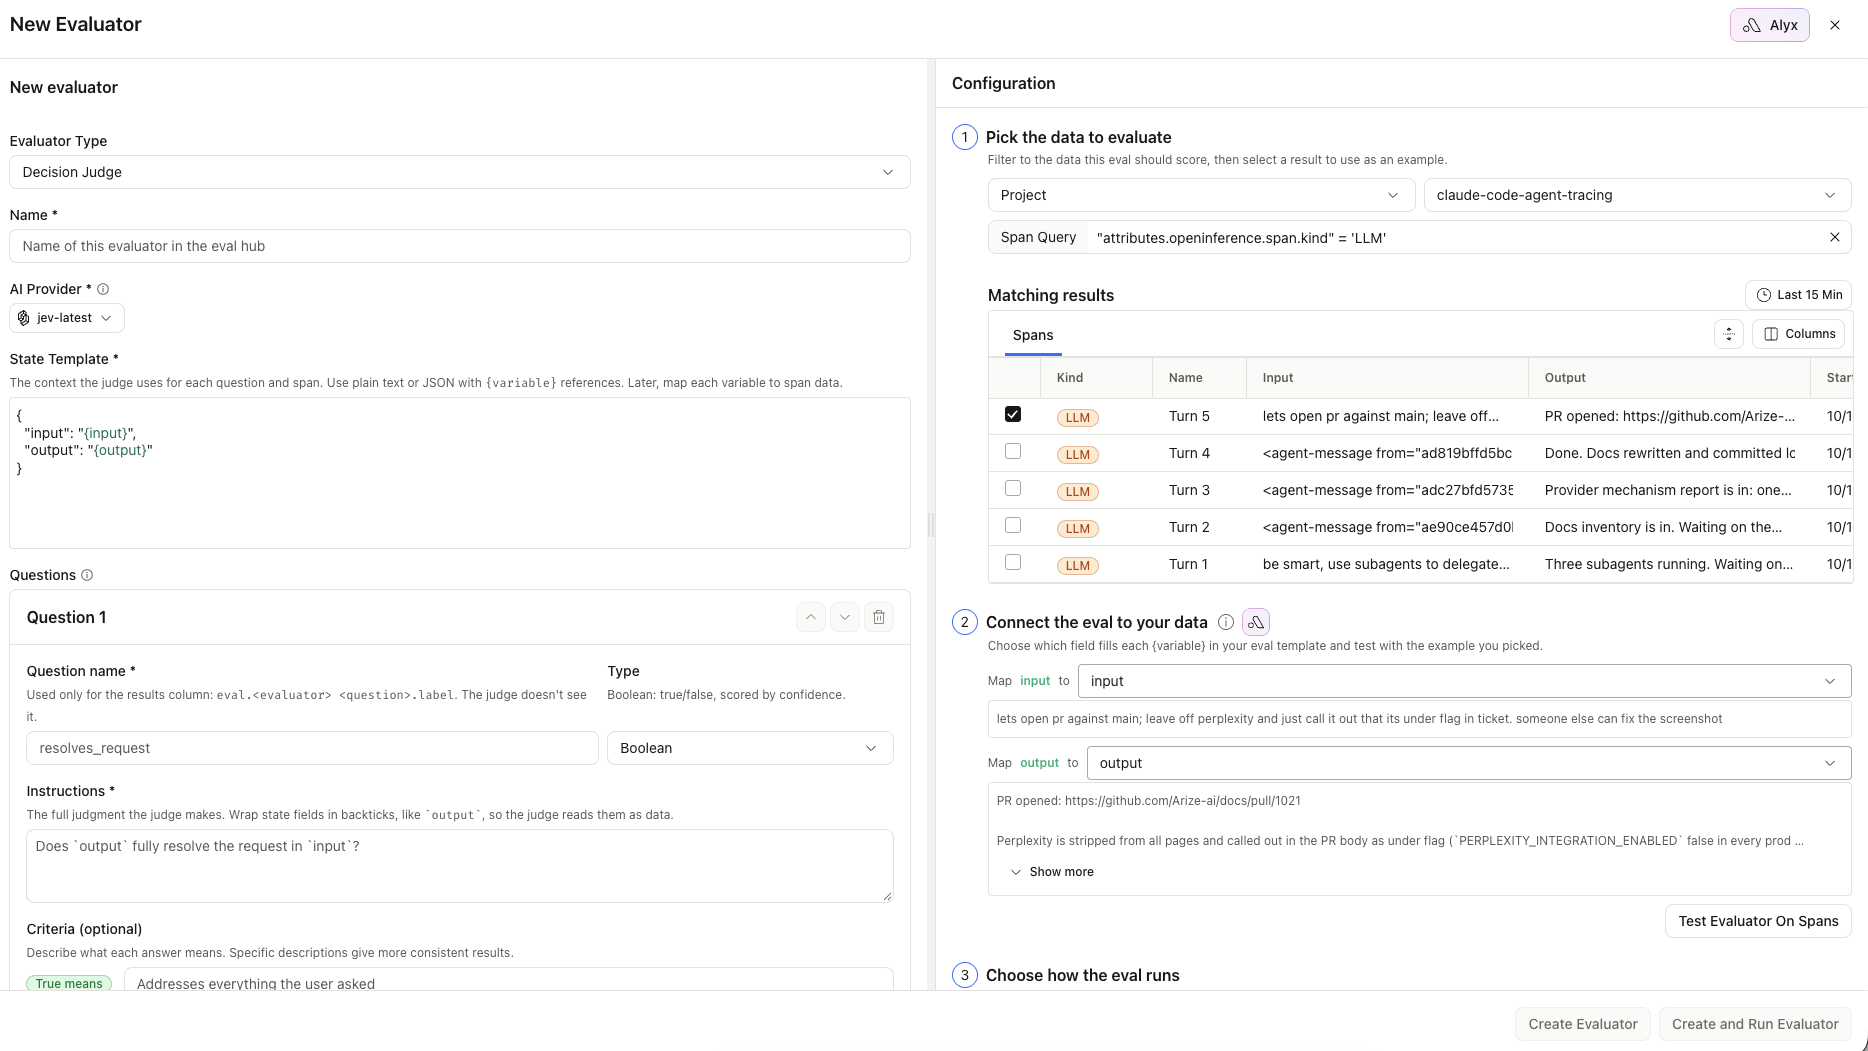
Go to **Evaluators → Create → Decision Judge**. In the **AI Provider** dropdown, select the integration and decision model to use.
Define the shared **state** (plain text or JSON with `{variables}`), map variables to span columns, then add one or more boolean, choice, or score questions. Put the full judgment in **instructions**; the question name is not sent to the model.
When you refer to a state field in a question, wrap it in backticks (for example `` `output` ``) so the model treats it as data, not as part of the instruction text.
Optionally run **Test Evaluator On Spans**, then **Create Evaluator** or **Create and Run Evaluator**. Attach it to an [online eval task](/docs/ax/evaluate/run-evals-on-traces) like any other evaluator.
## Start from a template
Most [Arize eval templates](/docs/ax/evaluate/evaluators/llm-as-a-judge#arize-eval-templates) have a Decision Judge version, including Hallucination, Q\&A Correctness, User Frustration, Toxicity, Profanity, Prompt Injection, Jailbreak, RAG Relevancy, Summarization, and Code Readability. Open a template card and pick a TypeSafe AI model in its model dropdown to load the Decision Judge version; pick a chat model to return to the LLM-as-a-judge version. Template versions currently run on TypeSafe AI only.
Decision Judge evaluators run on project spans only: they cannot run in the prompt playground, on datasets, or at trace or session granularity. A task holds a single Decision Judge evaluator, and you cannot mix it with LLM, code, or [remote evaluators](/docs/ax/evaluate/remote-evaluators) on the same task. Decision Judge calls are not traced, so runs do not produce eval traces.