> ## Documentation Index
> Fetch the complete documentation index at: https://arize-ax.mintlify.site/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# LLM-as-a-judge
> Judge LLM outputs using LLMs
LLM-as-a-Judge is an evaluation approach that uses an LLM to assess the quality of another model's outputs. LLM evaluation is extremely flexible, because you can specify the rules and criteria in mostly plain language, similar to how you would ask human evaluators to grade your responses.
You can run thousands of evaluations across curated datasets without the need for human intervention. This creates a scalable form of evaluation using only scoring or classification prompts to measure performance.
In Arize AX, LLM evaluators are managed in the Eval Hub, where they are versioned and reused across tasks. See [Where evaluators live](/docs/ax/evaluate/create-evaluators#evaluator-hub).
 ## What to evaluate
Start where problematic traces cluster: repeated confusion or dissatisfaction in user messages is a good cue to build a **user frustration** eval and measure how often it fires. Your eval input can be any mix of the agent's inputs, outputs, metadata, and prompt variables, pulled from whole traces or from the specific spans that show the behavior you care about.
Arize eval templates
If you don't want to start from scratch, Arize AX has predefined evaluation templates for common response-quality, agent, RAG, and security checks. Select one in the evaluator gallery to start with its prompt, labels, scores, optimization direction, and default scope already configured.
| Category | Template | Default scope | What it measures |
| ---------------- | -------------------------- | ------------- | ------------------------------------------------------------------------------------ |
| Response Quality | Hallucination | Span | Whether answers are grounded in reference context or hallucinated |
| Response Quality | Q\&A | Span | Whether the question was answered correctly using reference data |
| Response Quality | User Frustration | Span | Whether the user sounds frustrated versus neutral in the conversation |
| Response Quality | Toxicity | Span | Whether content is toxic or acceptable |
| Response Quality | Summarization | Span | How well a summary captures the source material |
| Response Quality | SQL Generation | Span | Whether generated SQL correctly matches the question and schema |
| Response Quality | Human vs AI | Span | Whether text reads as human-written versus AI-generated |
| Code Quality | Code Functionality | Span | Whether code behaves as intended for the given task |
| Code Quality | Code Readability | Span | Whether code is clear and maintainable to read |
| Trajectory | Tool Calling | Trace | Whether tool calls match the actions the assistant should take |
| Trajectory | Task Completion | Trace | Whether the agent completed the user's task across the trace |
| Trajectory | Step Efficiency | Trace | Whether the agent reached the outcome without redundant or wasteful steps |
| Session | Session Resolution | Session | Whether the user's request was resolved by the end of the session |
| Session | Topic Coherence | Session | Whether the assistant stayed coherent and on-topic across the session |
| Session | Session Frustration | Session | Whether the user grew frustrated over the course of the session |
| Session | Session Completion | Session | Whether the user accomplished their overall goal across the session |
| RAG | RAG Relevancy | Span | Whether retrieved context is relevant to the user query |
| RAG | Reference Link Correctness | Span | Whether answers correctly reflect linked documentation |
| Security | Toxicity Check | Span | Whether the AI response contains toxic, hateful, or threatening content |
| Security | PII Detection | Span | Whether the text contains personally identifiable information (PII) |
| Security | Competitive Mention | Span | Whether the AI response references or endorses competitor products or companies |
| Security | Profanity Check | Span | Whether the text contains profanity or highly offensive language |
| Security | Secrets Detection | Span | Whether the text contains exposed API keys, passwords, or other credentials |
| Security | Drugs / NSFW | Span | Whether the AI response contains references to illegal drugs or NSFW content |
| Security | Prompt Injection | Span | Whether user input contains a prompt injection attempt targeting the AI system |
| Security | SQL Injection | Span | Whether user input contains SQL injection patterns designed to manipulate a database |
| Security | Jailbreak Detector | Span | Whether user input attempts to bypass AI safety guidelines or ethical constraints |
| Security | Unusual Prompt | Span | Whether the user prompt is anomalous or exhibits adversarial behavior patterns |
The default scope follows the template's intended unit of analysis. You can customize the generated evaluator after selecting a template.
## Custom eval templates
Custom evaluation criteria and prompt templates let you measure what actually matters for your agent - going beyond what generic templates can assess. For example, you might create a custom eval to check for regulatory compliance, tone consistency, or task completion accuracy.
For multimodal applications, map the image or audio reference alongside the text output. The [receipt image judge cookbook](/docs/ax/cookbooks/evaluate/evaluate-receipt-agents-with-image-judge) shows a span-level evaluator that labels structured receipt extraction as `grounded`, `not_grounded`, or `needs_review` based on the source image.
In the guide below, we walk through how to build three types of custom LLM-as-a-Judge evaluators:
* **Categorical Classification Evaluator** – for labelling outputs (ex: “Compliant” vs. “Non-compliant”).
* **Numeric Classification Evaluator** – for scoring responses (ex: rating helpfulness from 1-10).
* **Fully Custom LLM Evaluator** – for more complex evaluations such as multi-step reasoning or domain-specific accuracy.
The steps below show how to create and configure these evaluators in Arize AX.
Set up an [AI provider integration](/docs/ax/security-and-settings/integrations-playground/overview), write your eval template, map variables to your data, and save it to the Eval Hub. For when to use span, trace, or session scope, see [Eval scope](/docs/ax/evaluate/create-evaluators#scope).
You can create an LLM-as-a-judge directly in the UI, or have Alyx or Arize Skills do it for you.
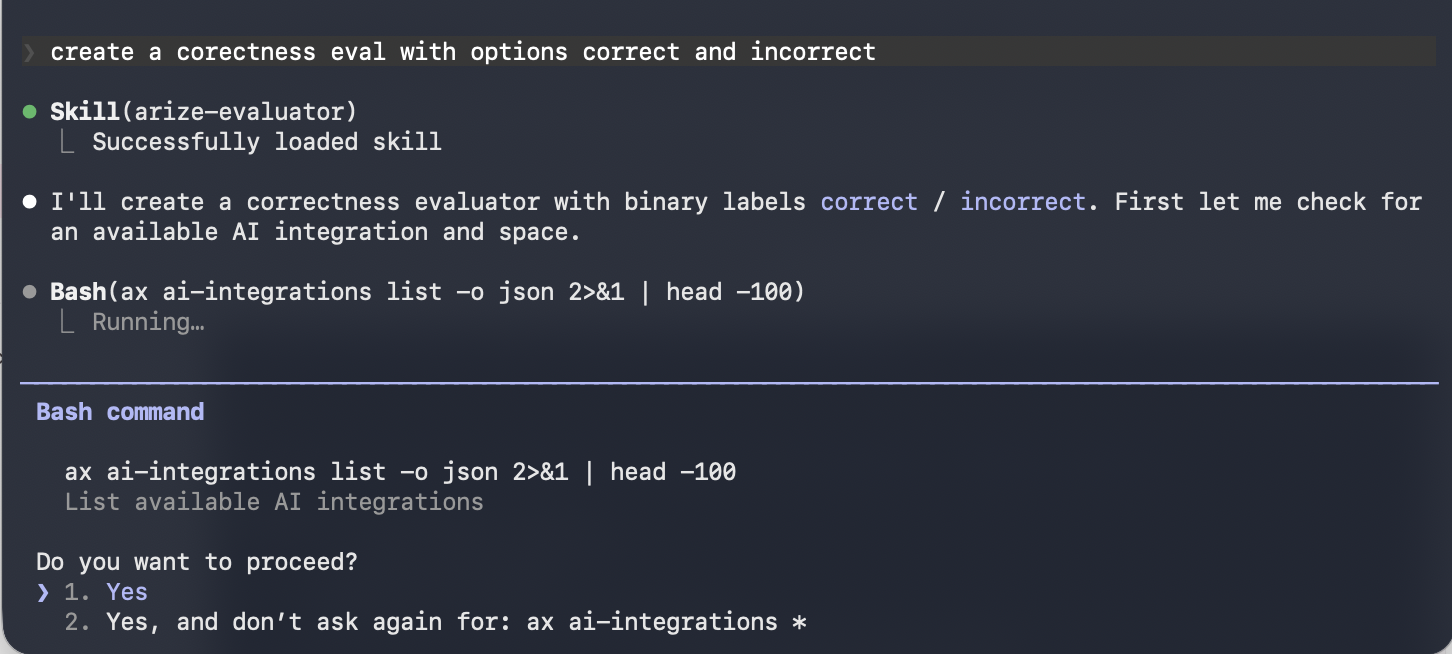
Use the [Arize skills plugin](/docs/ax/skills/overview) in your coding agent and the [arize-evaluator skill](https://github.com/Arize-ai/arize-skills/blob/main/skills/arize-evaluator/SKILL.md) to create evaluators via the `ax` CLI without leaving your editor. See the skill doc for supported commands. Then ask your agent:
* "Create a hallucination evaluator for my project"
* "Create an evaluator from blank with correct/incorrect labels"
* "Update the prompt on my correctness evaluator"
 Describe what you want to measure in plain language and Alyx will write the evaluator prompt for you, generate the labels and score mapping, and save it to the Eval Hub.
* "Create an evaluator that checks if customer support responses are empathetic and provide actionable next steps"
* "Write a hallucination evaluator for my RAG pipeline"
* "Create a correctness evaluator for my project"

From a trace or span
In the tracing UI, open a trace and use **Add Trace Eval** in the trace header to score the full trace, or select a span and use **Add Span Eval** in the span details panel for span-level judges.
When you are reviewing a trace, you can also open the evaluator template picker directly from the trace slideover to start a pre-built evaluator with the current trace context. You can create and manage the saved evaluator later from the Eval Hub.

Use a pre-built template
**Use a pre-built template** if a generic quality dimension covers your needs. See the complete, product-aligned list of [Arize eval templates](#arize-eval-templates), including their default span, trace, or session scope.
1. Navigate to **New Eval Task** and select **LLM-as-a-Judge**
2. Click **Add Evaluator** and select a template
3. Set the scope - span, trace, or session
4. Configure your judge model and AI provider (use a different model than the one you're evaluating)
5. Map your trace or dataset attributes to the template variables
6. Click **Create**


Create from blank
**Create from blank** if your agent has specific criteria that generic templates can't capture.
1. Navigate to **New Eval Task** and select **LLM-as-a-Judge**
2. Click **Add Evaluator**, then **Create From Blank**
3. Name the evaluator and write a **prompt template**; see below for what makes a successful prompt template.
4. Define **output labels** (e.g. correct / incorrect) and **scores**
5. Configure the **judge model** and save

Writing a prompt template
A successful prompt template has four elements:
Define the judge's role
Open by defining the judge's role. Skip framing like "you are an expert evaluator", which rarely helps and sometimes makes results worse. Give it context instead: what system it is evaluating, what domain that system operates in, and what its task is. *"You are identifying issues with the relevance of an agent's responses so we can improve the experience for our users"* covers all three.
Explicit criteria
Avoid ambiguous or aspirational instructions like "a good response" or "a helpful answer". Focus on explicit instructions: what specific elements of a response would make it helpful? For example, for a financial agent, one criterion might be "Contains a specific buy/sell/hold recommendation", or for a customer service agent it might be "mentions specific actions to take in the UI to resolve the issue".
Also include criteria for failure: what would make the response **not helpful**? This is often drawn from inspecting traces.
Avoid over-specifying. Modern LLMs follow instructions closely, so a long list of rigid rules constrains the judge in ways you never intended. "Must contain a specific buy/sell/hold recommendation" is far stricter than "consider whether the response provides an appropriate next step", especially when the judge already knows it is evaluating a financial system.
Include labeled data
Include variable names that will be expanded at runtime into the inputs and outputs of the template, e.g. `{input}` and `{output}`. Surround these variables with clear labels to the LLM so that it understands where your instructions end and inputs and outputs begin and end. XML tags are a clear way to mark where blocks begin and end:
```
{input}
{output}
```
Don't specify the output format
Leave labels and response format out of your prompt. You define the possible responses as the evaluator's **Choices** in the UI, and AX turns them into a single tool the model must call. Models without tool calling get those instructions appended to the system prompt instead. Either way, AX handles the output spec and parsing.
## Run it over your data
An evaluator on its own doesn't score anything until you attach it to a task. See [Run evals on your data](/docs/ax/evaluate/run-evals) for online and offline tasks, sampling, and cadence.