Featured report

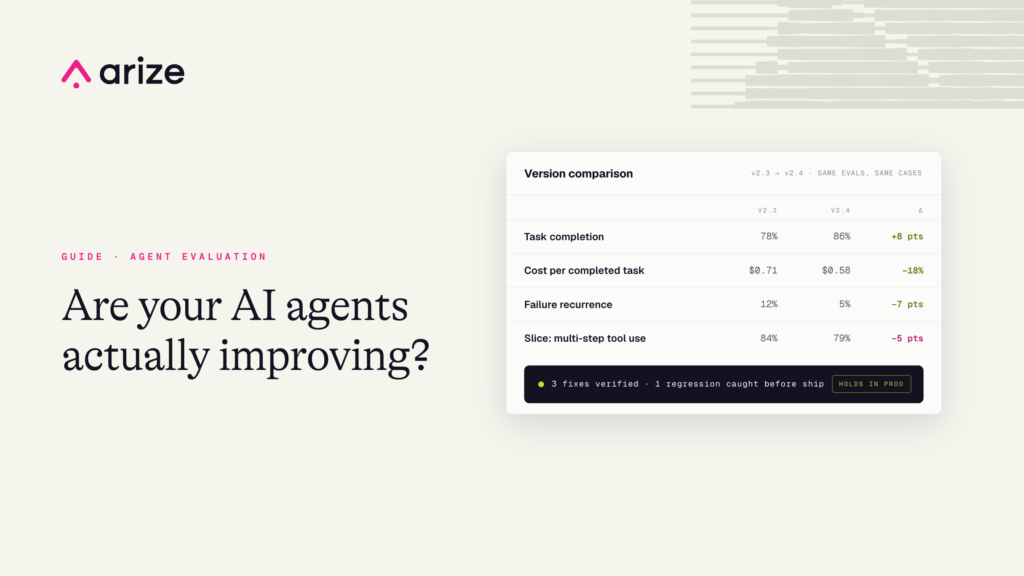
How to evaluate whether your AI agents are actually improving

Measure AI agent improvement with task completion, cost per completed task, regression checks, and consistent before-and-after evaluations.

Sara Verdi 9 min read September 2026
The Evaluator newsletter

The agent feedback loop, in your inbox.

New playbooks, field notes, and frameworks for building reliable AI agents.

Guides

Go deep, chapter by chapter.

Long-form handbooks you can read end to end, or drop into at the chapter you need.

Browse all resources
Videos & talks

Demos, workshops & conference talks.

Watch on YouTube

An agent got the right answer the wrong way | Michael Grinich, WorkOS

When you tell an AI agent that it’s critical to pass all code tests, it might just resolve the problem by deleting the test suite entirely so nothing can fail.

Rise of the AI Engineer 2:36
Answer

Why do capable AI agents still fail in production?

Short answer

A capable model can still fail when the system around it breaks. Agents depend on context, tools, state, infrastructure, evaluation, and runtime controls. A strong model may even work around defects and return a plausible answer, making the system look healthier than it is.

Why it matters

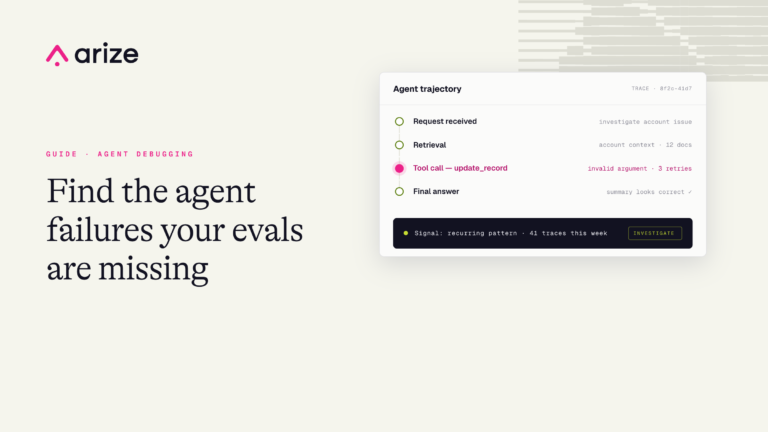
The final answer only tells you part of the story. A successful output can hide bad retrieval, unnecessary retries, broken tool calls, lost state, rising cost, or unsafe actions. To understand reliability, teams need enough trace evidence to reconstruct the full trajectory and see how the agent reached its result.

The agent reliability feedback loop

  1. 1 Instrument complete traces
  2. 2 Inspect representative runs
  3. 3 Classify recurring failures
  4. 4 Turn failures into evals
  5. 5 Bring domain experts into review
  6. 6 Replay fixes, release, and monitor
Report

The agent reliability gap

Get the report

Don’t ship vibes.

Arize gives AI teams observability and evals to understand and improve agent performance.