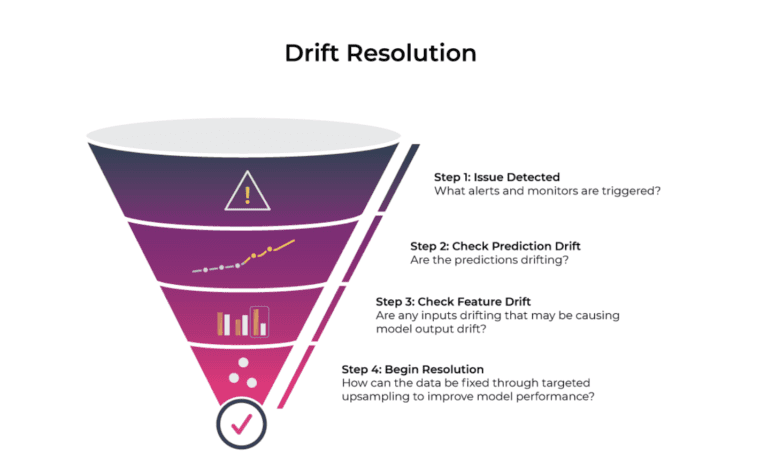
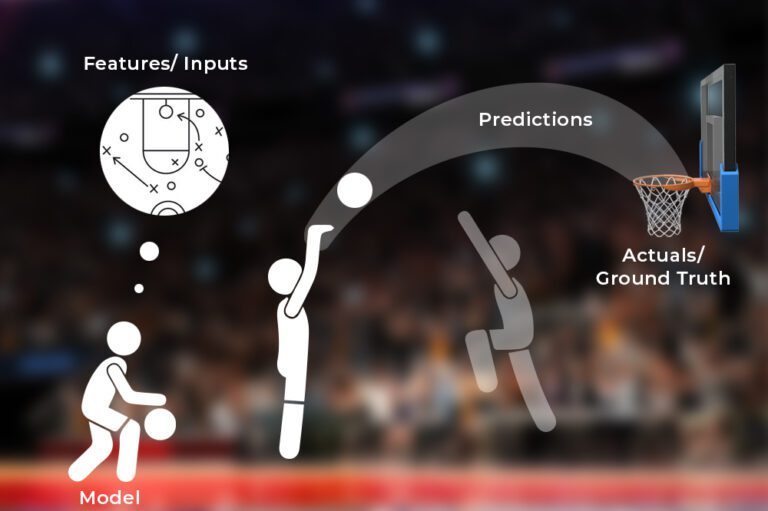
In the context of ML observability, the reference distribution can be a number of different options. The first distinction to make is that the reference distribution can be a distribution across a fixed time window (distribution does not change) or a moving time window (distribution can change). The reference is the baseline histogram or density your monitors compare against when scoring drift on features, scores, or labels.
Build better agents with Arize
Trace, evaluate, and learn. Build agents that work with Arize AX and start tracing your runs today.
Prefer open source? Try Arize Phoenix for self-hosted, open source agent observability.

Key takeaways
- Reference distribution is the baseline statistical shape used in drift and stability monitors.
- Fixed references anchor to training or a golden production month; moving references roll forward.
- Bin edges and aggregation must be frozen in model artifacts for comparable PSI over time.
- Changing reference without documentation resets historical alert context.
- Pick reference windows that represent behavior you want the model to handle well.
Fixed versus moving reference
Fixed reference uses training data, validation, or an approved production snapshot. PSI and similar scores always ask how far today diverges from that anchor. Good for regulated scorecards and long-lived models.
Moving reference compares current data to a recent trailing window (last 30 days). Detects sudden shifts relative to recent norms but erases slow gradual drift that moves both windows together.
Some teams maintain dual views: fixed for compliance, moving for ops triage.
What to store in the reference
Per-feature histogram bins or quantile edges.
Score distributions for model outputs.
Label rate baselines when label drift is monitored.
Embedding cluster centroids or sample archives for vector monitoring.
Metadata: sample counts, date range, model version, featurizer hash.
Choosing a good reference
Representative of intended deployment population, not only easiest historical slice.
Exclude incident weeks polluted by pipeline bugs unless documenting them as anti-patterns.
Large enough for stable bin counts; small references make PSI noisy.
Align with label definitions used for performance eval on the same era.
Operational practices
Version reference snapshots with model promotions. When you retrain, regenerate reference distributions from the new training window.
Do not recompute bin edges on current data each run when you need trendable PSI.
Document intentional reference refreshes after verified product changes.
Articles on model, concept, and data drift explain tying reference choice to drift type.
Lifecycle guides in AI model lifecycle management specify where reference artifacts live in the model bundle.
NLP monitoring posts such as NLP sentiment classification monitoring show cohort baselines alongside global reference charts.
Failure modes
Reference from a buggy month makes all future data look drifted.
Mixing train and test rows into reference inflates false stability.
Refreshing reference to silence alerts without fixing underlying shift.
Using different references across features in one dashboard without labeling them.
Audit trails
Store reference snapshot hashes in model registry metadata so auditors verify which baseline produced historical PSI charts.
When running A/B models, maintain separate reference distributions per champion to avoid blended drift scores.
Practitioner checklist
Before changing production settings, confirm labels, thresholds, and monitor windows match the definitions used in your last offline eval. Snapshot dashboards when incidents start so postmortems compare apples to apples.
Run slice-level reviews on high-traffic cohorts weekly even when global metrics look flat. Many failures appear first in one locale, product line, or prompt route.
Document model version, featurizer hash, and data window in every incident ticket. Future you needs that context to interpret drift charts.
When metrics disagree (offline vs online, precision vs recall), write down the business cost of each error type before picking a fix. Metrics are proxies; costs are the decision.
Share eval harness links in release notes so support and PM teams know which golden tasks must pass before they announce improvements.
Related concepts
Reference distributions pair with current distribution windows in drift dashboards. Document both window definitions in runbooks so new on-call engineers interpret alerts correctly.
FAQ
How is reference distribution different from current distribution?
Reference is baseline; current is the live window under test.
Should I use training data as reference?
Common and sensible if training matches intended deployment. Refresh when retrain changes population coverage.
When should I update the reference?
After approved retrain, verified product regime change, or scheduled scorecard refresh policies.
Can reference be synthetic?
Possible for privacy, but synthetic reference may misrepresent tail behavior; validate against real samples.
Do LLM apps need reference distributions?
Yes for prompt length, language, retrieval scores, and structured metadata feeding routers.