Overview
Quick answer: LangSmith is strongest for teams standardized on LangChain and LangGraph that want native tracing, agent trajectory and thread evaluators, LangSmith Engine, and managed deployment in one ecosystem. Arize AX is stronger for teams that need framework-agnostic OpenTelemetry and OpenInference instrumentation, built-in path, convergence, and session evaluation, continuous production monitoring and failure discovery, and VPC or on-prem deployment. If your stack is likely to span frameworks, providers, or custom agent code, Arize keeps observability and evaluation independent of the orchestration layer.
Arize and LangSmith both sit in the AI evaluation and observability category, but they were built around different centers of gravity.
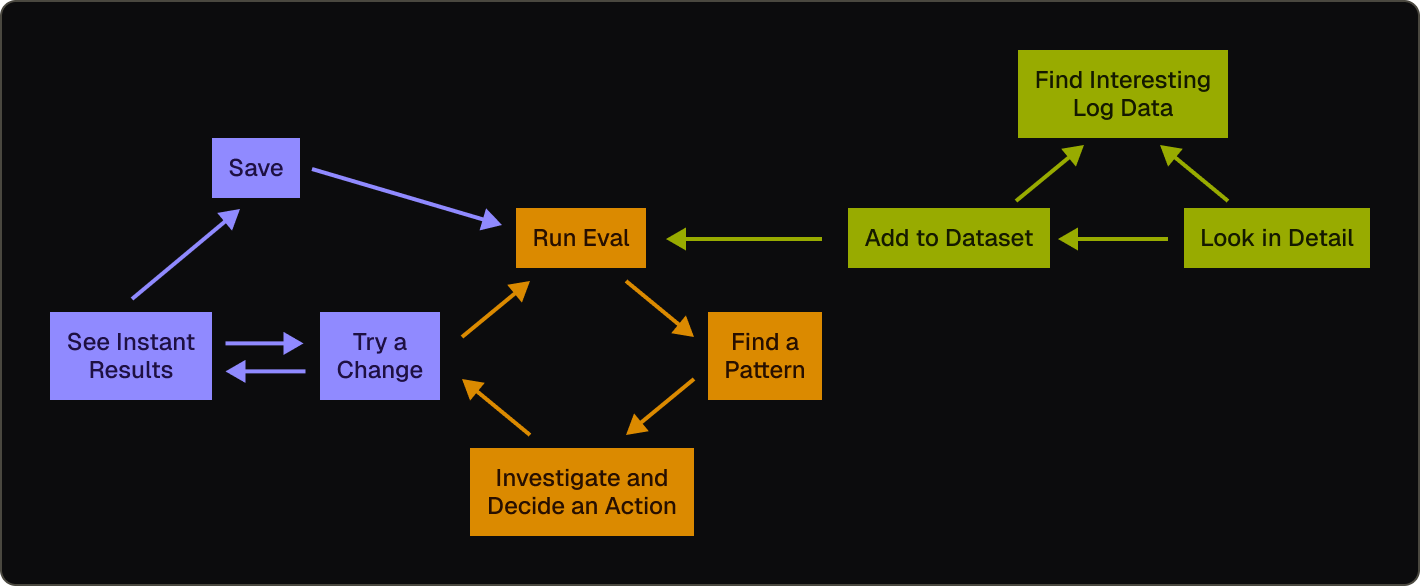
Arize is an AI engineering platform for teams shipping agents. The improvement loop starts with the trace, which records every call from the first development run through production, evaluates behavior at the span, trace, and session level, surfaces failure patterns the team didn’t predefine, and feeds those real failures back into datasets, experiments, and regression coverage for the next release. The platform works the same way whether the agent runs on LangGraph, a different framework, direct provider calls, or a custom stack.
LangSmith is the observability, evaluation, and deployment platform from the LangChain team. Its tightest loop lives inside the ecosystem: instrument a LangChain or LangGraph application with very little configuration, inspect run trees and graph state, run offline or online evaluators including trajectory and thread-level evaluators, use LangSmith Engine to analyze recurring failures, and deploy through the managed platform. The product also accepts OpenTelemetry from applications outside LangChain, but its data model and highest-leverage workflows remain LangChain- and LangGraph-shaped.
This was last updated in August 2026. Here’s a side-by-side look at the core assets of each tool:
For a broader view of the market, see our broader Arize alternatives comparison.
| Capability | Arize | Langsmith |
|---|---|---|
| Philosophy | Observability-first; evaluation across the full lifecycle on open standards | Framework-native; tracing, evals, and deployment built around LangChain and LangGraph |
| Strongest phase | Production: live traces, sessions, online evals, monitoring, root cause | Development inside the ecosystem: run trees, LangGraph Studio, prompt work, framework-native evals |
| Agent debugging | Trajectory, path, and session-level evaluation; graph views for multi-agent systems on any framework | Trajectory evaluators and thread-level online evals, plus run trees and LangGraph graph views; deepest inside LangChain and LangGraph. |
| Issue discovery | Alyx assistant plus Signal, which continuously reviews production traces and surfaces emerging failure clusters | LangSmith Engine (Beta) clusters recurring issues, diagnoses root causes, proposes fixes and evaluators, and creates dataset examples; dashboards and alerts are also available |
| Instrumentation | OpenTelemetry and OpenInference native; auto-instrumentation across 30+ frameworks and providers | Near-zero config for LangChain and LangGraph; accepts OpenTelemetry, then maps GenAI, OpenInference, TraceLoop, and generic LLM attributes into LangSmith run fields |
| Self-hosting | Arize AX deploys in your VPC or fully on-prem, control plane included; Phoenix also runs fully self-contained | Cloud on paid plans; hybrid and fully self-hosted options on Enterprise. Hybrid keeps the control plane in LangChain Cloud; full self-hosting runs in your infrastructure |
| Pricing model | Arize AX has free and self-serve tiers priced on spans and data volume, no per-seat charges; Phoenix is open source and free | Developer: $0 with 5k base traces; Plus: $39 per seat with 10k base traces; additional trace retention and LCU/LSU-metered products add usage costs |
For teams building primarily inside LangChain and LangGraph, LangSmith offers a highly integrated path from tracing through evaluation and deployment. For teams that want the observability and evaluation layer to stay stable while frameworks, providers, and custom services change, Arize AX is the stronger fit.
Compare AI observability platforms
Explore AI observability and AI engineering platforms across tracing, evaluation, experimentation, and continuous improvement.
Why teams choose Arize
One record from development to production Most agent evaluation tools split the AI lifecycle in half. Offline experiments…
See the competitionBraintrust
Compare Arize and Braintrust for AI observability, agent evaluation, tracing, production monitoring, deployment, and enterprise scale.
See the competitionLangfuse
Compare Arize Phoenix vs. Langfuse on open source tracing, agent evals, self-hosting, and pricing, plus when teams add…
See the competitionWhat Arize does well
- The observability foundation is complete. Traces, sessions, retrieval calls, tool calls, cost, and quality signals all land in one place, with dashboards, monitors, and alerting on top, so the platform answers “what happened” before the team starts asking “was it good.”
- Instrumentation lives on open standards. OpenTelemetry and OpenInference support means one instrumentation step covers 30+ frameworks and providers, including LangChain and LangGraph, so adopting a new framework never means adopting a new observability stack.
- Evaluation runs everywhere, not just in experiments. The same evaluators work in offline experiments, CI, and continuously against live traffic, and agent-native evals cover trajectories, path convergence, tool selection, and session-level task completion rather than only final outputs.
- Failure discovery is built in. Signal continuously reviews production traces and surfaces emerging failure patterns the team did not predefine. Alyx, the in-platform AI engineering agent, helps investigate those issues and propose next steps.
- There’s a free path with no ceiling on open source. Phoenix self-hosts in your own environment with no feature gates or usage caps. Teams move to Arize AX when they want managed infrastructure, governance, and production scale. AX Free and Pro include hosted tracing and evals with span, ingestion, retention, and Signal limits; Enterprise removes those ceilings and adds VPC / on-prem deployment.
LangSmith and Arize overlap most in tracing and offline evaluation, and they separate on framework dependence and production depth.
What LangSmith does well
- Tracing inside the ecosystem is nearly free. One environment variable turns on tracing for a LangChain or LangGraph application, and the run trees, node graphs, and state at each step all line up with almost no glue code.
- The development-to-deployment path is connected. LangGraph Studio supports visual debugging with breakpoints and step inspection, and the managed deployment platform takes the same agent to production, with Fleet and Agent Builder extending the operational surface.
- The eval toolkit reaches agent workflows. LangSmith supports datasets, offline and online evaluators, human annotation, pairwise comparison, trajectory evaluation for tool-use paths, and multi-turn online evaluators at the thread level. That makes it more capable than a simple output-scoring system, especially for LangGraph applications.
- The ecosystem keeps compounding. LangChain and LangGraph have broad documentation and examples, LangSmith accepts OpenTelemetry telemetry, and the product connects tracing, evaluation, deployment, and newer agent operations in one developer workflow.
- Automated failure analysis is now part of the product. LangSmith Engine (Beta) periodically reviews traces, finds recurring issue clusters, diagnoses root causes, proposes fixes and evaluators, and creates examples for regression datasets. It is the closest LangSmith analogue to automated production failure discovery.
How Arize and LangSmith differ across the AI agent lifecycle
LangSmith is strongest when the application lives inside its ecosystem: instrument with minimal configuration, debug LangGraph state and runs, evaluate against datasets and production threads, and deploy through the managed platform. Real production architectures often grow beyond one abstraction layer, with direct provider calls, custom retrieval services, MCP tools, multiple runtimes, and purpose-built application code. Coding agents can accelerate that shift by making custom orchestration easier to generate and maintain, which raises the value of an observability layer that survives framework choices instead of depending on them. Frameworks will remain useful; the strategic question is whether your telemetry and evaluation system stays intact when the architecture changes.
Production also asks operational questions that a framework-native debugging surface wasn’t designed to answer:
- Which sessions failed, and how many users did this touch?
- Did the failure come from retrieval, the model, a tool call, routing, or stale context?
- Why did latency spike, whether from retries, longer outputs, or a slow external tool?
- Is this concentrated in one segment, one customer, one agent path?
- Is it recurring right now, and will we know whether it comes back after the fix?
This is where the two platforms diverge. LangSmith is no longer only a manual dashboard surface: LangSmith Engine (Beta) analyzes traces on a scheduled cadence, clusters recurring issues, diagnoses likely root causes, proposes fixes and evaluators, and can create ground-truth dataset examples. It closes more of the production feedback loop than earlier versions of LangSmith did. The architectural tradeoff is that the tightest tracing, debugging, evaluation, and deployment experience still follows LangChain and LangGraph concepts.
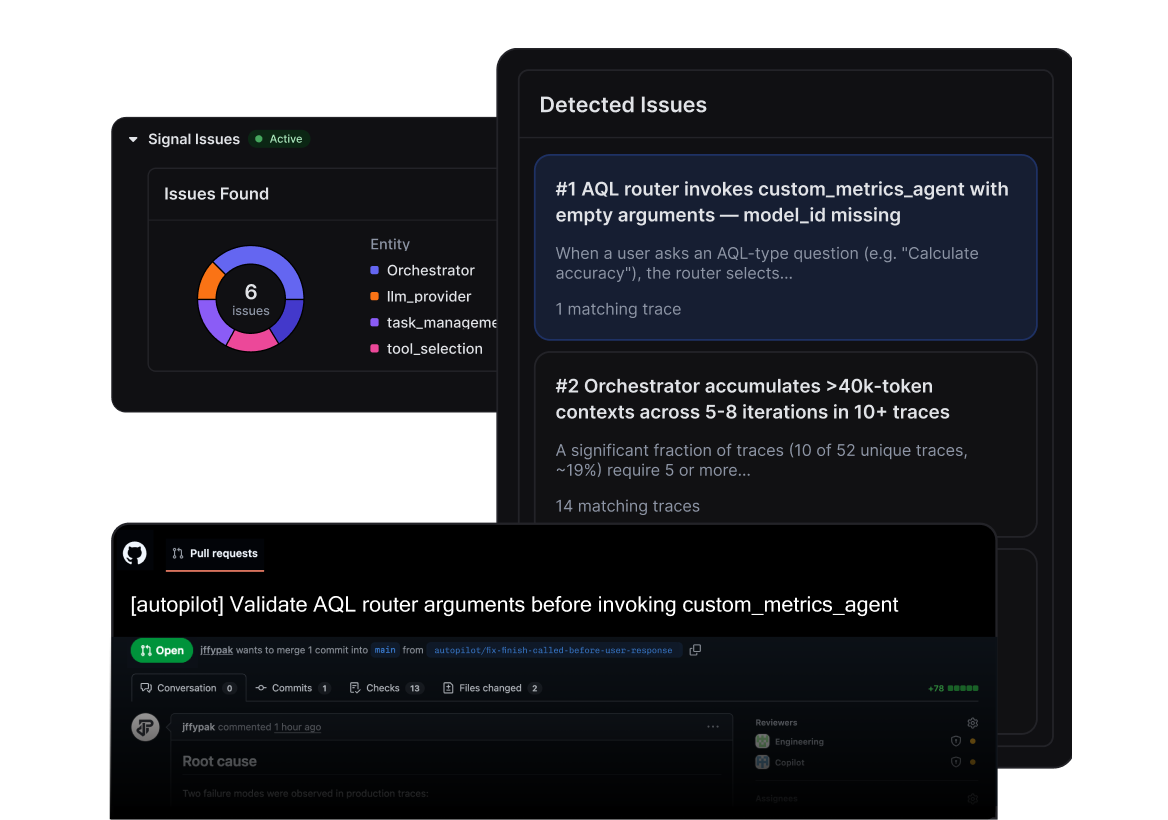
Arize gives you a discovery surface built on a continuous record: every call is traced from development through production regardless of framework, Signal continuously reviews traffic, emerging failure patterns are clustered and surfaced, and the eval suite grows from what is actually breaking rather than only what the team predicted. Signal is the always-on worker that reviews production traces and groups related failures into investigation reports. Agent-as-a-Judge lets teams describe what good behavior looks like so an agentic harness can inspect live traces, identify the relevant spans, classify issues, and create labels that feed monitoring, evaluation, and experimentation going forward. The eval signal keeps pace with production instead of waiting for someone to check a dashboard.
Head-to-head comparison
Observability: seeing what happened
Arize was built for observability first. Arize AX captures traces, sessions, spans, tool calls, retrieval calls, latency, token usage, and cost, with dashboards, alerting, and monitors on top: a full picture of agent observability rather than a per-framework debugging view. Instrumentation is OpenTelemetry and OpenInference native, with auto-instrumentation across 30+ frameworks and providers including OpenAI, Anthropic, Bedrock, LangGraph, LangChain, LlamaIndex, CrewAI, the OpenAI Agents SDK, and DSPy. Teams already on LangGraph keep their framework and instrument it the same way as everything else, so the observability layer stays neutral as the stack evolves. Because the data lives on open standards, it stays portable. Arize also supports voice agents natively, inspecting audio sessions alongside transcripts, analyzing interruptions and time-to-first-audio, and running evals directly against audio interactions.
LangSmith approaches observability from the framework side. Tracing for LangChain and LangGraph is tightly integrated, with detailed run trees and graph-oriented views, and LangSmith now accepts OpenTelemetry telemetry from any OTel-compatible application. Its OTel documentation shows incoming GenAI semantic conventions, OpenInference, TraceLoop, and generic LLM attributes being mapped into LangSmith’s internal run fields. That provides useful ingestion interoperability, but it is different from keeping the observability data model itself centered on open AI telemetry conventions. For mixed-framework systems, teams should test not only whether traces can be sent to LangSmith, but whether the attributes, evaluator outputs, and downstream workflows they rely on remain portable outside the product.
Evaluability: measuring whether it was good
Both platforms take evaluation seriously. LangSmith supports datasets, built-in and custom evaluators, LLM-as-judge scoring, annotation queues, pairwise comparison, trajectory evaluators for agent tool-use paths, and multi-turn online evaluators that score threads in production. That covers both pre-release testing and important classes of agent evaluation.
Arize matches that workflow, including datasets, experiments, annotations, LLM-as-judge, and human labeling queues, and extends it in three directions:
- Online evals at production scale. Evaluators run continuously against live traffic, not only against experiments, across customers like Uber and Booking.com.
- Agent-native evals on any stack. LangSmith now supports trajectory and thread-level evaluation, so the distinction is not whether it can evaluate agents. Arize differentiates on built-in path, convergence, tool-selection, and session analysis tied to the same production traces across frameworks. Path evals measure route quality, convergence evals catch loops and unnecessary backtracking, session evals measure multi-turn behavior, and graph views expose handoffs and cycles without requiring the application to be built on LangGraph.
- Versioned, reusable evaluators. The Evaluator Hub gives teams version history with commit messages over evaluators, so the same judge can run in offline experiments, CI, and production monitoring.
Actionability: getting from failure to fix
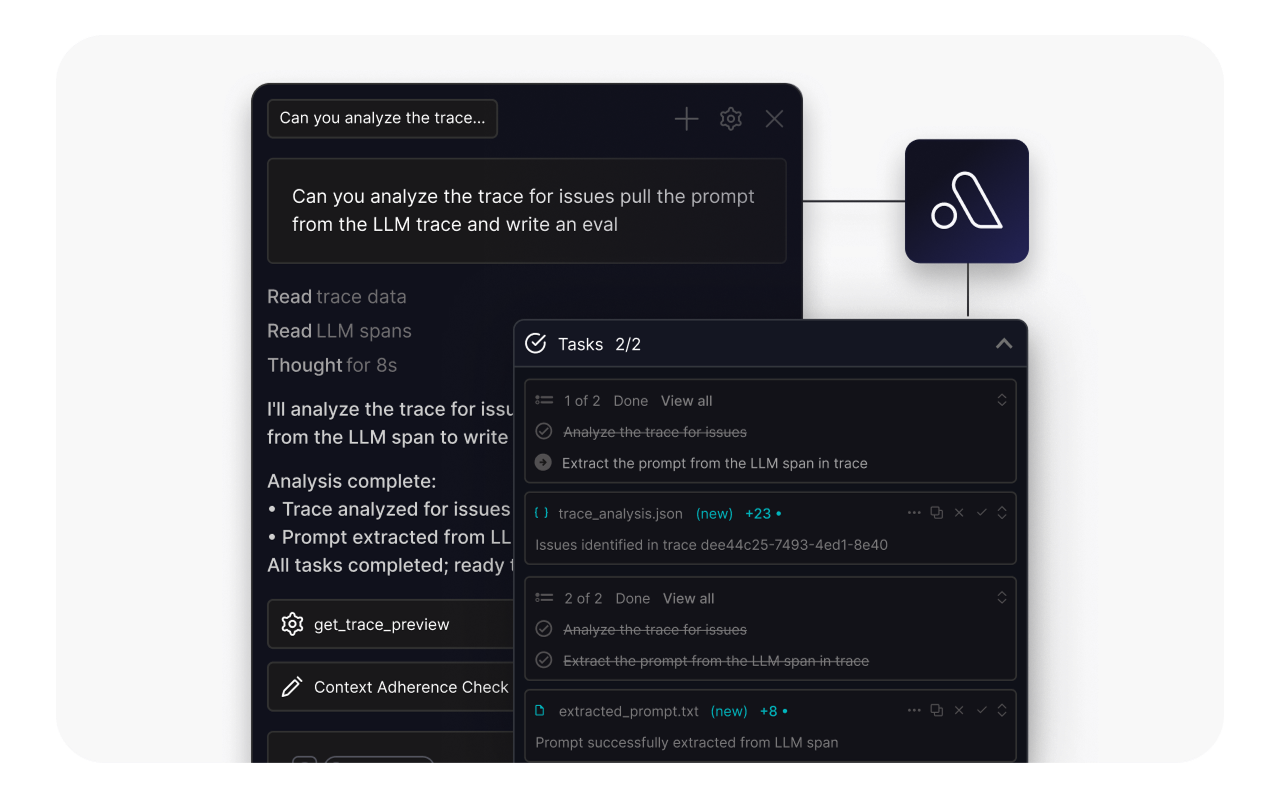
Arize is built for root cause. Signal surfaces recurring production failure patterns. Alyx, the in-platform AI engineering agent, investigates traces, proposes evaluators (with human confirmation before changes apply), and helps debug directly, while alerting routes to PagerDuty and Slack. The Arize CLI and Skills let teams run the same workflows from the terminal or from coding agents like Claude Code and Cursor, so debugging production issues lives in the same loop as writing the fix. The trace-to-dataset workflow closes the circle: a failed session becomes a labeled example, a dataset item, and a regression test.
LangSmith now closes more of the failure-to-fix loop with LangSmith Engine (Beta). Engine periodically analyzes production traces, groups recurring issues, investigates root causes, proposes fixes and evaluators, and creates dataset examples that can be used for regression testing. The workflow is compelling for LangChain and LangGraph teams, but it is a separately metered Engine service and its strongest remediation and deployment path remains inside the LangChain ecosystem. Teams comparing automated failure discovery should evaluate cadence, cost, framework coverage, and how easily a discovered issue becomes a durable monitor and regression test.
Operability: fitting how your company runs AI
This is where structural differences matter most for enterprise buyers.
Self-hosting
Arize offers a genuinely self-contained path. Arize AX deploys to one Kubernetes cluster in your VPC or fully on-prem, control plane included, with SOC 2 and GDPR support on the platform, plus HIPAA, RBAC, and audit controls on Enterprise. Phoenix also runs entirely in your environment, whether locally, in Docker, or in your cloud, with no SaaS control plane. That same self-contained deployment model is used in regulated environments, including U.S. Navy / DIU MLOps programs where Arize contributed model-monitoring capabilities.
LangSmith can be fully self-hosted, but only on Enterprise. In the fully self-hosted option, the LangSmith platform runs inside the customer environment and the customer operates the full stack. LangSmith also offers an Enterprise hybrid option that keeps the control plane in LangChain Cloud while the data plane runs in the customer VPC. The practical distinction is therefore not “self-hosted versus not self-hosted”; it is whether a team needs a self-serve open-source option, what components it is willing to operate, and which plan is required. Arize Phoenix provides a self-hosted open-source path, while Arize AX supports VPC and on-prem Enterprise deployments.
Data portability
Arize is built on OpenTelemetry and the OpenInference semantic conventions, so trace data remains in an open format you can move.
LangSmith supports OpenTelemetry ingestion, but ingestion compatibility and data-model portability are different questions. LangSmith’s OTel integration maps standard GenAI attributes, OpenInference attributes, TraceLoop attributes, and generic LLM attributes into LangSmith run fields. Teams can send OTel traces into the platform, but should validate how custom attributes, evaluations, and product-specific metadata export if they later change observability backends.
Cross-functional work
Production AI failures are rarely just a development problem, since support sees the tickets, product sees the abandonment, and finance sees the token spend. Arize AX gives each function a view over the same quality signal, including dashboards, labels, cost attribution, and recurring-failure reports, while teams work from raw traces and evaluator outputs. LangSmith’s surfaces are built primarily for the developer working inside the framework loop.
Compare pricing at your expected production volume
Both platforms have free entry points and usage-based charges, but the billing dimensions differ. Arize centers hosted pricing on telemetry volume without per-seat charges. LangSmith combines included trace allowances with per-seat pricing on Plus, trace retention charges, and separate LCU/LSU metering for products such as Engine, Deployment, Fleet, and Sandboxes.
Arize
- Phoenix: free and self-hosted with no feature gates or usage caps, covering tracing, evals, datasets, experiments, and prompt management.
- AX Free: hosted tier that includes Alyx and the evaluation suite at $0, with 25k spans/month, 1 GB ingestion, 15-day retention, Signal limited to 10 issues/month, and a choice of data region.
- AX Pro: self-serve tier from $50/month with 50k spans/month, 10 GB ingestion, 30-day retention, Signal limited to 25 issues/month, overage pricing so data keeps flowing past the cap, and no per-seat charges.
- AX Enterprise: custom pricing for production scale, governance, ADB Data Fabric, VPC / on-prem deployment, HIPAA, unlimited Signal, and support SLAs.
The structural difference is that Arize prices on span and data volume with no per-seat charges, so the bill tracks how much the system runs rather than how many people look at it. Adding reviewers, annotators, or stakeholders from other teams costs nothing, and adding evaluation depth to an agent doesn’t multiply the bill. For teams starting out, Phoenix removes the pricing question entirely.
LangSmith
- Developer: $0, with 1 seat, 5,000 base traces per month, and 14-day base trace retention. Usage beyond the included traces can continue on pay-as-you-go billing once a payment method is configured.
- Plus: $39 per seat per month, with 10,000 base traces included, paid usage beyond the allowance, and access to products including Deployment and Engine. Base traces have 14-day retention; traces upgraded to extended retention are kept for 400 days and cost more. Feedback, annotation, and some evaluation workflows can trigger extended-retention upgrades.
- Enterprise: custom annual pricing, with hybrid and fully self-hosted deployment options plus enterprise identity, authorization, retention, and support controls.
The production cost model has several independent dimensions. Seats grow with the number of people using Plus, traces grow with traffic and retention, and Engine, Deployment, Fleet, and Sandboxes can add LCU or LSU usage. LangSmith currently prices LCUs at $1.50 and estimates a typical Engine run at roughly 5 to 30 LCUs depending on workload; Engine is scheduled every six hours by default when enabled. A 15-person Plus team therefore starts at $585 per month in seat fees before usage. Teams should model the combined bill at expected team size, traffic, retention, evaluator activity, and Engine or deployment usage rather than comparing only the free allowances.
When LangSmith is the right choice
LangSmith fits well when the team is committed to LangChain and LangGraph and wants tracing, agent evaluation, Engine-based failure analysis, and deployment in one ecosystem. The near-zero-config developer path and graph-native debugging are difficult to beat inside that stack. Enterprise teams can also choose hybrid or fully self-hosted deployment. The tradeoff to model is how much of the long-term architecture you want coupled to the framework ecosystem, especially if direct provider calls, custom services, or code generated and maintained by coding agents become a larger share of the application.
When Arize is the right choice
Choose Arize when:
- You want one record from development to production. Traces, sessions, online evals, monitoring, alerting, and root-cause workflows run on the same data before and after release, so nothing depends on what someone remembered to stage.
- Your stack is bigger than one framework (or likely to become bigger). OTel-native instrumentation covers LangGraph alongside 30+ other frameworks and providers, so the observability layer stays neutral while the architecture evolves. That matters as teams mix frameworks with direct SDK calls, MCP tools, custom services, and more code assembled with coding agents.
- You need failure discovery, not just dashboards. Signal continuously reviews production traffic, surfaces issues you did not predefine, and turns them into labeled, monitorable patterns.
- You need real deployment control. Arize AX supports VPC and on-prem without a framework dependency in your production infrastructure, and Phoenix gives you a fully contained open source option.
- You’re scaling the team, not just the traffic. Pricing on data volume with no per-seat charges means annotators, reviewers, and cross-functional stakeholders join without changing the bill.
- You operate at scale. Arize’s platform is built to handle trillion-span monthly volumes, with a heritage in ML monitoring, including drift and embeddings, that LLM-native tools don’t match.