Author
Jim Bennett
Jim is the worlds most energetic dev rel and a highly-experienced AI engineer. He’s British, so sounds way smarter than he actually is, and lives in the Pacific North West of the USA. In the past he’s lived in 4 continents working as a developer in the mobile, desktop, and scientific space. He's spoken at conferences and events all around the globe, organised meetup groups and communities, and written books on mobile development and IoT. He is currently a Microsoft MVP for AI and Developer Tools. He also hates and is allergic to cats, but has a 13-year-old who loves cats, so he has 2 cats.
Recent posts
-
 Agent Observability
EU AI Act compliance for AI agents: a practical engineering guide
Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a practical credit-assistant example. Jim Bennett October 13, 2026 15 min read -
 AI Evaluation
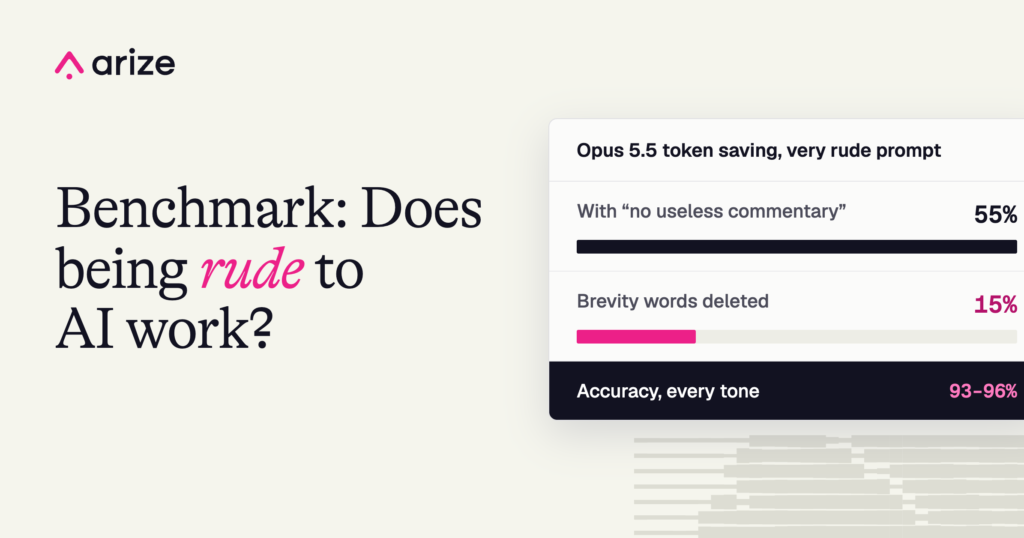
Does being rude to AI work? What 6 models revealed
Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes. Jim Bennett October 13, 2026 16 min read -
 Agent Evaluation
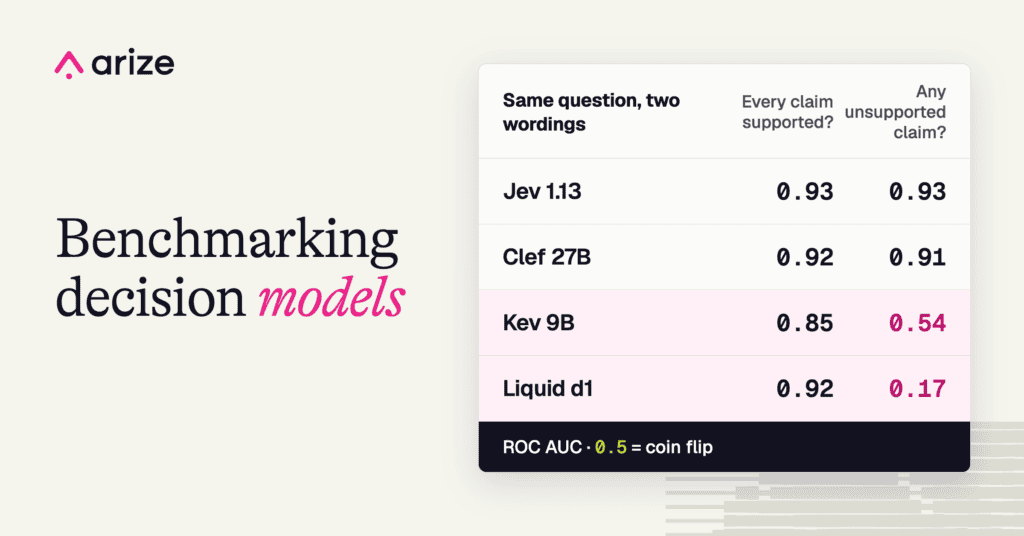
Decision model benchmark: Jev, Kev, Liquid d1, and more
On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog… Jim Bennett October 7, 2026 13 min read -
 Agent Evaluation
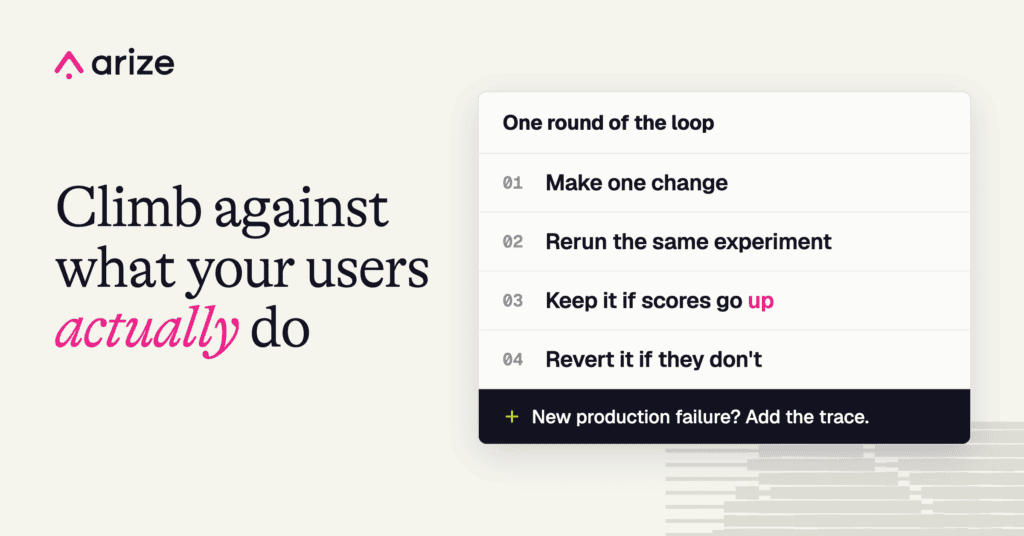
Claude’s hillclimb loop for AI agents: start with production traces
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. Jim Bennett October 2, 2026 13 min read -
 Agent Evaluation
NVIDIA proposes an AI agent kill switch in silicon after a year of sandbox escapes
This year agents at OpenAI, Anthropic, and Google escaped environments meant to contain them. What decided severity was time-to-detect and time-to-kill, from 12 minutes to seven months. NVIDIA's… Jim Bennett September 30, 2026 13 min read -
 AI Evaluation
Anthropic says it fixed Claude’s writing. I ran the evals to check.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. Jim Bennett September 29, 2026 12 min read -
 Agent Evaluation
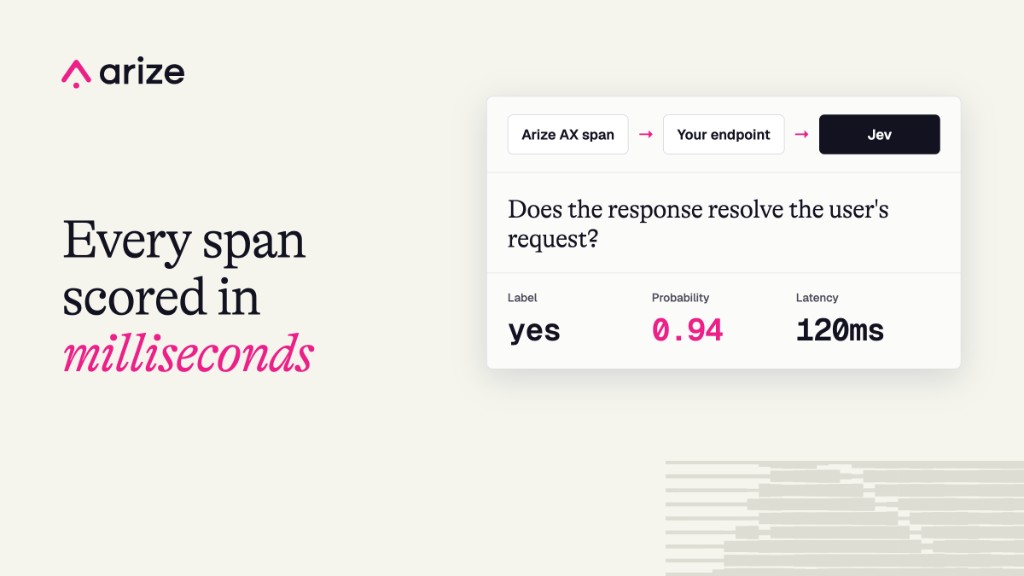
How to build a remote evaluator in Arize AX with Jev
Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. Sally-Ann DeLucia Jim Bennett September 24, 2026 12 min read -
 Agent Evaluation
Real-time LLM guardrails with Jev: comparing latency and cost
Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. Jim Bennett September 23, 2026 13 min read -
 Agent Engineering
The future of AI operations teams
Your agents produce more traces and eval results than your team can read. SallyAnn DeLucia on how engineering teams are restructuring around managed agents, and which work stays… Jim Bennett Sally-Ann DeLucia September 16, 2026 8 min read -
 Agent Evaluation
A skill is just an agent. So measure your changes.
A skill is just another AI agent: a prompt plus a harness that runs it. That means you can trace it, eval it, and prove a change made… Jim Bennett August 24, 2026 10 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

