Author
Laurie Voss
Recent posts
-
 Agent Engineering
Why Anthropic replaced Git, and whether you’ll need to
Anthropic built Scion for an enormous monorepo handling more than 30,000 daily merges. Most teams can keep using Git, but AI coding agents are changing how source control,… Laurie Voss October 19, 2026 11 min read -
 Agent Evaluation
AI agent permissions: Why agents don’t know what you’re allowed to do
AI agent permissions determine what an agent is allowed to do on someone’s behalf. As agents get more powerful, we’re running into a basic problem: a model can’t… Laurie Voss October 15, 2026 8 min read -
 Agent Engineering
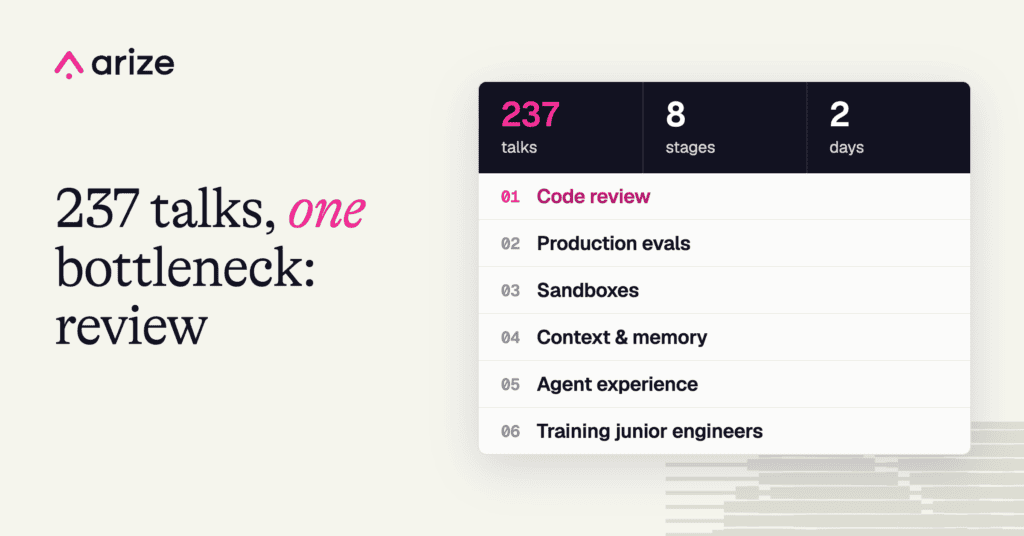
What everyone was talking about at WeAreDevelopers World Congress North America
After 237 talks across eight stages, code review emerged as the bottleneck for AI-generated code. Here are the production eval, sandbox, context, and agent experience themes that kept… Laurie Voss September 29, 2026 16 min read -
 Agent Engineering
Are agent harnesses dying? What harness distillation changes
Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. Laurie Voss September 29, 2026 9 min read -
 Agent Evaluation
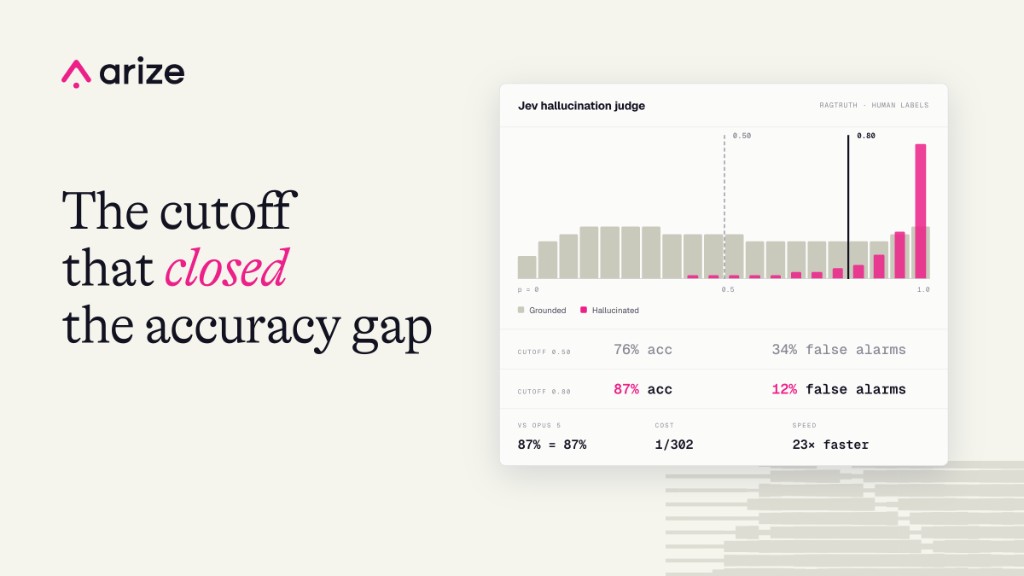
Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks
We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. Laurie Voss September 23, 2026 11 min read -
 Agent Engineering
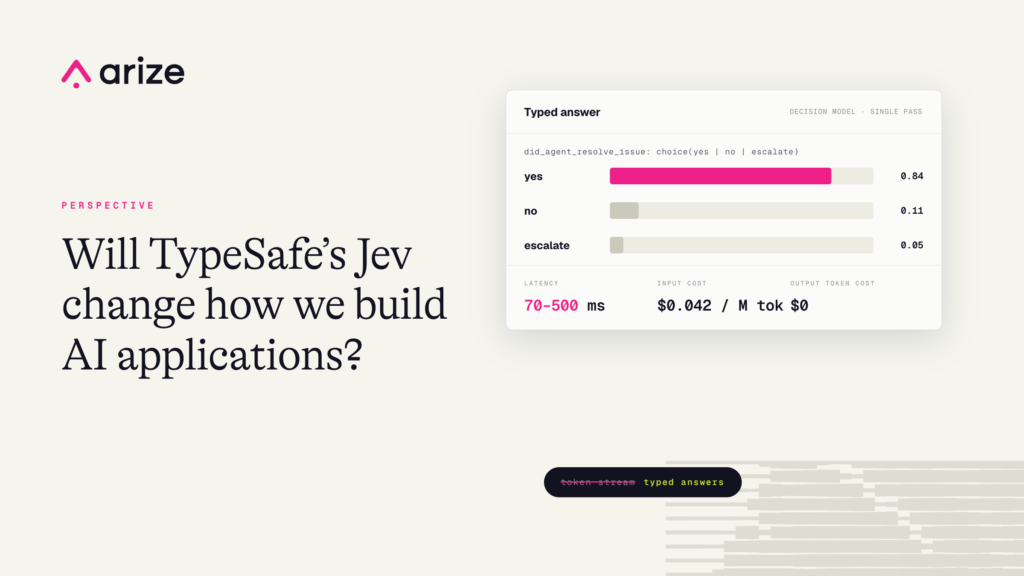
TypeSafe’s Jev: Can decision models replace LLM judges?
TypeSafe’s Jev classifies, scores, and routes without generating text — up to hundreds of times cheaper than an LLM judge. What that changes for evals, confidence routing, and… Laurie Voss September 18, 2026 10 min read -
 Agent Engineering
Agent cost management is about more than the model
Every LLM call your application makes costs money, and agentic applications make a lot of LLM calls. Arize AX now ships a Cost Agent that reads traces, ranks… Laurie Voss September 1, 2026 8 min read -
 Agent Evaluation
Is your coding agent uploading all your code?
After Grok Build was caught uploading entire Git repos, we read the privacy docs for Claude Code, Codex, Cursor, GitHub Copilot, and Grok Build to compare what code… Laurie Voss August 20, 2026 7 min read -
 Agent Evaluation
Where agent evals are going: Agent-as-a-Judge
Agents changed what failure looks like, and the evaluation layer has to change with them. Why agent-as-a-judge is moving from research paper to production eval stack. Laurie Voss August 19, 2026 8 min read -
 Agent Engineering
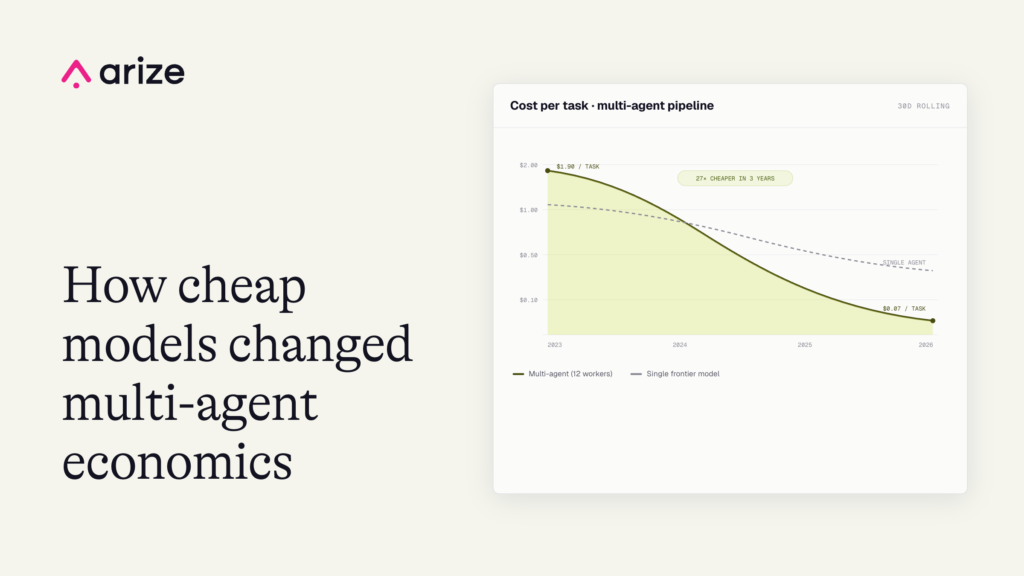
How cheap models changed multi-agent economics
Orchestrator-executor just became the smart default for production agents: an expensive model plans, cheap models execute, and cost per completed task decides the roster. Laurie Voss August 7, 2026 8 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

