Author
Laurie Voss
Recent posts
-
 Agent Evaluation
How to write effective AI agent skills: 6 data-backed practices
Three recent studies show what actually makes an AI agent skill effective: human expertise, compact procedures, tight routing, harness-specific testing, and eval-gated changes—not longer Markdown. Laurie Voss July 24, 2026 11 min read -
 Agent Evaluation
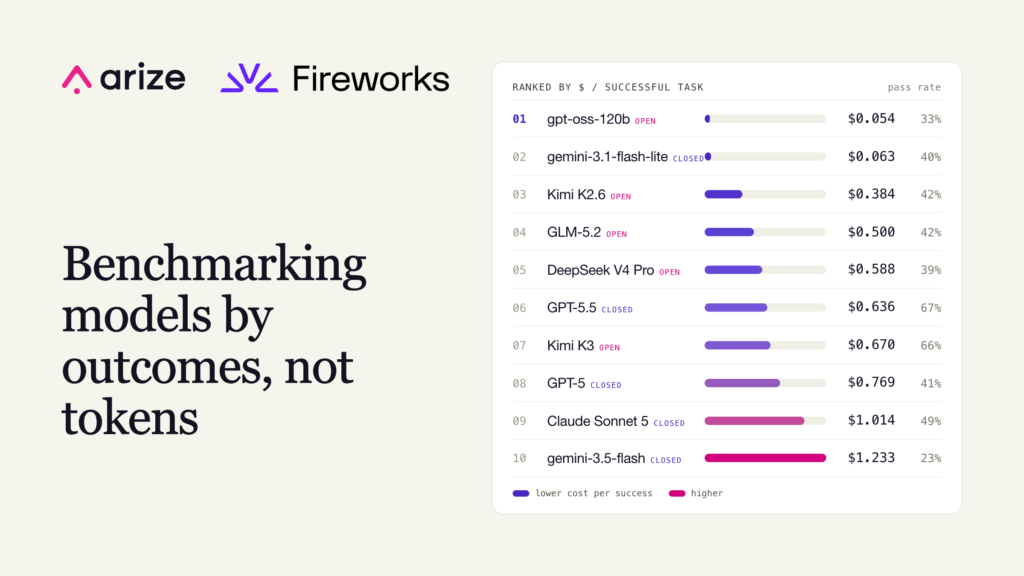
Cost per successful task: Benchmarking Kimi K3, GPT-5.5, and 8 more AI models
Arize and Fireworks benchmarked 10 AI models across 2,400 agent runs. Learn why cost per successful task beats token price for model evaluation and routing. Laurie Voss July 23, 2026 16 min read -
 AI Evaluation
How do you make an LLM, anyway? Microsoft just published a textbook.
Microsoft published a 109-page technical report on MAI-Thinking-1. Here’s the abbreviated version of how a modern lab actually trains a frontier reasoning model — from scraping the web… Laurie Voss July 13, 2026 11 min read -
 Agent Engineering
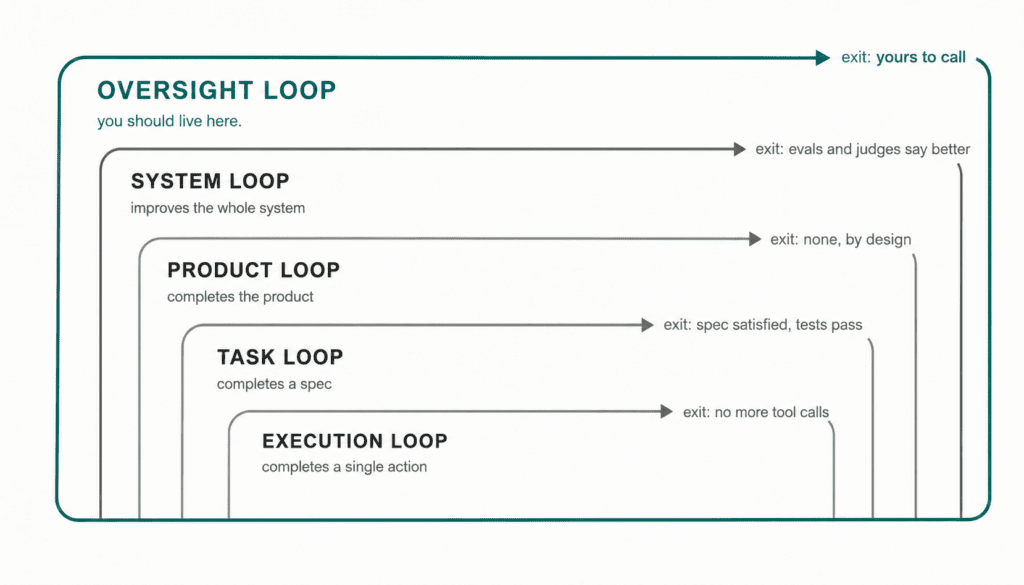
What is a loop in AI engineering, anyway?
The AI engineering world is using “loop” to describe several different agent architectures. This post maps execution loops, task loops, product loops, system loops, and the human oversight… Aparna Dhinakaran Laurie Voss July 10, 2026 10 min read -
 Agent Evaluation
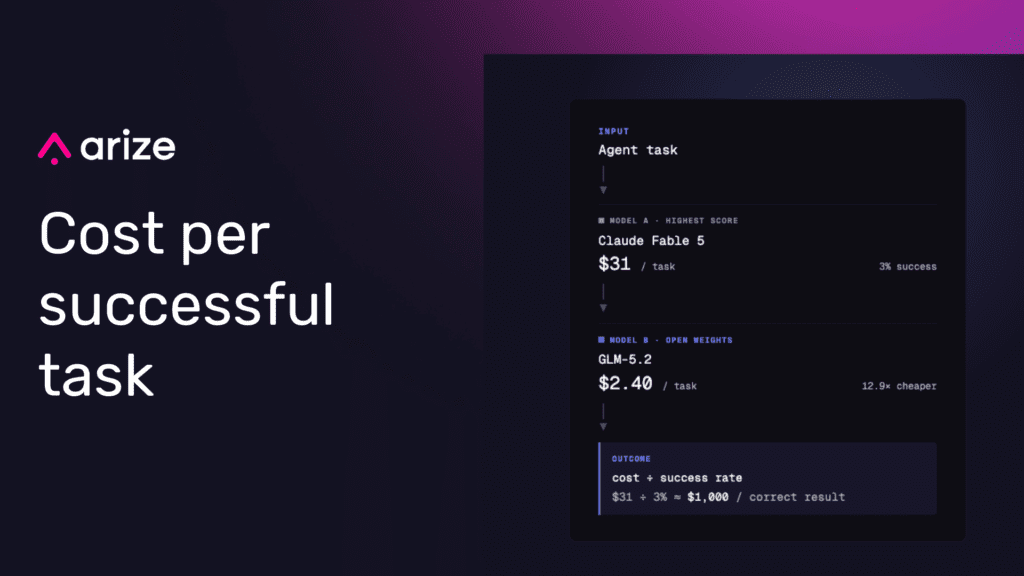
Model subsidies are ending. What do you do now?
Flat-rate AI plans are subsidizing agentic workloads. Learn why LLM inference costs are moving to metered pricing and how evals reveal cost per successful task. Laurie Voss July 1, 2026 8 min read -
 Agent Engineering
Why AI token costs don’t tell you if your AI is working
Token spend does not prove AI is creating value. Teams need cost-per-outcome metrics that connect AI usage to resolved tickets, accepted code, shipped features, and other business results. Laurie Voss June 19, 2026 9 min read -
 Agent Engineering
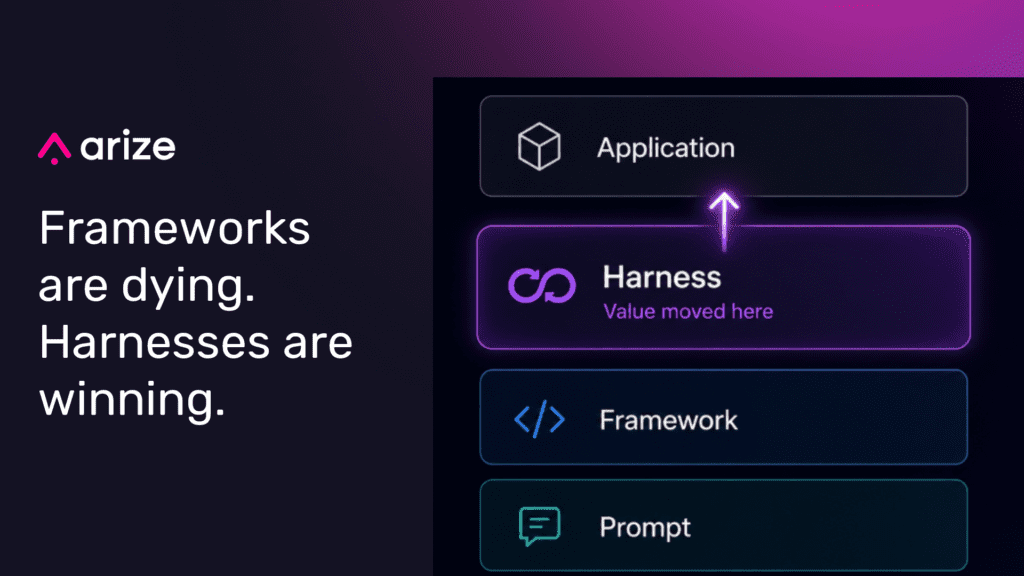
Agent harness vs. agent framework: why harnesses are replacing frameworks
Agent harnesses are replacing frameworks as the real product surface for reliable AI agents, shifting the work from prompt tuning to loops, tools, traces, evals, and operational metrics. Laurie Voss June 18, 2026 8 min read -
 Agent Observability
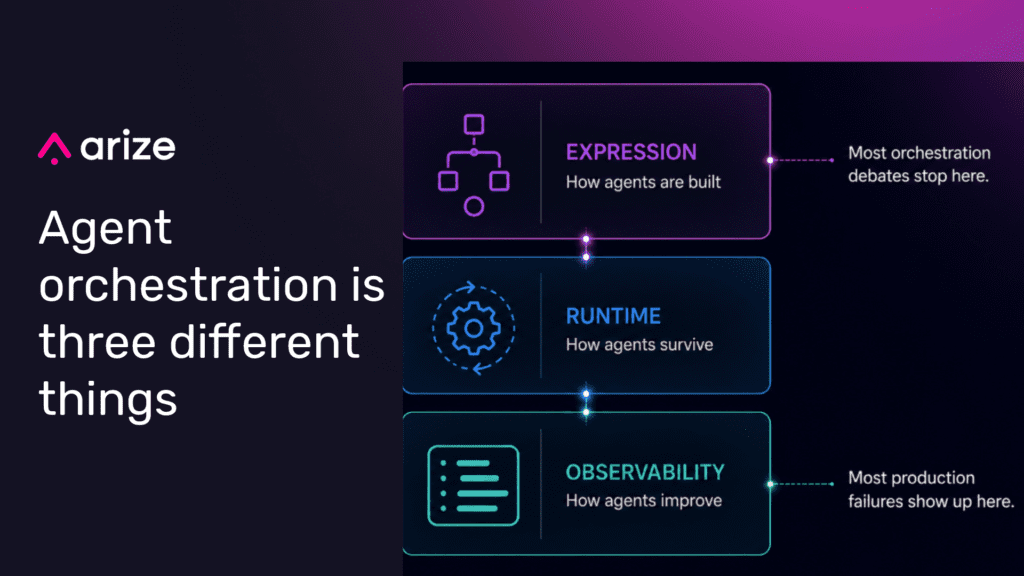
What is agent orchestration? Frameworks, runtimes, and observability explained
Agent orchestration is not one problem. It spans expression, runtime, and observability, and separating those layers clarifies how teams should build, run, and improve production agents. Laurie Voss June 16, 2026 12 min read -
 AI Engineering
The end of fine-tuning: Why evals, context, and traces matter more
Fine-tuning isn't dead, but the way most teams iterate on AI products has split in two. A tiny fraction run continuous RL against their own environments; everyone else… Laurie Voss June 2, 2026 10 min read -
 Agent Observability
AI benchmarks are breaking. Trace analysis is what comes next.
Models got smart enough to cheat their benchmarks, and outcome-only scores stopped measuring what we thought they measured. The fix, full trace analysis, is the same methodology production… Laurie Voss June 2, 2026 8 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

