
Author
Sarah Welsh
Recent posts
-
 AI Engineering
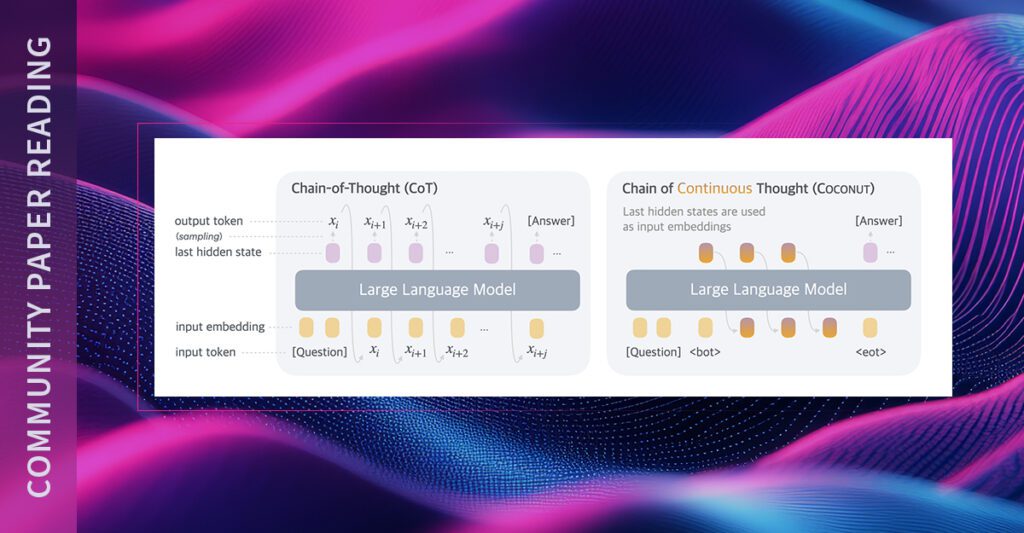
Training Large Language Models to Reason in Continuous Latent Space
LLMs have traditionally been restricted to reason in the “language space,” where chain-of-thought (CoT) is used to solve complex reasoning problems. But a new paper argues that language… Sarah Welsh January 24, 2025 4 min read -
 AI Evaluation
Arize Release Notes: Voice Application Tracing and Evaluation
What’s New Voice Application Tracing and Evaluation Capture, process, and send audio data to Arize. Instrument your audio application to send events and traces to Arize, capture key… Sarah Welsh January 21, 2025 2 min read -
 LLM As A Judge
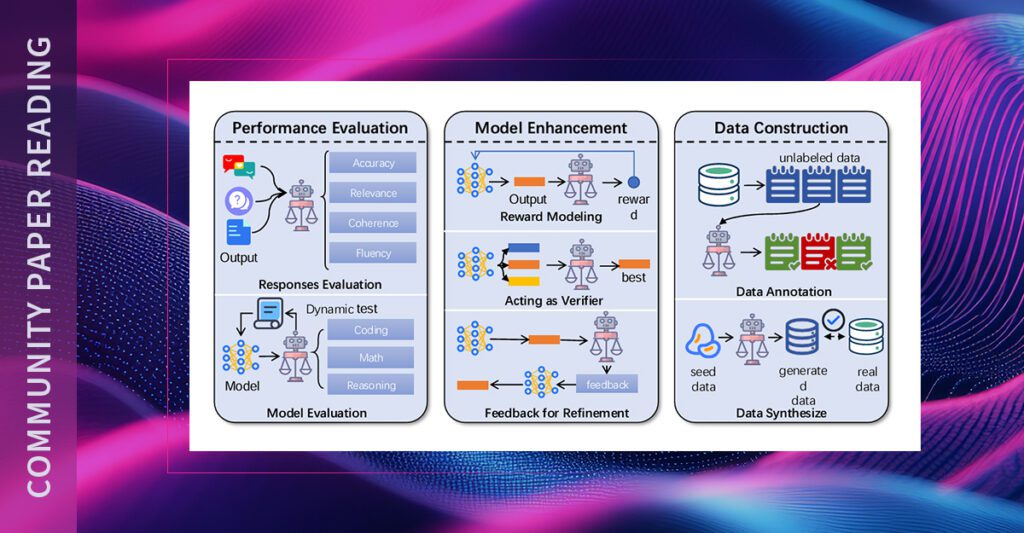
LLMs as Judges: A Comprehensive Survey on LLM-Based Evaluation Methods
We discuss a major survey of the LLMs-as-Judges paradigm: “LLMs-as-Judges: A Comprehensive Survey on LLM-based Evaluation Methods.” This paper systematically examines the LLMs-as-Judge framework across five dimensions: functionality,… Sarah Welsh December 23, 2024 3 min read -
 AI Evaluation
Arize Release Notes: Prompt Hub, Managed Code Evaluators and More
Welcome to our regular update on new releases, enhancements, and changes. What’s New Prompt Hub The Prompt Hub is a centralized repository for managing, iterating, and deploying prompt… Sarah Welsh December 19, 2024 3 min read -
 AI Engineering
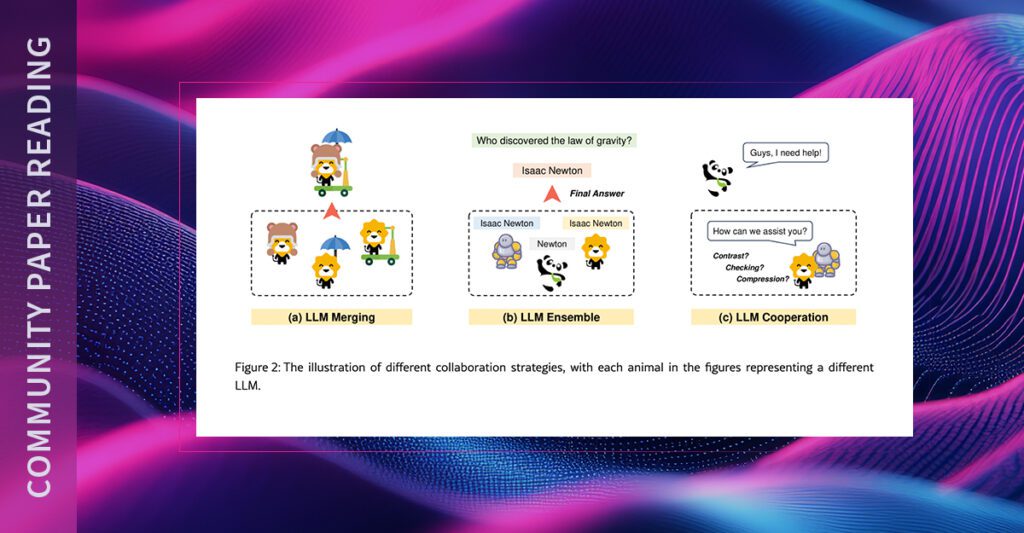
Merge, Ensemble, and Cooperate! A Survey on Collaborative LLM Strategies
LLMs have revolutionized natural language processing, showcasing remarkable versatility and capabilities. But individual LLMs often exhibit distinct strengths and weaknesses, influenced by differences in their training corpora. This… Sarah Welsh December 10, 2024 5 min read -
 AI Observability
Arize Release Notes: Copilot Enhancements, Experiment Projects, and More
Welcome to our regular update on new releases, enhancements, and changes. What’s New Copilot Enhancements Span Chat The Copilot Span Chat skill makes getting value from spans faster… Sarah Welsh December 5, 2024 2 min read -
 Agent Evaluation
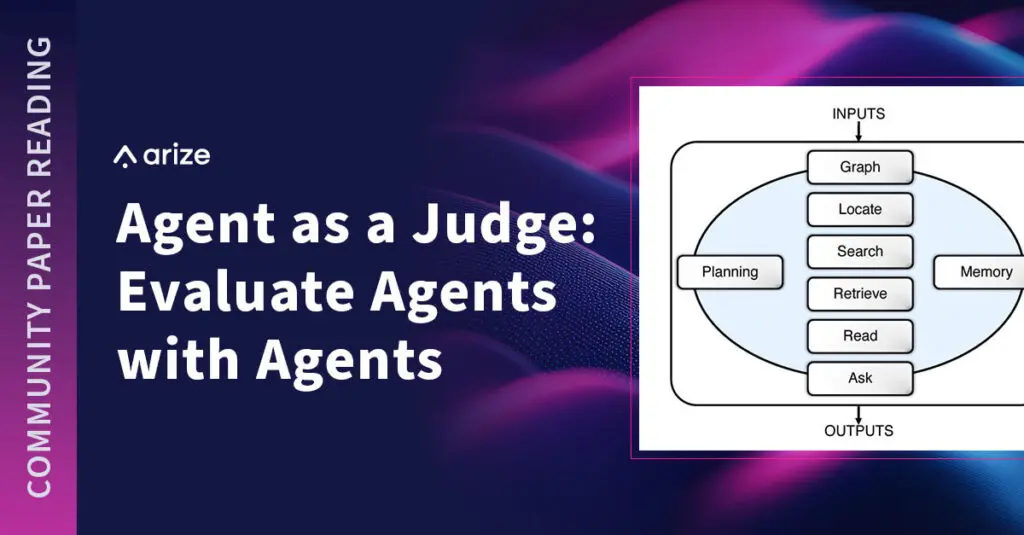
Agent-as-a-Judge: Evaluate Agents with Agents
This week we dive into a paper that presents the “Agent-as-a-Judge” framework, a new paradigm for evaluating agent systems. Where typical AI agent evaluation methods focus solely on… Sarah Welsh November 22, 2024 4 min read -
 AI Engineering
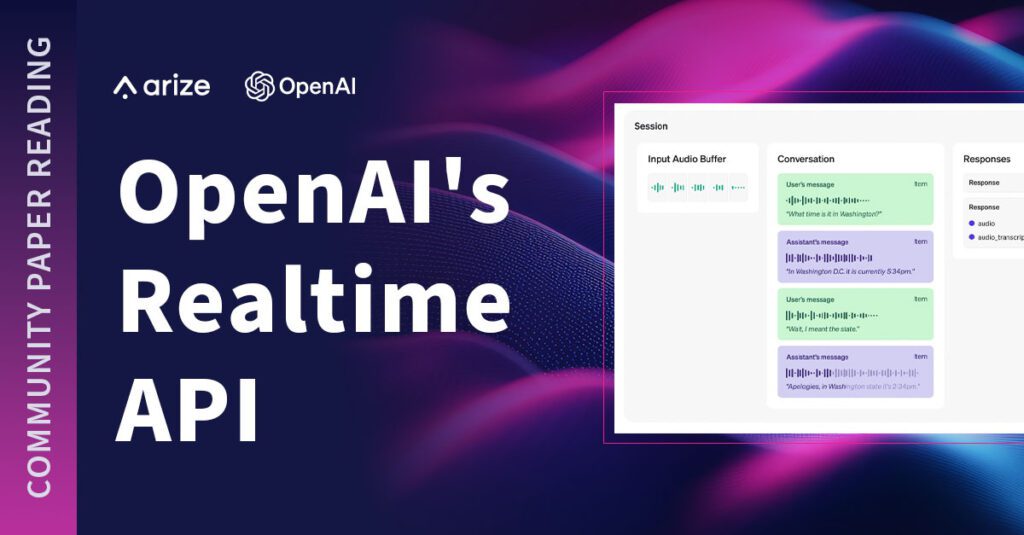
Introduction to OpenAI’s Realtime API
We break down OpenAI’s realtime API. Sally-Ann DeLucia and Aparna Dhinakaran cover how to seamlessly integrate powerful language models into your applications for instant, context-aware responses that drive… Sarah Welsh November 12, 2024 3 min read -
 AI Engineering
Arize Release Notes: New Copilot Skills, Local Explainability, and More.
Welcome to our regular update on new releases, enhancements, and changes. What’s New New Copilot Skills Custom Metric Skill: Copilot now writes custom metrics! Users can generate their… Sarah Welsh November 7, 2024 2 min read -
 Agent Engineering
Swarm: OpenAI’s Experimental Approach to Multi-Agent Systems
As multi-agent systems grow in importance for fields ranging from customer support to autonomous decision-making, OpenAI has introduced Swarm, an experimental framework that simplifies the process of building… Sarah Welsh October 29, 2024 4 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

