Author
Elizabeth Hutton
Recent posts
-
 Agent Evaluation
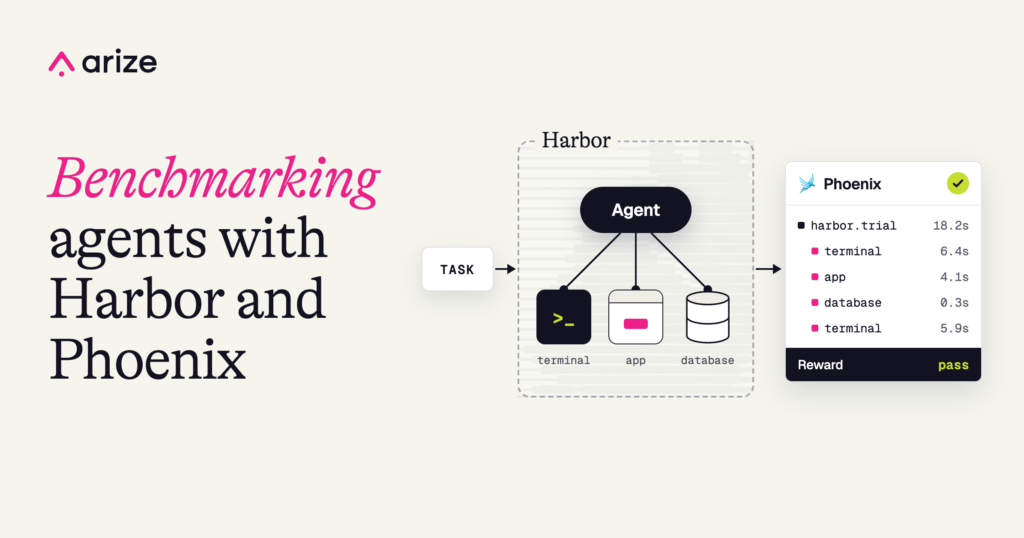
How we benchmark AI agents and tools with Harbor and Arize Phoenix
See how Arize uses Harbor and Phoenix to benchmark AI agents, MCP servers, skills, and CLIs in reproducible sandboxes, then inspect traces and annotations. Elizabeth Hutton October 5, 2026 5 min read -
 Agent Evaluation
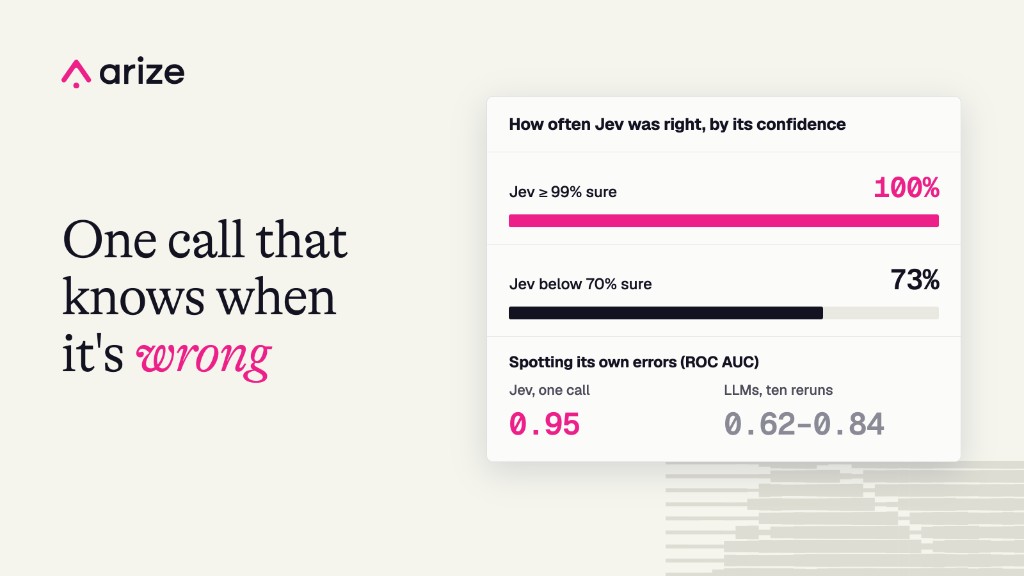
What Jev’s probabilities reveal that repeated LLM judgments miss
I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers changed alongside accuracy, cost, and latency. Elizabeth Hutton September 28, 2026 11 min read -
 LLM As A Judge
How to measure human-LLM judge alignment
No single metric proves an LLM judge is trustworthy. This field guide shows how to measure human–human agreement, compare it to LLM–human agreement, and diagnose errors with precision,… Elizabeth Hutton July 22, 2026 16 min read -
 Agent Evaluation
From observability to context: What’s next for Arize Phoenix
As agents start changing software, they need a way to verify their work that includes traces, evals, feedback, and APIs. This is where Phoenix goes next — not… Mikyo King Elizabeth Hutton May 11, 2026 10 min read -
 Agent Evaluation
How to Evaluate Tool-Calling Agents
When you give an LLM access to tools, you introduce a new surface area for failure — and it breaks in two distinct ways: The model selects the… Elizabeth Hutton March 2, 2026 9 min read -
 LLM As A Judge
Evidence-Based Prompting Strategies for LLM-as-a-Judge: Explanations and Chain-of-Thought
When LLMs are used as evaluators, two design choices often determine the quality and usefulness of their judgments: whether to require explanations for decisions, and whether to use… Sri Chavali Elizabeth Hutton Aparna Dhinakaran August 20, 2025 8 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

