Recent posts
-
 Agent Evaluation
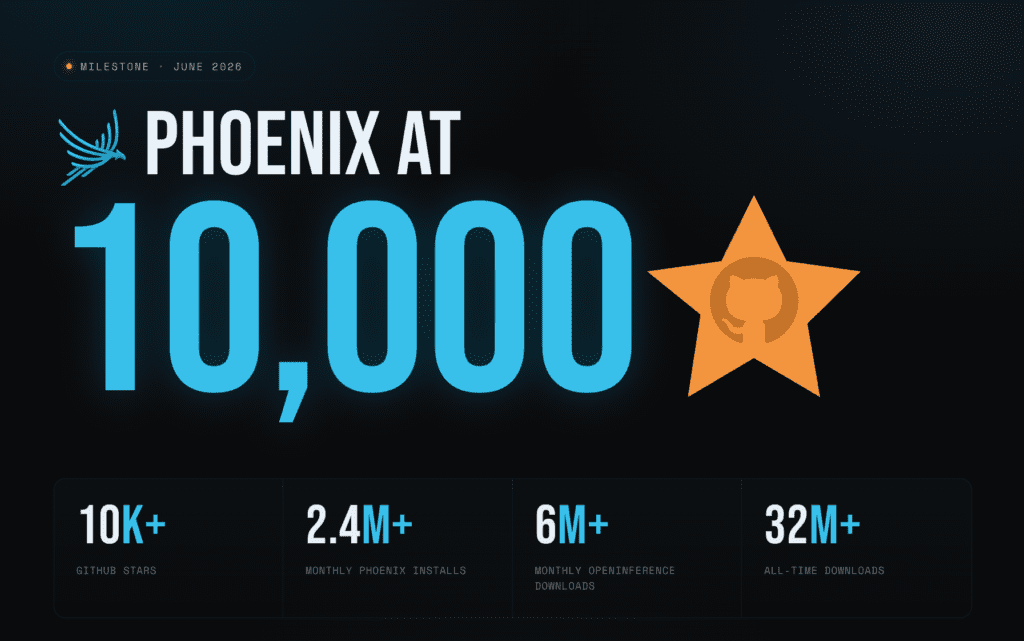
Phoenix at 10,000 stars on GitHub: How an open source AI observability project grew by following its community
Phoenix crossed 10,000 GitHub stars. Here is how the open-source AI observability project grew from a Jupyter notebook extension into a community-shaped platform for traces, evals, OpenInference, and… RL Nabors Nancy Chauhan June 7, 2026 10 min read -
 AI Evaluation
How to ship a local LLM that matches frontier LLMs with evals and prompt engineering
Most production AI features don't need a frontier model. Here's how capability evals and prompt engineering can help ship a local SLM that matches frontier-model quality with lower… RL Nabors May 26, 2026 15 min read -
 Agent Engineering
Agent harnesses have an expiration date
A benchmark-driven look at why agent harnesses need adaptive finish logic as model behavior changes across Claude, GPT-4o, and Gemma. RL Nabors May 7, 2026 11 min read -
 AI Engineering
Code is free, technical debt isn’t: Notes from AI Engineer Europe
Keynotes at Europe’s first flagship AI Engineer Conference shared one theme: code generation has accelerated past our ability to verify it, and the industry is quietly reorganizing around… RL Nabors April 20, 2026 5 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

