-
 LLM As A Judge
How to build a software factory that tests its own prompts
A small software factory that turns GitHub issues into released code, traces every station to Arize AX, and uses the verdicts it already produces to test and improve… Jim Bennett October 22, 2026 17 min read -
 LLM As A Judge
What agent traces can tell you without an LLM judge
Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI, without an LLM judge. Ashwin Govind Ugale October 6, 2026 8 min read -
 LLM As A Judge
Claude’s hillclimb loop for AI agents: start with production traces
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. Jim Bennett October 2, 2026 13 min read -
 LLM As A Judge
Anthropic says it fixed Claude’s writing. I ran the evals to check.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. Jim Bennett September 29, 2026 12 min read -
 LLM As A Judge
How to build a remote evaluator in Arize AX with Jev
Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. Sally-Ann DeLucia Jim Bennett September 24, 2026 12 min read -
 LLM As A Judge
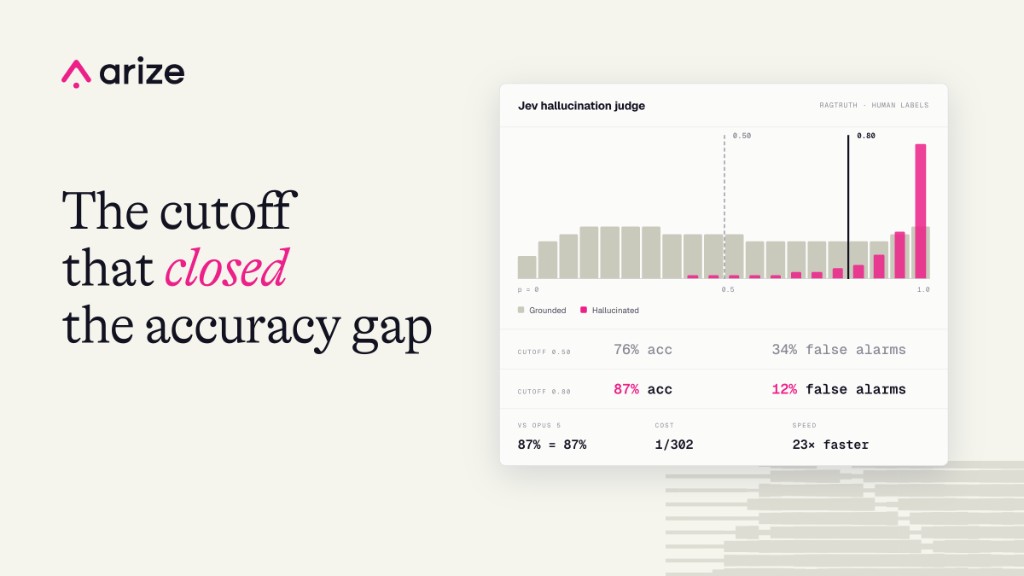
Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks
We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. Laurie Voss September 23, 2026 11 min read -
 LLM As A Judge
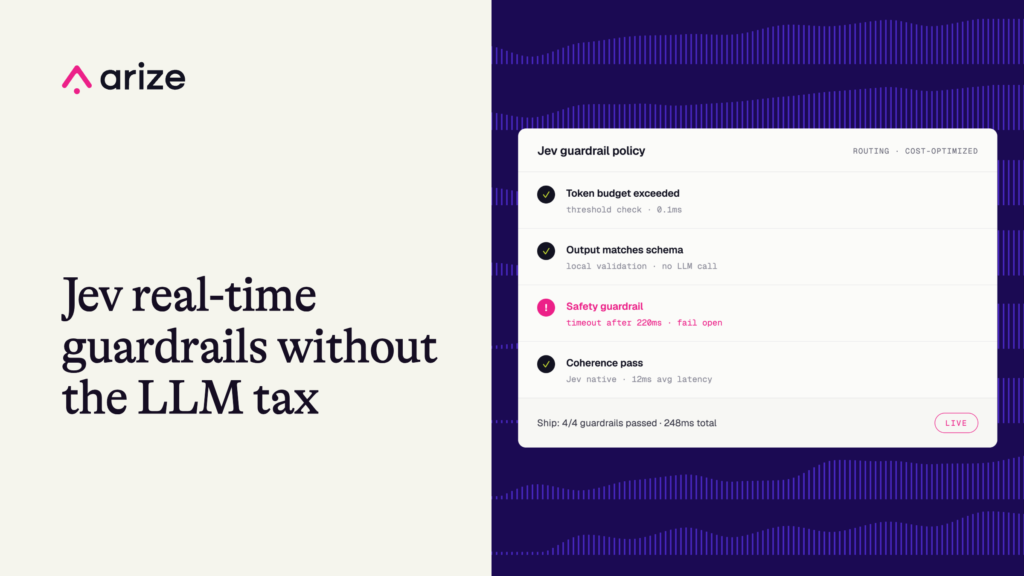
Real-time LLM guardrails with Jev: comparing latency and cost
Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. Jim Bennett September 23, 2026 13 min read -
 LLM As A Judge
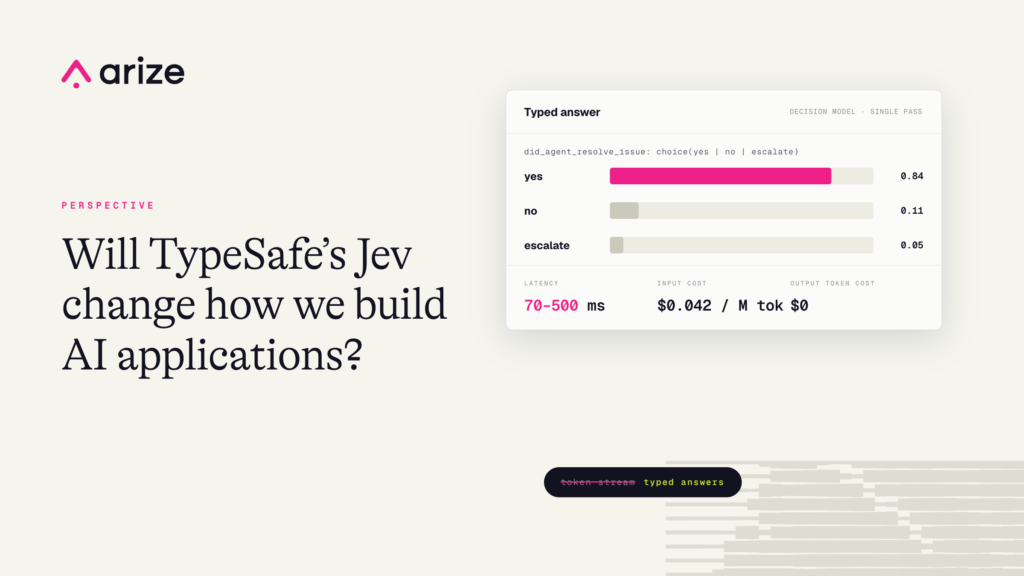
TypeSafe’s Jev: Can decision models replace LLM judges?
TypeSafe’s Jev classifies, scores, and routes without generating text — up to hundreds of times cheaper than an LLM judge. What that changes for evals, confidence routing, and… Laurie Voss September 18, 2026 10 min read -
 LLM As A Judge
How to measure human-LLM judge alignment
No single metric proves an LLM judge is trustworthy. This field guide shows how to measure human–human agreement, compare it to LLM–human agreement, and diagnose errors with precision,… Elizabeth Hutton July 22, 2026 16 min read -
 LLM As A Judge
How do you make an LLM, anyway? Microsoft just published a textbook.
Microsoft published a 109-page technical report on MAI-Thinking-1. Here’s the abbreviated version of how a modern lab actually trains a frontier reasoning model — from scraping the web… Laurie Voss July 13, 2026 11 min read -
 LLM As A Judge
AI evals are a data science problem: What most teams get wrong
Hamel Husain explains why the best AI teams treat LLM judges like classifiers, not dashboards. Sara Verdi June 30, 2026 10 min read -
 LLM As A Judge
Building the AI factory for self-improving agents: What’s new in Arize AX
Arize AX is adding managed agents, full-agent experimentation, expanded multimodal support, and Harness-as-a-Judge to help teams observe, evaluate, and improve production agents. Jason Lopatecki Aparna Dhinakaran June 4, 2026 8 min read -
 LLM As A Judge
How to build LLM-as-a-Judge evaluators that hold up in production
Learn how to design, calibrate, and run LLM-as-a-judge evaluators with fixed labels, human agreement checks, trace context, and Phoenix Evals. Aaron Winston May 21, 2026 22 min read -
 LLM As A Judge
Should I Use the Same LLM for My Eval as My Agent? Testing Self-Evaluation Bias
Thanks to Aparna Dhinakaran and Elizabeth Hutton for their contributions to this piece. When building and testing AI agents, one practical question that arises is whether to use… Sanjana Yeddula October 8, 2025 10 min read -
 LLM As A Judge
Evidence-Based Prompting Strategies for LLM-as-a-Judge: Explanations and Chain-of-Thought
When LLMs are used as evaluators, two design choices often determine the quality and usefulness of their judgments: whether to require explanations for decisions, and whether to use… Sri Chavali Elizabeth Hutton Aparna Dhinakaran August 20, 2025 8 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

