Guides.
Multi-agent orchestration: how to evaluate agent teams
Multi-agent orchestration coordinates specialized AI agents, handoffs, and shared state. Learn when it beats a single agent and…
Read the guide
How to pitch AI observability to your VP
How to make the case for AI observability to your VP: the numbers to bring, the pitch structure…
Read the guide
AI observability tools: how they work and how to choose one
Learn how AI observability tools work, which features matter, and how to evaluate platforms for tracing, evaluations, monitoring,…
Read the guide
Agent-as-a-Judge: A practical guide to agentic evaluation
Learn when to use an agent judge, how it differs from LLM-as-a-Judge, and how to write, validate, and…
Read the guide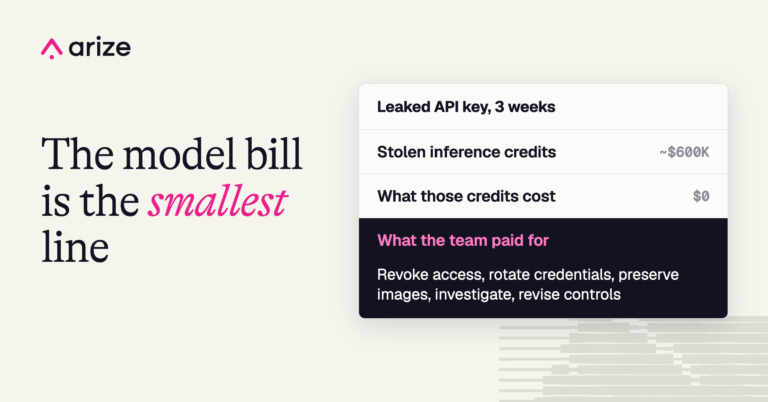
AI governance and security costs: what to budget for
Learn what drives AI governance and security costs, including controls, evaluation, human review, incidents, lifecycle changes, and production…
Read the guide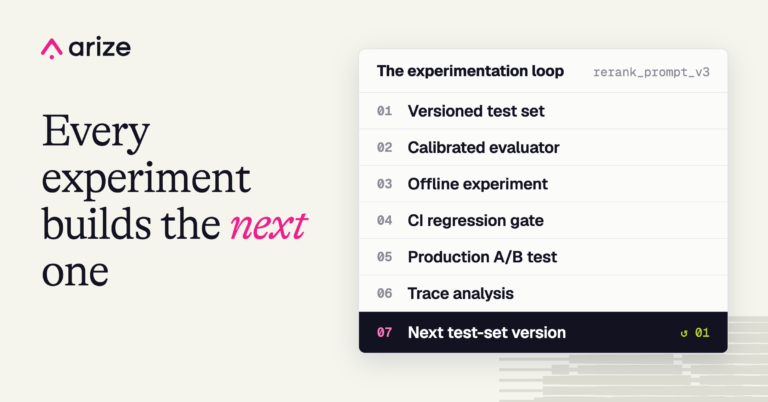
How to A/B test AI agents with an experimentation loop
Test agent changes with versioned test sets, calibrated evaluators, offline experiments, CI gates, production A/B tests, and trace-level…
Read the guide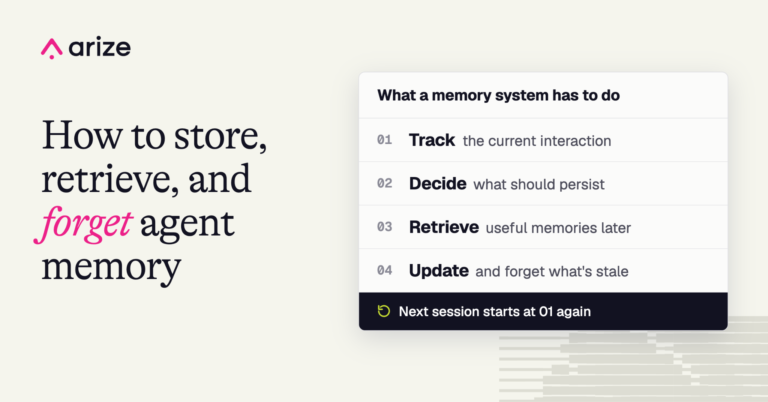
AI agent memory systems: how long-term memory works
Learn how AI agent memory works, including long-term memory, profiles, vector retrieval, knowledge graphs, memory architecture, tools, and…
Read the guide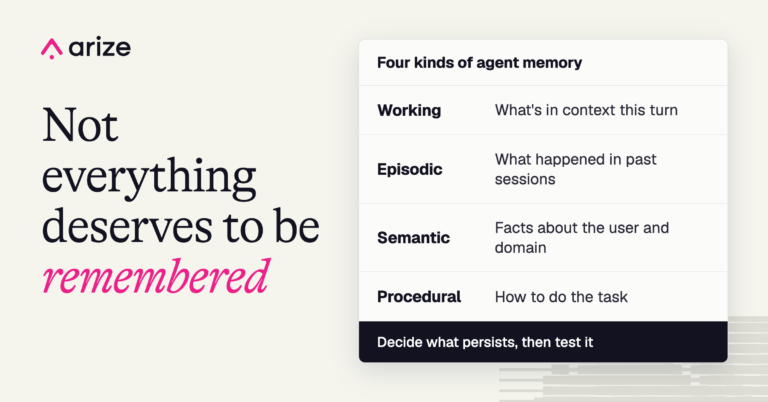
AI memory: types, architecture, and how memory works in AI agents
Learn how AI memory works in agents, including working, episodic, semantic, and procedural memory, architecture patterns, retrieval, updating,…
Read the guide
How to choose an AI observability platform
Learn how to choose an AI observability platform in 2026, with evaluation criteria for tracing, evals, monitoring, pricing…
Read the guide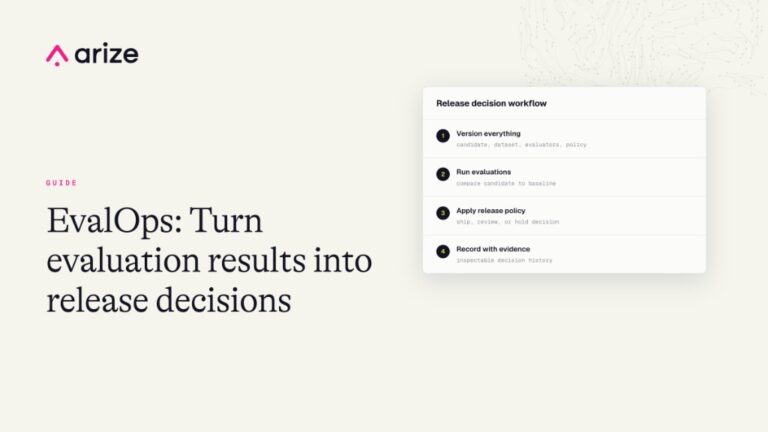
EvalOps: How to build AI evaluation release gates
Learn how to turn AI evaluations into release gates with a worked agent example, ship/review/hold criteria, and a…
Read the guide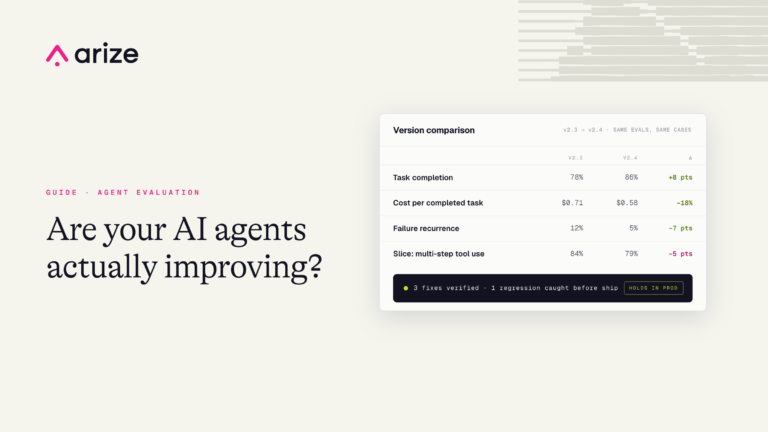
How to evaluate whether your AI agents are actually improving
Measure AI agent improvement with task completion, cost per completed task, regression checks, and consistent before-and-after evaluations.
Read the guide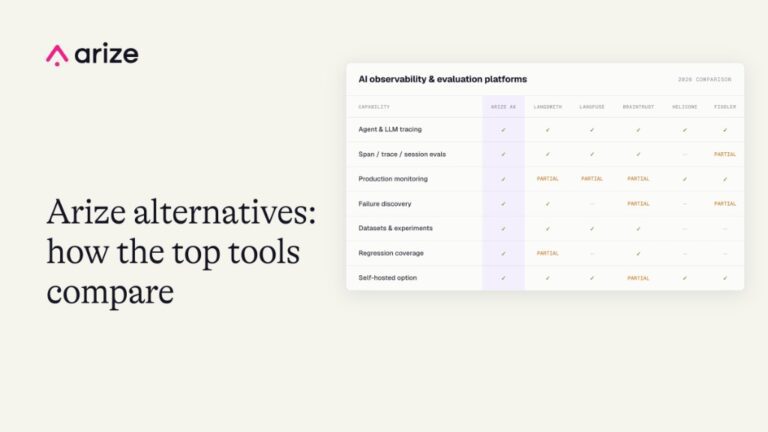
Arize alternatives: How the top AI observability and evaluation tools compare
Compare Arize alternatives including LangSmith, Langfuse, Braintrust, Helicone, and Fiddler on evals, tracing, self-hosting, and production depth. See…
Read the guideDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

