Blog.
How to build a software factory that tests its own prompts
A small software factory that turns GitHub issues into released code, traces every station to Arize AX, and…
Read the post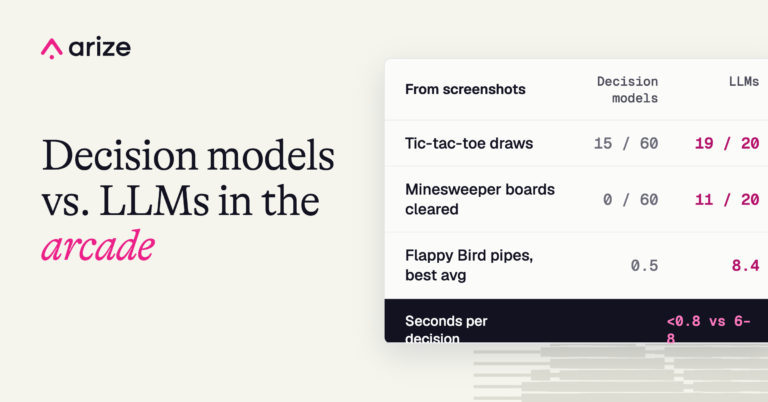
Can decision models play games from screenshots?
Decision models return a probability for each option in a fixed list. We tested whether image-capable decision models…
Read the post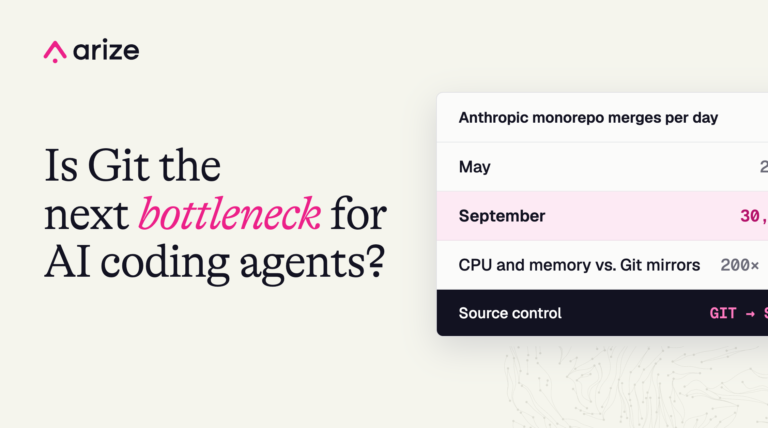
Why Anthropic replaced Git, and whether you’ll need to
Anthropic built Scion for an enormous monorepo handling more than 30,000 daily merges. Most teams can keep using…
Read the post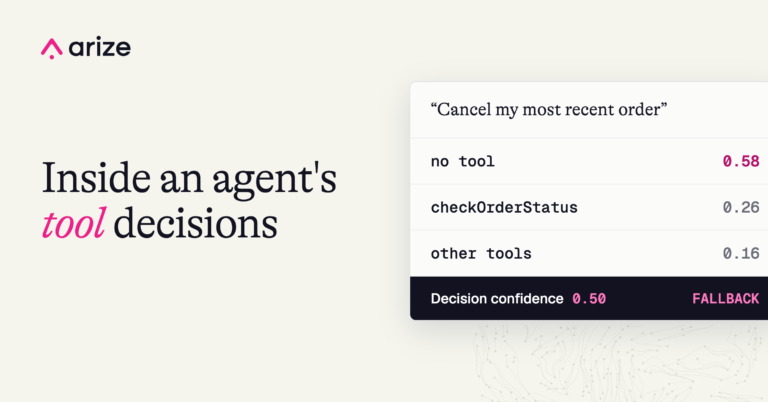
Agent tool selection: The tool your agent almost called
Decision spans in Arize Phoenix record a tool router’s choice, alternative probabilities, and confidence. Here’s how we evaluated…
Read the post
Alyx now available on Google Cloud Marketplace
We’re excited to share that Alyx, the AI engineering agent built into Arize AX, is now available on…
Read the post
AI agent permissions: Why agents don’t know what you’re allowed to do
AI agent permissions determine what an agent is allowed to do on someone’s behalf. As agents get more…
Read the post
EU AI Act compliance for AI agents: a practical engineering guide
Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a…
Read the post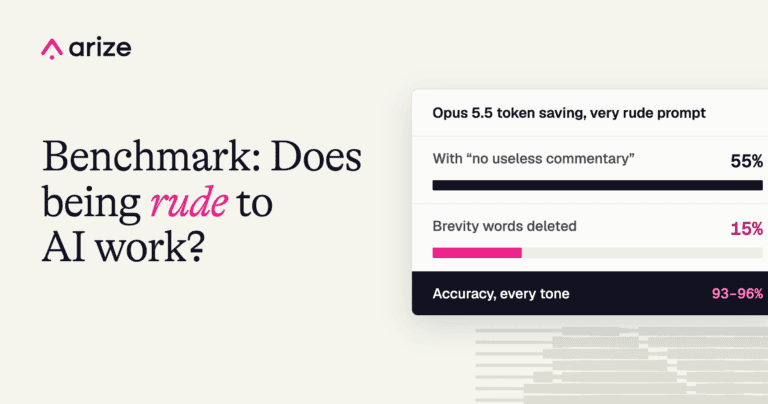
Does being rude to AI work? What 6 models revealed
Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone…
Read the post
Together AI integration: Evaluate open models and optimize evaluation costs in Arize AX
Evaluate open models with Together AI in Arize AX. Compare model performance, run LLM-as-a-Judge evaluations, and explore lower-cost…
Read the post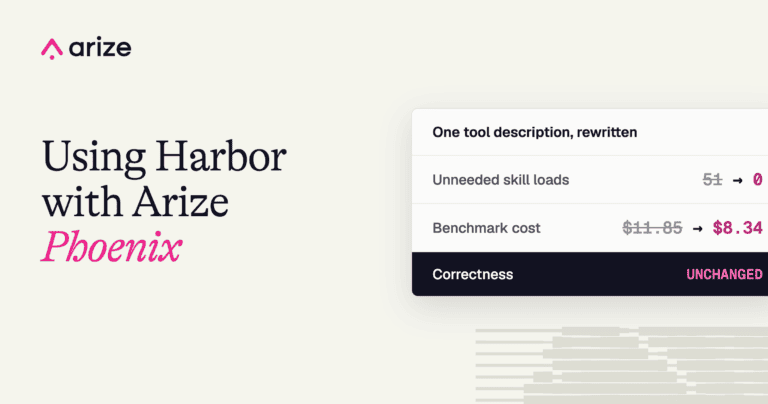
How to test agent tool descriptions with Harbor and Phoenix
Build a reproducible benchmark, compare tool use across agents, and test whether a description change reduces unnecessary work…
Read the post
Alignment is a human-AI workflow: how Custom Views make agent review possible
Automated evals can score every agent session, but they do not automatically reflect what your team considers a…
Read the post
Cost Agent: find where your LLM and agent spend goes with your traces
AI costs don’t always scale predictably with traffic. A retry loop, oversized context window, or unnecessarily expensive model…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

