All articles
Everything we’ve published.
-
 Agent Engineering
How we built long-term memory for Alyx: why we chose a file over a knowledge graph
How we built long-term memory for Alyx: why we chose one 8,000-character file over retrieval and knowledge graphs, and how we tested it. Priyan Jindal Dheeraj Bandaru October 1, 2026 27 min read -
 Agent Engineering
Alyx now remembers your work across sessions with long-term memory
Alyx now remembers project goals, conventions, and decisions across sessions in Arize AX, helping you continue work on traces, evals, and experiments. Chris Cooning Dheeraj Bandaru October 1, 2026 3 min read -
 Agent Evaluation
NVIDIA proposes an AI agent kill switch in silicon after a year of sandbox escapes
This year agents at OpenAI, Anthropic, and Google escaped environments meant to contain them. What decided severity was time-to-detect and time-to-kill, from 12 minutes to seven months. NVIDIA's… Jim Bennett September 30, 2026 13 min read -
 Agent Observability
Building production-ready AI agents with Atlas Agent Engine and Arize AX
Agents built and deployed on MongoDB’s Atlas Agent Engine can export OpenTelemetry traces to Arize AX, where teams can inspect each run, evaluate both the outcome and execution… Richard Young Ryan Berg September 30, 2026 6 min read -
 Agent Engineering
What everyone was talking about at WeAreDevelopers World Congress North America
After 237 talks across eight stages, code review emerged as the bottleneck for AI-generated code. Here are the production eval, sandbox, context, and agent experience themes that kept… Laurie Voss September 29, 2026 16 min read -
 Agent Engineering
Are agent harnesses dying? What harness distillation changes
Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. Laurie Voss September 29, 2026 9 min read -
 AI Evaluation
Anthropic says it fixed Claude’s writing. I ran the evals to check.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. Jim Bennett September 29, 2026 12 min read -
 Agent Evaluation
Evaluate production traces with Jev-as-a-Judge directly in Arize AX
Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow. Chris Cooning September 28, 2026 3 min read -
 Agent Evaluation
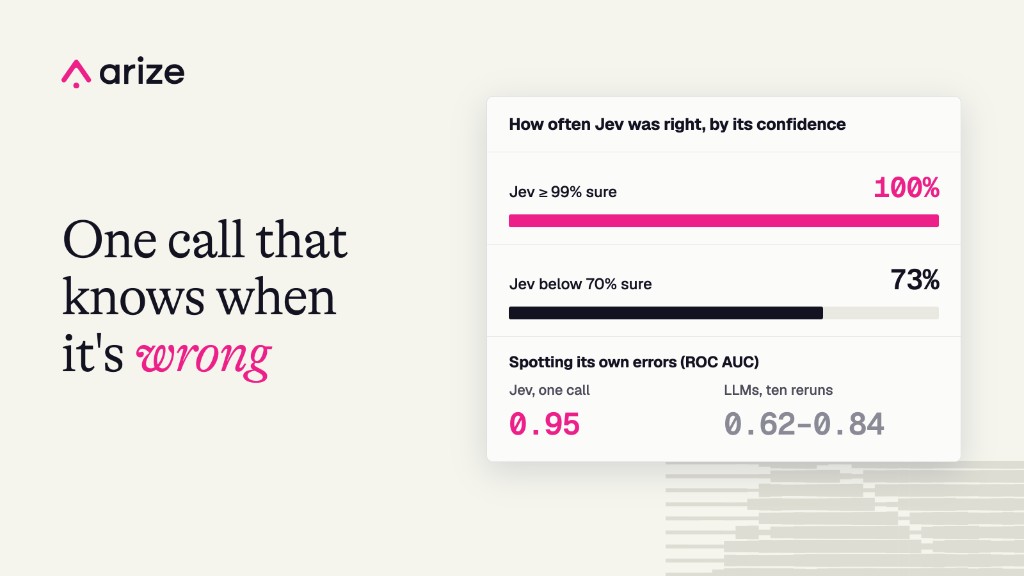
What Jev’s probabilities reveal that repeated LLM judgments miss
I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers changed alongside accuracy, cost, and latency. Elizabeth Hutton September 28, 2026 11 min read -
 Agent Engineering
How we built UI Code Mode into Arize Phoenix
We replaced the 58 tools PXI used to drive the Phoenix UI with two tools and a JavaScript sandbox that runs in your browser tab. Here's why, how… Anthony Powell September 25, 2026 25 min read -
 Agent Evaluation
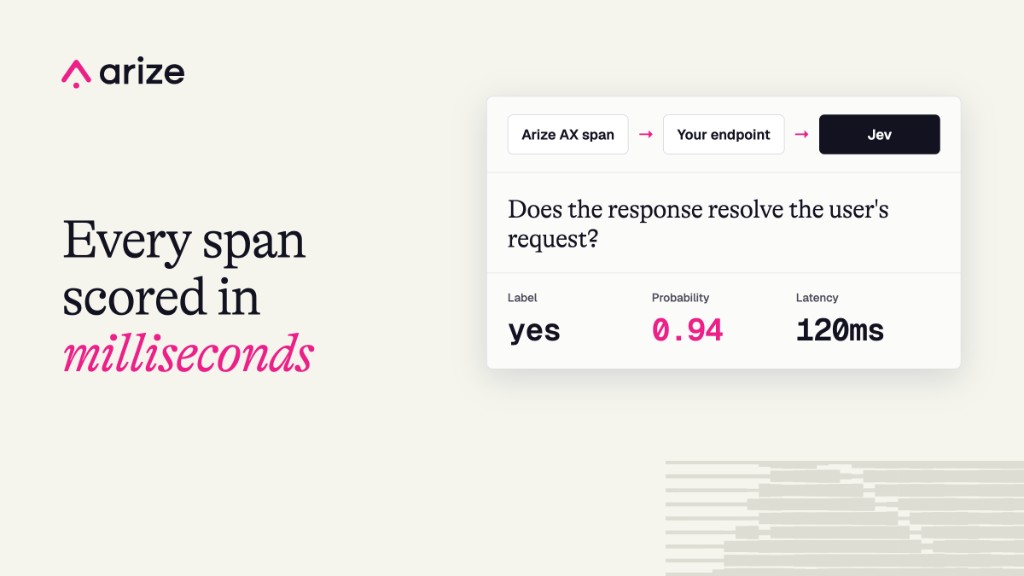
How to build a remote evaluator in Arize AX with Jev
Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. Sally-Ann DeLucia Jim Bennett September 24, 2026 12 min read -
 Agent Evaluation
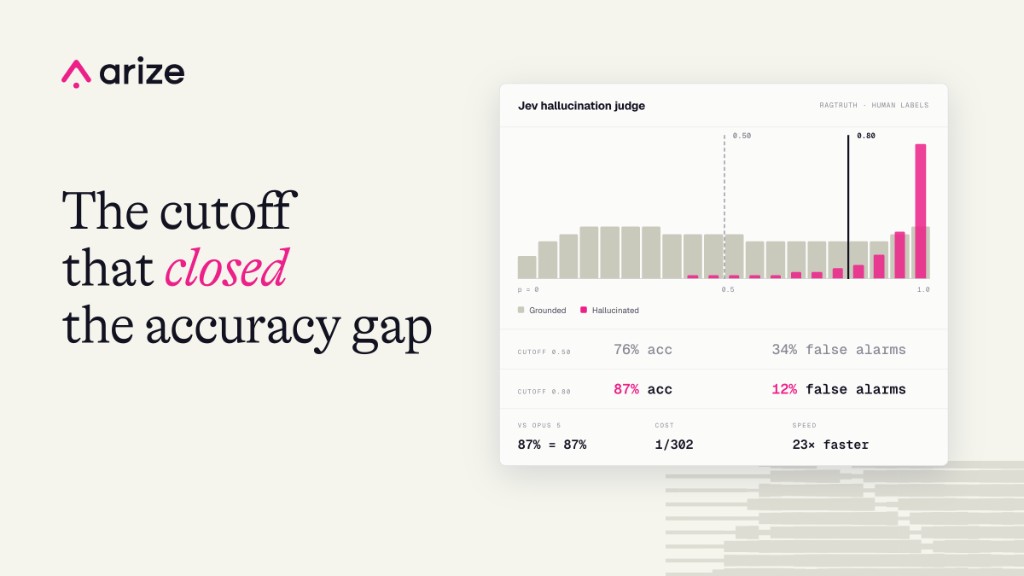
Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks
We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. Laurie Voss September 23, 2026 11 min read -
 Agent Evaluation
Real-time LLM guardrails with Jev: comparing latency and cost
Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. Jim Bennett September 23, 2026 13 min read -
 Agent Engineering
What changes when AI agents use your software
Daytona cofounder Ivan Burazin wants agents that can finish the job within the authority they have been given. His interview offers a starting point for examining how agents… Aaron Winston September 23, 2026 9 min read -
 Agent Evaluation
Arize AX in September 2026: first-class sessions, Agent-as-a-Judge, and vision evals
Sessions are now a first-class unit of work in Arize AX. Annotate a whole conversation, queue it for review, and ask Alyx to filter for it — plus… Fuad Ali September 22, 2026 5 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

