All articles
Everything we’ve published — page 2.
-
 Agent Evaluation
Alignment is a human-AI workflow: how Custom Views make agent review possible
Automated evals can score every agent session, but they do not automatically reflect what your team considers a good outcome. That takes human judgment. Dheeraj Bandaru October 9, 2026 7 min read -
 Agent Engineering
Cost Agent: find where your LLM and agent spend goes with your traces
AI costs don’t always scale predictably with traffic. A retry loop, oversized context window, or unnecessarily expensive model can make a small number of traces disproportionately expensive. Fuad Ali October 8, 2026 3 min read -
 Agent Evaluation
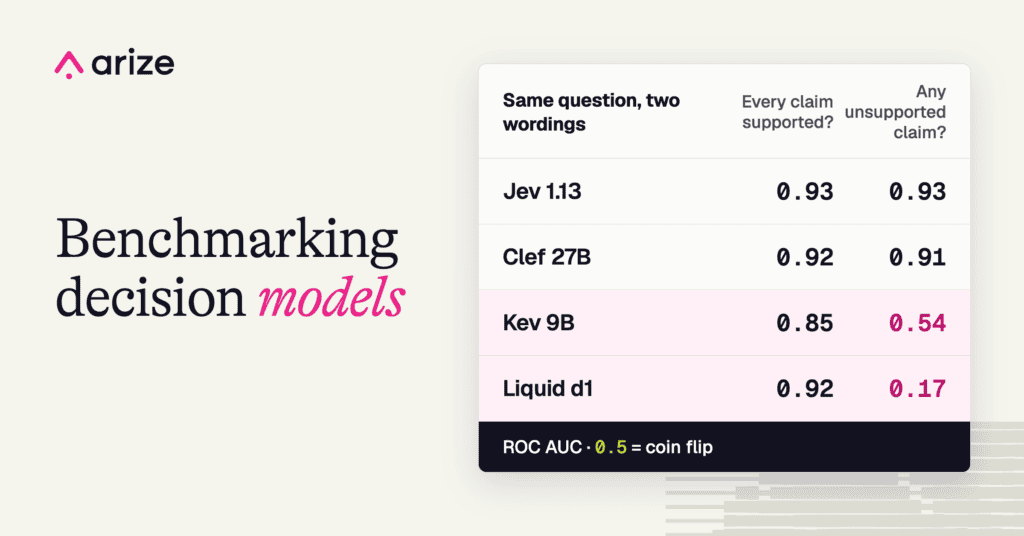
Decision model benchmark: Jev, Kev, Liquid d1, and more
On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog… Jim Bennett October 7, 2026 13 min read -
 Agent Evaluation
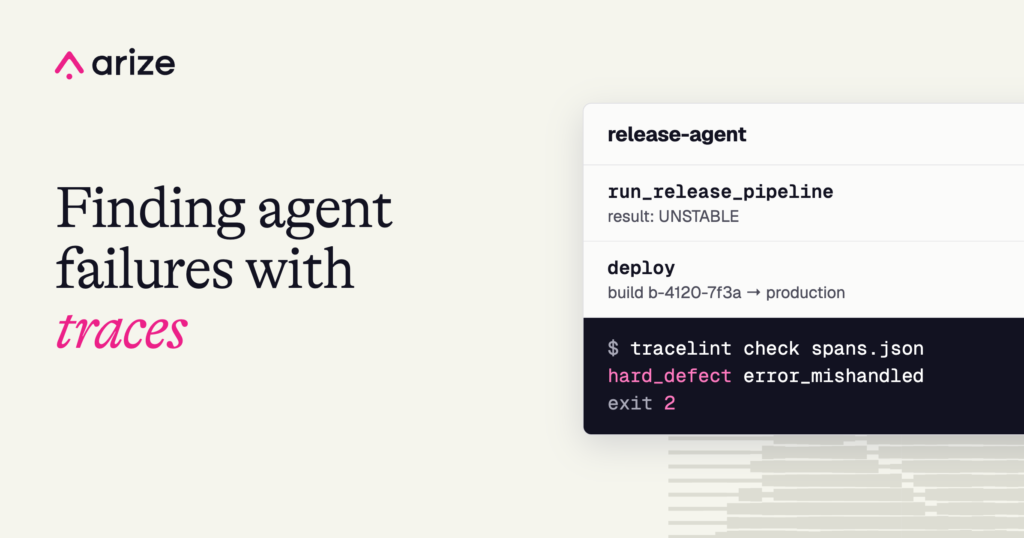
What agent traces can tell you without an LLM judge
Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI, without an LLM judge. Ashwin Govind Ugale October 6, 2026 8 min read -
 Agent Evaluation
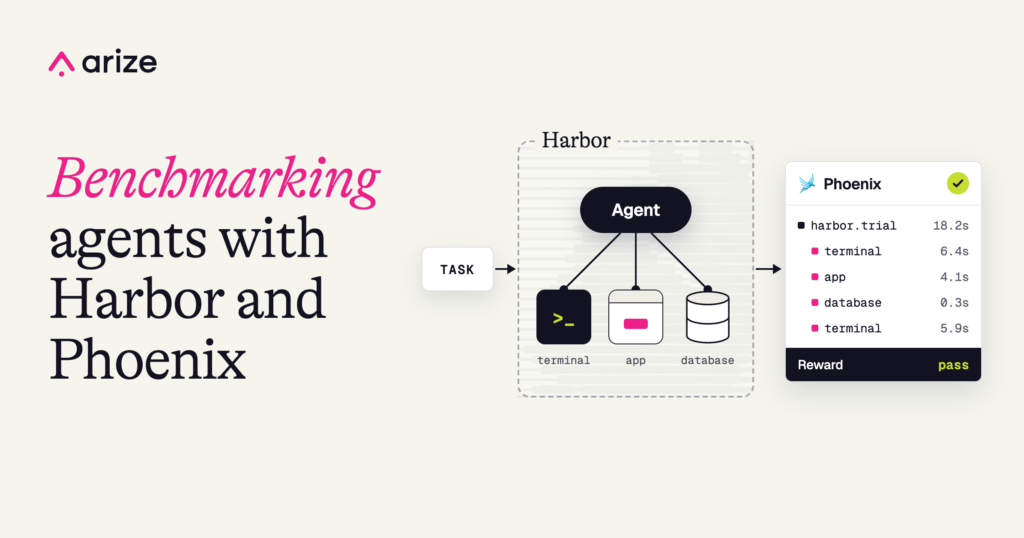
How we benchmark AI agents and tools with Harbor and Arize Phoenix
See how Arize uses Harbor and Phoenix to benchmark AI agents, MCP servers, skills, and CLIs in reproducible sandboxes, then inspect traces and annotations. Elizabeth Hutton October 5, 2026 5 min read -
 Agent Engineering
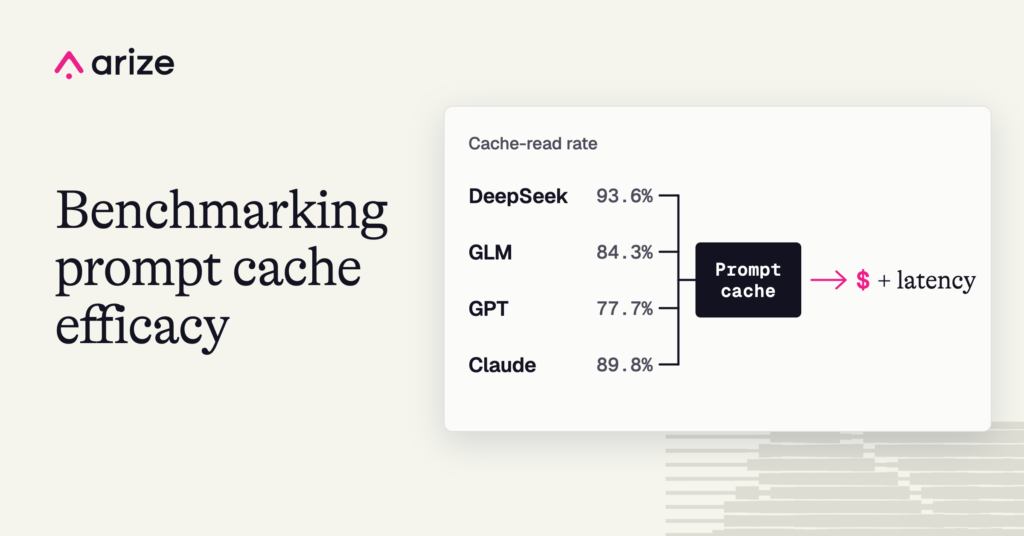
Prompt caching benchmark: high cache reuse doesn’t always mean lower cost
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we could compare cache reuse, estimated cost, and latency on the… Nancy Chauhan October 2, 2026 7 min read -
 Agent Engineering
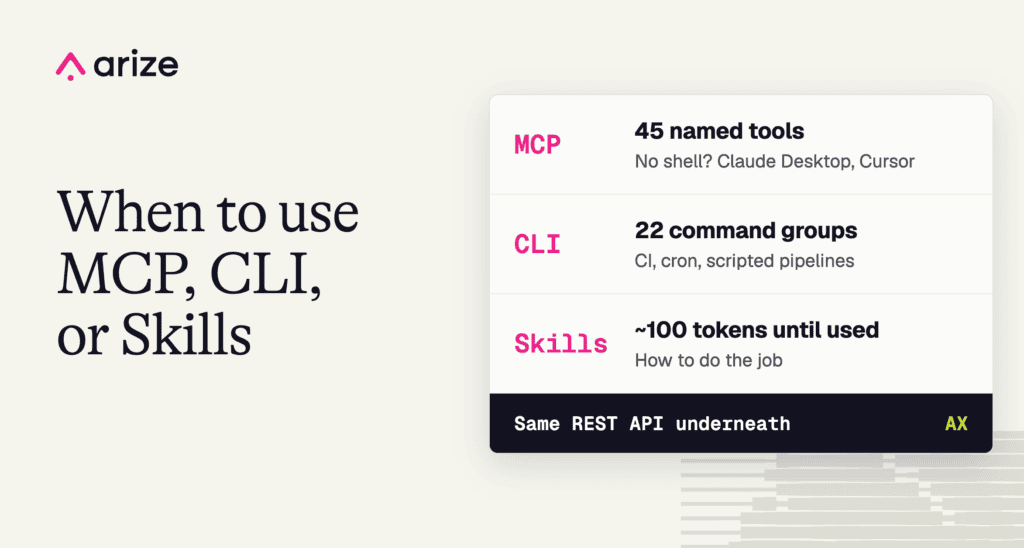
Introducing Arize AX MCP: When to use MCP, CLI, or skills
MCP, CLI, and skills are three ways to extend an agent with the same platform. The question is no longer which one wins. It is where the agent… Fuad Ali Dirk Brand Sragvi Vadali October 2, 2026 11 min read -
 Agent Evaluation
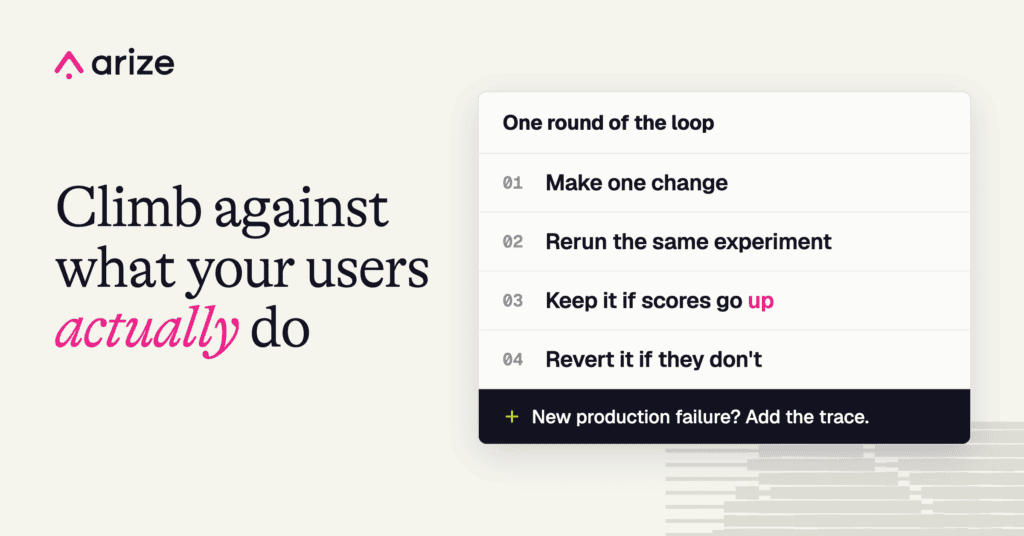
Claude’s hillclimb loop for AI agents: start with production traces
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. Jim Bennett October 2, 2026 13 min read -
 Agent Engineering
How we built long-term memory for Alyx: why we chose a file over a knowledge graph
How we built long-term memory for Alyx: why we chose one 8,000-character file over retrieval and knowledge graphs, and how we tested it. Priyan Jindal Dheeraj Bandaru October 1, 2026 27 min read -
 Agent Engineering
Alyx now remembers your work across sessions with long-term memory
Alyx now remembers project goals, conventions, and decisions across sessions in Arize AX, helping you continue work on traces, evals, and experiments. Chris Cooning Dheeraj Bandaru October 1, 2026 3 min read -
 Agent Evaluation
NVIDIA proposes an AI agent kill switch in silicon after a year of sandbox escapes
This year agents at OpenAI, Anthropic, and Google escaped environments meant to contain them. What decided severity was time-to-detect and time-to-kill, from 12 minutes to seven months. NVIDIA's… Jim Bennett September 30, 2026 13 min read -
 Agent Observability
Building production-ready AI agents with Atlas Agent Engine and Arize AX
Agents built and deployed on MongoDB’s Atlas Agent Engine can export OpenTelemetry traces to Arize AX, where teams can inspect each run, evaluate both the outcome and execution… Richard Young Ryan Berg September 30, 2026 6 min read -
 Agent Engineering
What everyone was talking about at WeAreDevelopers World Congress North America
After 237 talks across eight stages, code review emerged as the bottleneck for AI-generated code. Here are the production eval, sandbox, context, and agent experience themes that kept… Laurie Voss September 29, 2026 16 min read -
 Agent Engineering
Are agent harnesses dying? What harness distillation changes
Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. Laurie Voss September 29, 2026 9 min read -
 AI Evaluation
Anthropic says it fixed Claude’s writing. I ran the evals to check.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. Jim Bennett September 29, 2026 12 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

