All articles
Everything we’ve published — page 4.
-
 Agent Engineering
Agent cost management is about more than the model
Every LLM call your application makes costs money, and agentic applications make a lot of LLM calls. Arize AX now ships a Cost Agent that reads traces, ranks… Laurie Voss September 1, 2026 8 min read -
 AI Engineering
How to reduce LLM costs without sacrificing quality
Trace where your AI budget goes, identify the requests that do not justify their spend, and validate lower-cost alternatives with Arize AX. Nancy Chauhan August 31, 2026 11 min read -
 Agent Engineering
How Signal found two hidden retry loops in our production agent Alyx
We ran Signal on Alyx, the AI engineering agent built into Arize AX. It surfaced a duplicate task-state loop and a 43-call dataset retry that appeared as valid… Nancy Chauhan August 27, 2026 8 min read -
 Agent Evaluation
Arize Phoenix has a built-in MCP server that lets your agents query traces with SQL
Read-only SQL and code mode let coding agents answer questions across your traces without paging thousands of spans through model context. Nancy Chauhan Roger Yang Mora Vigo Malusardi August 27, 2026 10 min read -
 Agent Engineering
Why better models don’t fix every agent failure: Lessons from OpenAI
In this installment of Rise of the AI Engineer, Stuart Sy from OpenAI, explains why the bottleneck has moved off the model and onto context, evals, and observability. Sara Verdi August 25, 2026 9 min read -
 Agent Evaluation
A skill is just an agent. So measure your changes.
A skill is just another AI agent: a prompt plus a harness that runs it. That means you can trace it, eval it, and prove a change made… Jim Bennett August 24, 2026 10 min read -
 Agent Evaluation
Is your coding agent uploading all your code?
After Grok Build was caught uploading entire Git repos, we read the privacy docs for Claude Code, Codex, Cursor, GitHub Copilot, and Grok Build to compare what code… Laurie Voss August 20, 2026 7 min read -
 Agent Evaluation
Where agent evals are going: Agent-as-a-Judge
Agents changed what failure looks like, and the evaluation layer has to change with them. Why agent-as-a-judge is moving from research paper to production eval stack. Laurie Voss August 19, 2026 8 min read -
 Agent Engineering
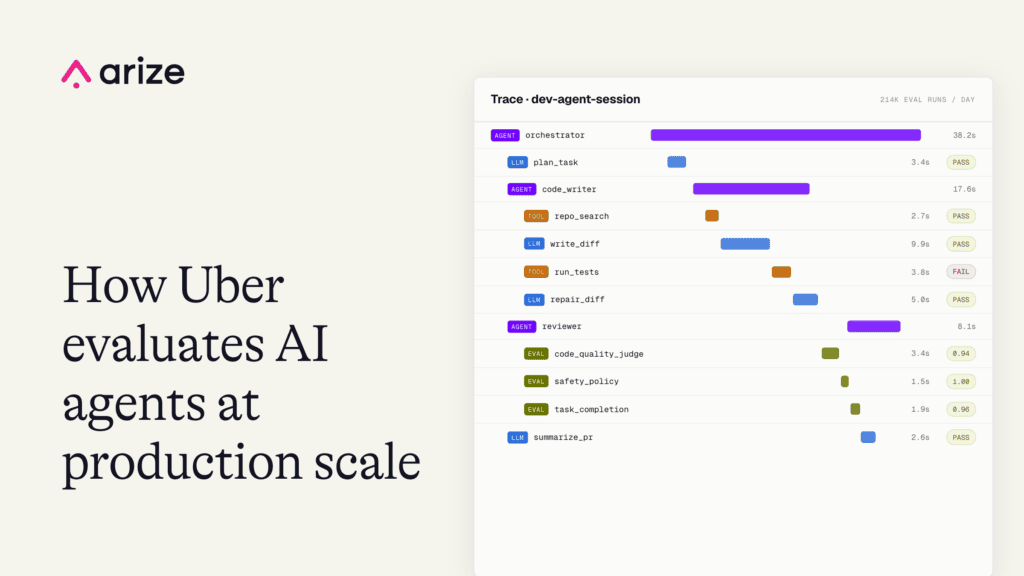
How Uber evaluates AI agents at production scale
A background comment about pizza exposed a failure that Uber’s offline evaluations had missed. The incident helped reveal what production AI agent evaluation actually requires: automatic tracing, living… Sara Verdi August 14, 2026 14 min read -
 Company
Arize and Dynatrace: Making the World’s AI Work
Today we are announcing the signing of a definitive agreement for the acquisition of Arize by Dynatrace to accelerate our mission to make the world's AI work. Jason Lopatecki August 13, 2026 5 min read -
 Agents
AI agent guardrails vs. evals: How to build more reliable agent systems
Guardrails constrain what an agent can do in code; evals judge whether it performed well. Learn how both layers—and the harness around them—make long-running AI agents reliable. Aaron Winston August 13, 2026 9 min read -
 Agent Engineering
Evaluation-driven development: How to move AI agents from pilot to production
Learn how evaluation-driven development, agent harnesses, AI observability, guardrails, and cost-per-outcome metrics move AI agents from pilot to production. Sara Verdi August 13, 2026 19 min read -
 Agent Observability
Crew Studio launches with native Arize AX tracing and evaluation
Through a native Arize AX integration, teams can send traces from Crew Studio to Arize from the first run without custom instrumentation—then inspect behavior, evaluate quality, and test… Richard Young Jesse Miller August 13, 2026 5 min read -
 AI Engineering
You chose the best model. Why is your agent still failing?
Public benchmarks can show how a model performs in general. Production reliability depends on the context and harness around it, which only your team can evaluate against its… Aparna Dhinakaran Prukalpa Sankar August 12, 2026 12 min read -
 Agent Observability
Arize AX adds native support for OpenTelemetry GenAI semantic conventions
Arize AX now normalizes OpenTelemetry GenAI semantic conventions into first-class AI traces, unlocking evaluations, token and cost visibility, and easier debugging. Chris Cooning Dheeraj Bandaru August 11, 2026 4 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

