-
 Agent Evaluation
Trace before you migrate: Measuring Kubernetes bottlenecks in AI agent sandboxes
Kubernetes is strong for long-lived services, but it is often a poor default for short-lived agent sandboxes. Trace sandbox creation, tool execution, eval latency, and full trajectory time… Sara Verdi July 9, 2026 7 min read -
 Agent Evaluation
The agent is the user now: lessons from the founder of WorkOS
WorkOS founder Michael Grinich explains why the next era of AI engineering depends on the systems around agents: identity, permissions, evals, memory, and feedback loops that keep autonomous… Aaron Winston July 8, 2026 9 min read -
 Agent Evaluation
How to evaluate AI agents, avoid reward hacking, and build better specs
Agent evals are repeatable tests that score whether AI agents completed a task correctly. Learn how to design rubrics, test suites, and trace-based evals that catch failures and… Sara Verdi July 2, 2026 9 min read -
 Agent Evaluation
Model subsidies are ending. What do you do now?
Flat-rate AI plans are subsidizing agentic workloads. Learn why LLM inference costs are moving to metered pricing and how evals reveal cost per successful task. Laurie Voss July 1, 2026 8 min read -
 Agent Evaluation
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
A field guide to the new wave of long-horizon agent benchmarks: what each one actually measures, the realism-versus-verifiability bargain it strikes, and the seam where its score leaks. Jim Bennett June 24, 2026 14 min read -
 Agent Evaluation
Meet PXI: the AI engineering agent inside Phoenix
An AI engineering agent built into Phoenix. It works like a coding agent, just point it at your telemetry instead of a source tree. Mikyo King Roger Yang Nancy Chauhan Anthony Powell June 18, 2026 17 min read -
 Agent Evaluation
Agent harness vs. agent framework: why harnesses are replacing frameworks
Agent harnesses are replacing frameworks as the real product surface for reliable AI agents, shifting the work from prompt tuning to loops, tools, traces, evals, and operational metrics. Laurie Voss June 18, 2026 8 min read -
 Agent Evaluation
Bring production agent traces from Arize into Databricks Unity Catalog
Arize Data Fabric now supports Databricks, helping teams sync production agent traces, evaluations, and annotations into customer-owned storage for governed analysis in Unity Catalog. Richard Young June 11, 2026 8 min read -
 Agent Evaluation
Phoenix at 10,000 stars on GitHub: How an open source AI observability project grew by following its community
Phoenix crossed 10,000 GitHub stars. Here is how the open-source AI observability project grew from a Jupyter notebook extension into a community-shaped platform for traces, evals, OpenInference, and… RL Nabors Nancy Chauhan June 7, 2026 10 min read -
 Agent Evaluation
Building the AI factory for self-improving agents: What’s new in Arize AX
Arize AX is adding managed agents, full-agent experimentation, expanded multimodal support, and Harness-as-a-Judge to help teams observe, evaluate, and improve production agents. Jason Lopatecki Aparna Dhinakaran June 4, 2026 8 min read -
 Agent Evaluation
Microsoft’s open trust stack runs on OpenInference
Microsoft's open trust stack for AI agents puts ASSERT and Agent Control Specification on top of OpenInference, connecting evaluation, runtime controls, and observability through a shared trace contract. Jim Bennett June 3, 2026 6 min read -
 Agent Evaluation
The best eval harness for production AI and agents: A comparison
A practical comparison of production AI evaluation harnesses, including what to look for across instrumentation, evaluators, online evals, CI gates, and agent workflows. Laurie Voss June 1, 2026 10 min read -
 Agent Evaluation
How to build a better agent harness with traces and evals
Agents are easy to prototype and hard to improve. A repeatable loop of traces, evals, failed-span inspection, and targeted harness changes makes agent behavior easier to debug and… Aaron Winston May 29, 2026 14 min read -
 Agent Evaluation
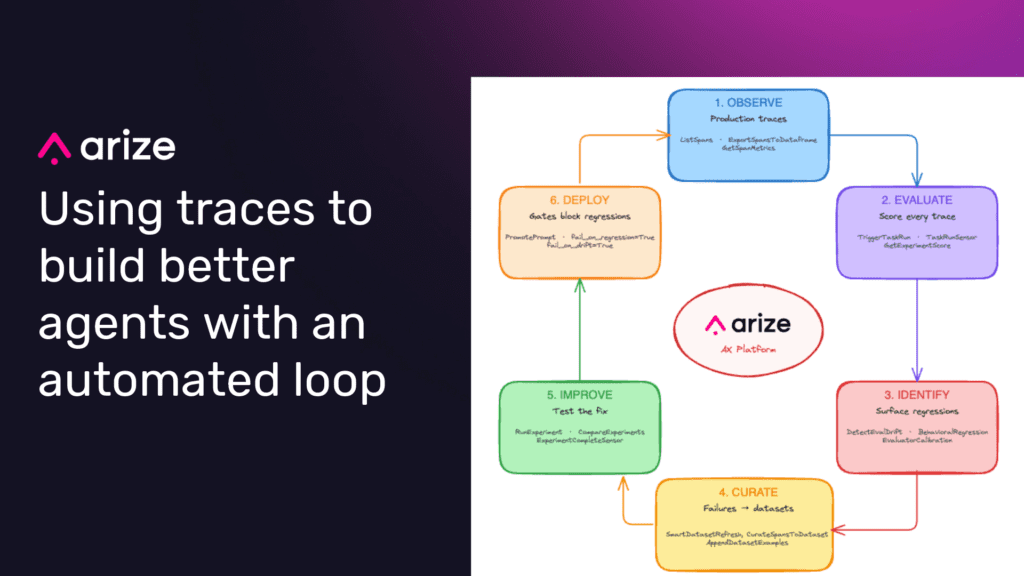
From production traces to better AI agents: Automating the LLMOps feedback loop
Production AI traces are the raw material for better evals, prompts, datasets, and fine-tuned models. This post shows how the Arize AX Airflow Provider turns that feedback loop… Jitendra Yadav Hakan Tekgul May 27, 2026 17 min read -
 Agent Evaluation
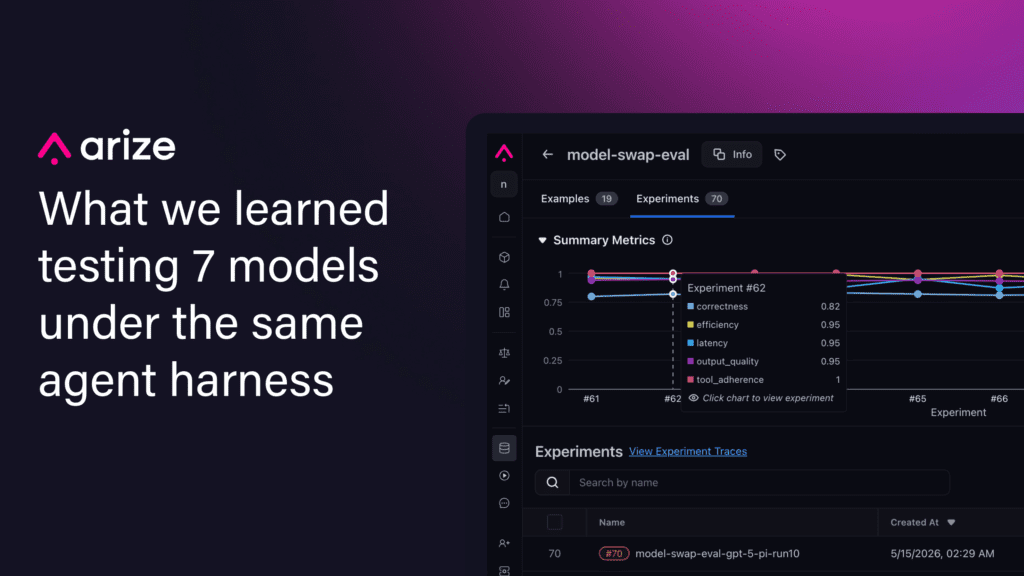
What we learned testing 7 models under the same agent harness
Model swaps look like configuration changes, but they behave more like product migrations. A new model may be cheaper, faster, easier to get capacity for, or stronger on… Nancy Chauhan May 20, 2026 10 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

