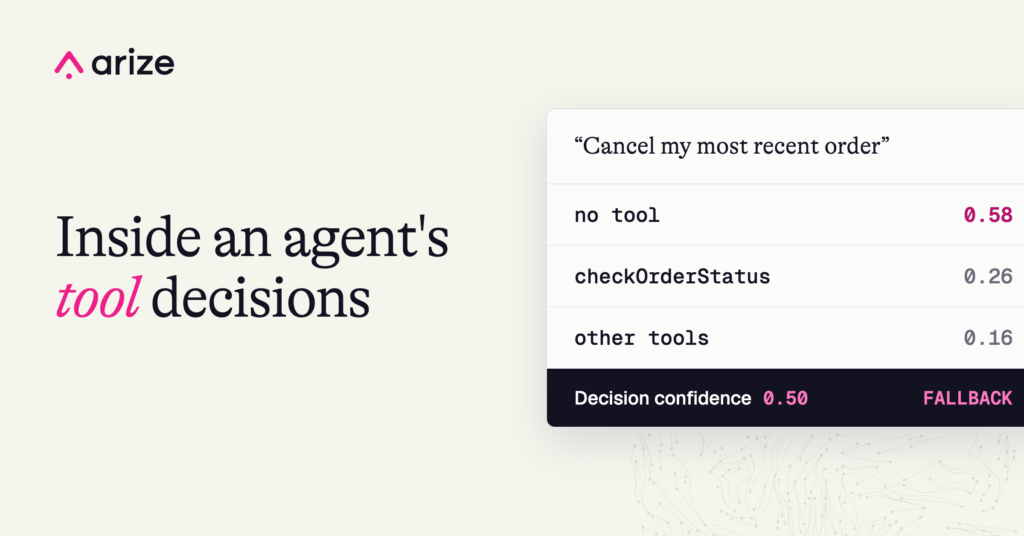
AI agent tool selection: The tool your agent almost called
Decision spans in Arize Phoenix record a tool router’s choice, alternative probabilities, and confidence. Here’s how we evaluated those decisions and used the results to set a fallback…
14 min readAlyx now available on Google Cloud Marketplace
We’re excited to share that Alyx, the AI engineering agent built into Arize AX, is now available on Google Cloud Marketplace. Teams building and running AI agents on…
4 min read
AI agent permissions: Why agents don’t know what you’re allowed to do
AI agent permissions determine what an agent is allowed to do on someone’s behalf. As agents get more powerful, we’re running into a basic problem: a model can’t…
8 min readBenchmarks, agent evaluations, and experiments.
View all research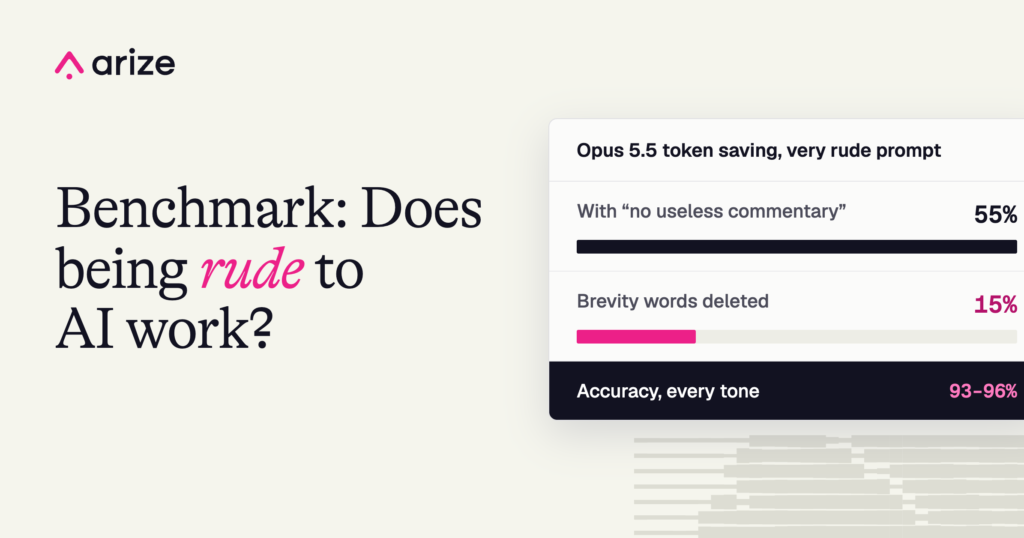
Does being rude to AI work? What 6 models revealed
Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes.
October 13, 2026 16 min read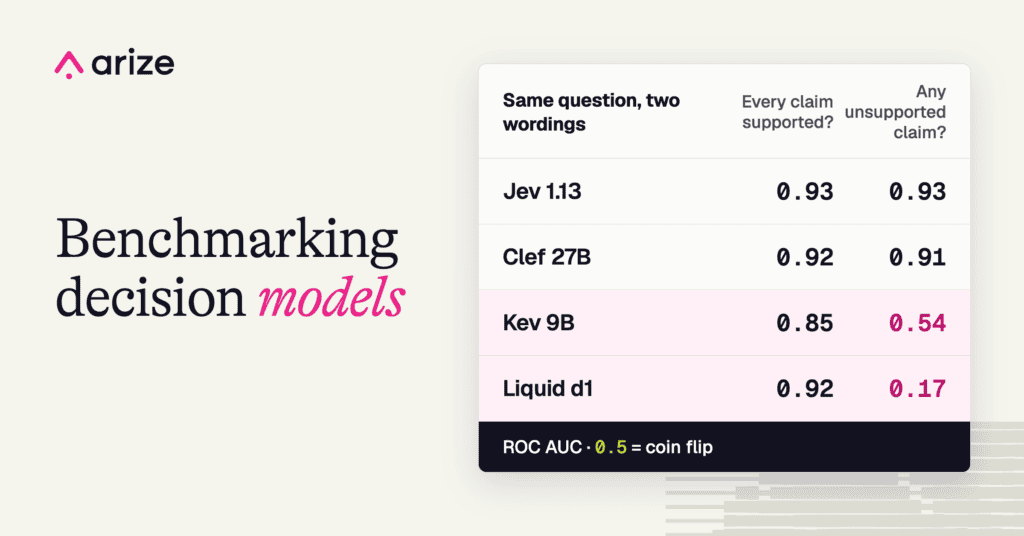
Decision model benchmark: Jev, Kev, Liquid d1, and more
On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog…
October 7, 2026 13 min read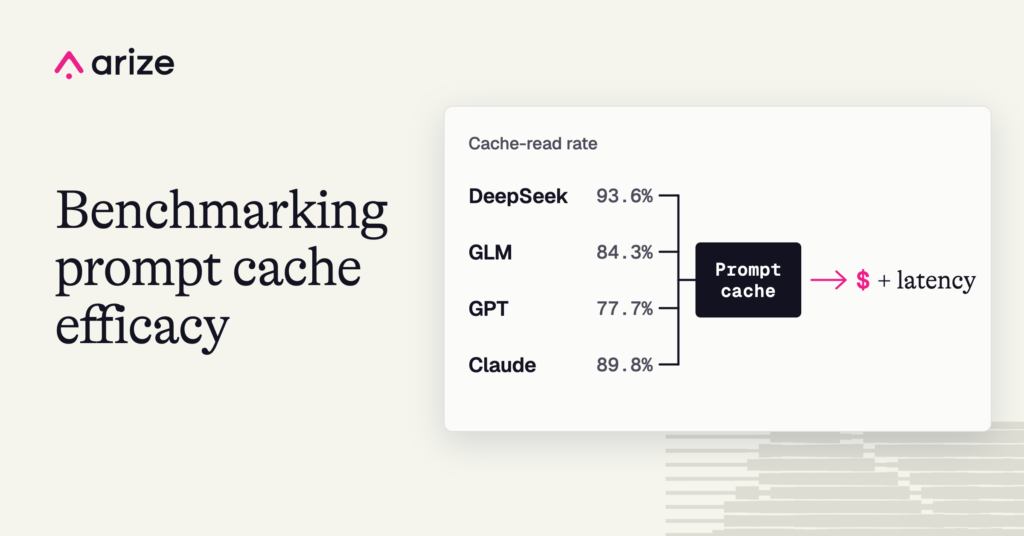
Prompt caching benchmark: high cache reuse doesn’t always mean lower cost
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we could compare cache reuse, estimated cost, and latency on the…
October 2, 2026 7 min readDemos, workshops, and conference talks.
See all on YouTube
The Model Knew What to Say. The Harness Failed. | Laurie Voss
Laurie Voss (Head of Developer Relations at Arize AI) breaks down why the agent harness, specifically code-level guardrails, is the most critical boundary layer in modern software engineering.
InsightsGet the latest on AI & Observability
Sign up for our newsletter, The Evaluator—and stay in the know with updates and new resources:
Real teams, shipping AI.
See allHow Booking.com scales AI observability with Arize
How Booking.com built a unified AI observability stack with Arize for agentic GenAI workflows and traditional ML — from telemetry collection and PII redaction to latency monitors and…
Read moreHow LG Uplus is building better AI customer service agents with evaluation-driven development
How LG Uplus uses Arize AX to build evaluation-driven AI contact center agents — combining production traces, user feedback, and domain expertise to continuously improve customer service for…
Read moreHow Tripadvisor is building the AI product development lifecycle for agentic travel
Tripadvisor VP of Data and AI Rahul Todkar on building a production AI lifecycle for traditional ML and agentic travel products with unified observability, traces, evals, and governance…
Read moreCatch up on everything you missed.
See all-
 Agent Observability
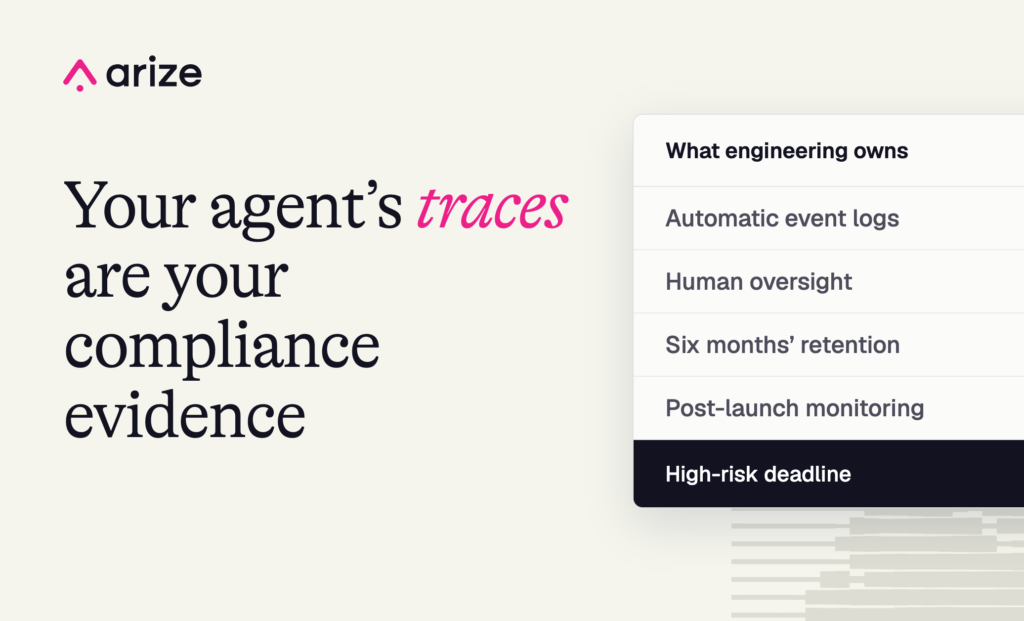
EU AI Act compliance for AI agents: a practical engineering guide
Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a practical credit-assistant example. Jim Bennett October 13, 2026 15 min read -
 AI Engineering
Together AI integration: Evaluate open models and optimize evaluation costs in Arize AX
Evaluate open models with Together AI in Arize AX. Compare model performance, run LLM-as-a-Judge evaluations, and explore lower-cost alternatives. Chris Cooning Lexi Pierre October 12, 2026 4 min read -
 Agent Evaluation
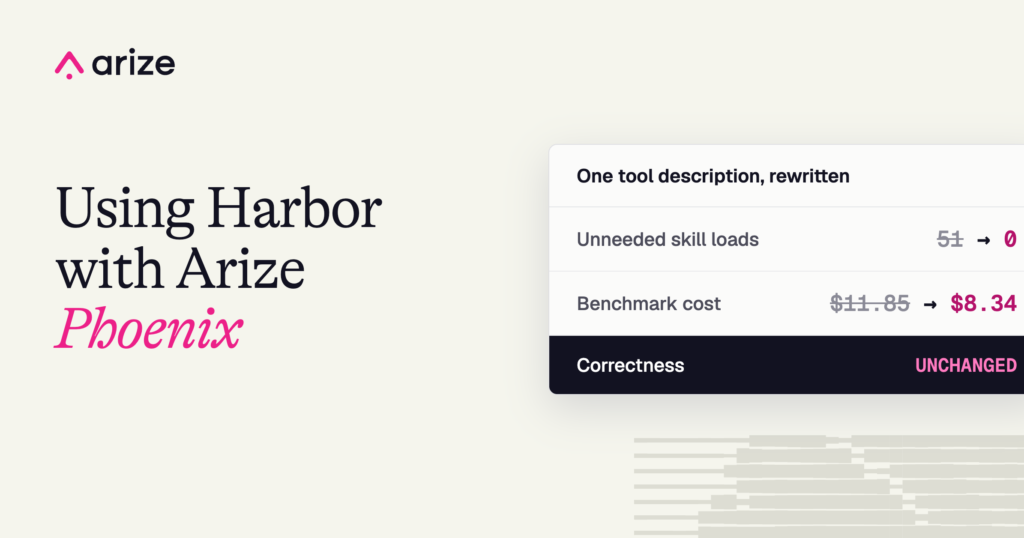
How to test agent tool descriptions with Harbor and Phoenix
Build a reproducible benchmark, compare tool use across agents, and test whether a description change reduces unnecessary work while preserving outcomes. Nancy Chauhan October 12, 2026 11 min read -
 Agent Evaluation
Alignment is a human-AI workflow: how Custom Views make agent review possible
Automated evals can score every agent session, but they do not automatically reflect what your team considers a good outcome. That takes human judgment. Dheeraj Bandaru October 9, 2026 7 min read -
 Agent Engineering
Cost Agent: find where your LLM and agent spend goes with your traces
AI costs don’t always scale predictably with traffic. A retry loop, oversized context window, or unnecessarily expensive model can make a small number of traces disproportionately expensive. Fuad Ali October 8, 2026 3 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

