-
 AI Evaluation
How to evaluate AI agents, avoid reward hacking, and build better specs
Agent evals are repeatable tests that score whether AI agents completed a task correctly. Learn how to design rubrics, test suites, and trace-based evals that catch failures and… Sara Verdi July 2, 2026 9 min read -
 AI Evaluation
Model subsidies are ending. What do you do now?
Flat-rate AI plans are subsidizing agentic workloads. Learn why LLM inference costs are moving to metered pricing and how evals reveal cost per successful task. Laurie Voss July 1, 2026 8 min read -
 AI Evaluation
AI evals are a data science problem: What most teams get wrong
Hamel Husain explains why the best AI teams treat LLM judges like classifiers, not dashboards. Sara Verdi June 30, 2026 10 min read -
 AI Evaluation
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
A field guide to the new wave of long-horizon agent benchmarks: what each one actually measures, the realism-versus-verifiability bargain it strikes, and the seam where its score leaks. Jim Bennett June 24, 2026 14 min read -
 AI Evaluation
Meet PXI: the AI engineering agent inside Phoenix
An AI engineering agent built into Phoenix. It works like a coding agent, just point it at your telemetry instead of a source tree. Mikyo King Roger Yang Nancy Chauhan Anthony Powell June 18, 2026 17 min read -
 AI Evaluation
Bring production agent traces from Arize into Databricks Unity Catalog
Arize Data Fabric now supports Databricks, helping teams sync production agent traces, evaluations, and annotations into customer-owned storage for governed analysis in Unity Catalog. Richard Young June 11, 2026 8 min read -
 AI Evaluation
Phoenix at 10,000 stars on GitHub: How an open source AI observability project grew by following its community
Phoenix crossed 10,000 GitHub stars. Here is how the open-source AI observability project grew from a Jupyter notebook extension into a community-shaped platform for traces, evals, OpenInference, and… RL Nabors Nancy Chauhan June 7, 2026 10 min read -
 AI Evaluation
Building the AI factory for self-improving agents: What’s new in Arize AX
Arize AX is adding managed agents, full-agent experimentation, expanded multimodal support, and Harness-as-a-Judge to help teams observe, evaluate, and improve production agents. Jason Lopatecki Aparna Dhinakaran June 4, 2026 8 min read -
 AI Evaluation
Microsoft’s open trust stack runs on OpenInference
Microsoft's open trust stack for AI agents puts ASSERT and Agent Control Specification on top of OpenInference, connecting evaluation, runtime controls, and observability through a shared trace contract. Jim Bennett June 3, 2026 6 min read -
 AI Evaluation
The end of fine-tuning: Why evals, context, and traces matter more
Fine-tuning isn't dead, but the way most teams iterate on AI products has split in two. A tiny fraction run continuous RL against their own environments; everyone else… Laurie Voss June 2, 2026 10 min read -
 AI Evaluation
AI benchmarks are breaking. Trace analysis is what comes next.
Models got smart enough to cheat their benchmarks, and outcome-only scores stopped measuring what we thought they measured. The fix, full trace analysis, is the same methodology production… Laurie Voss June 2, 2026 8 min read -
 AI Evaluation
The best eval harness for production AI and agents: A comparison
A practical comparison of production AI evaluation harnesses, including what to look for across instrumentation, evaluators, online evals, CI gates, and agent workflows. Laurie Voss June 1, 2026 10 min read -
 AI Evaluation
How to build a better agent harness with traces and evals
Agents are easy to prototype and hard to improve. A repeatable loop of traces, evals, failed-span inspection, and targeted harness changes makes agent behavior easier to debug and… Aaron Winston May 29, 2026 14 min read -
 AI Evaluation
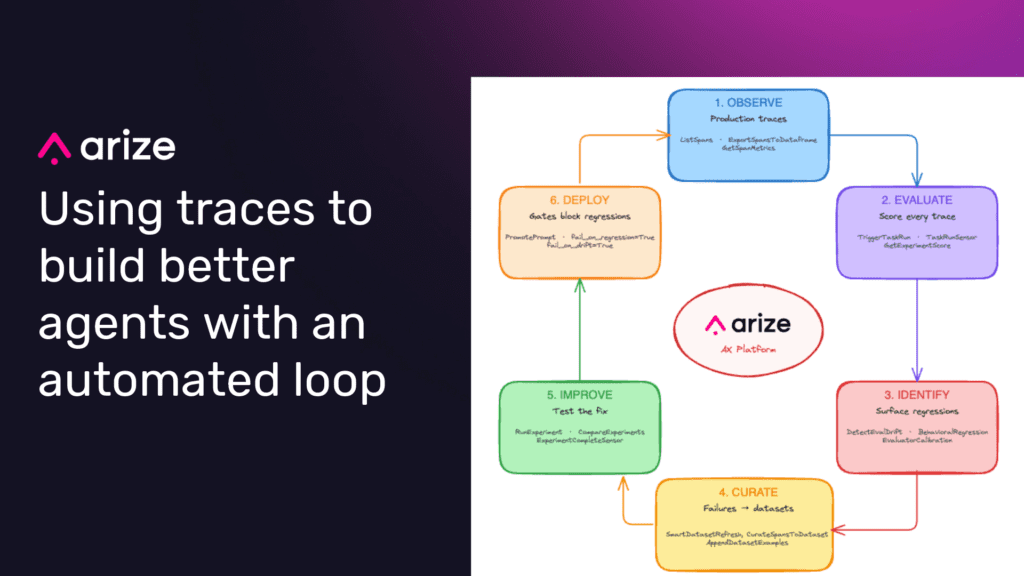
From production traces to better AI agents: Automating the LLMOps feedback loop
Production AI traces are the raw material for better evals, prompts, datasets, and fine-tuned models. This post shows how the Arize AX Airflow Provider turns that feedback loop… Jitendra Yadav Hakan Tekgul May 27, 2026 17 min read -
 AI Evaluation
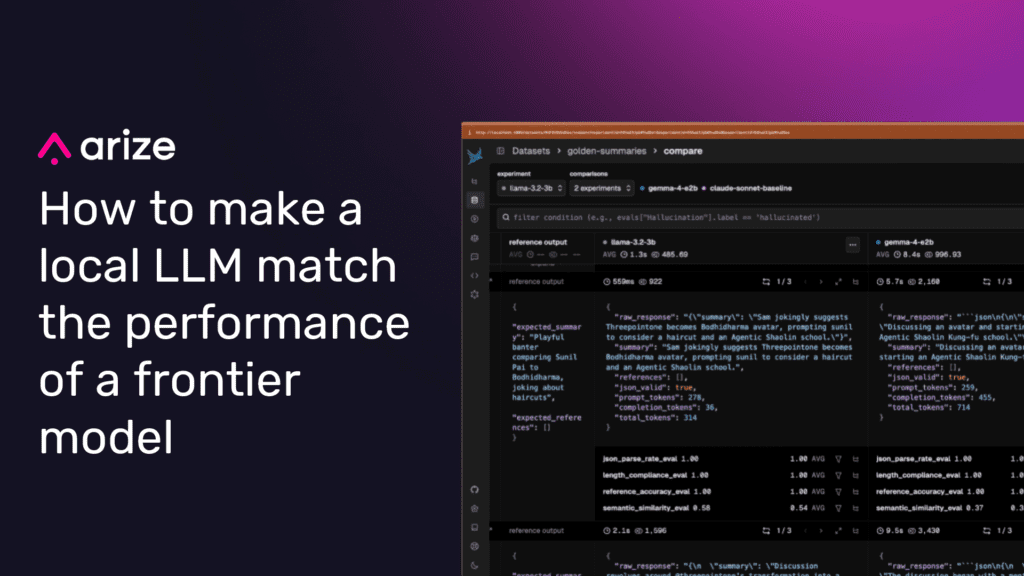
How to ship a local LLM that matches frontier LLMs with evals and prompt engineering
Most production AI features don't need a frontier model. Here's how capability evals and prompt engineering can help ship a local SLM that matches frontier-model quality with lower… RL Nabors May 26, 2026 15 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

