-
 LLM Evals
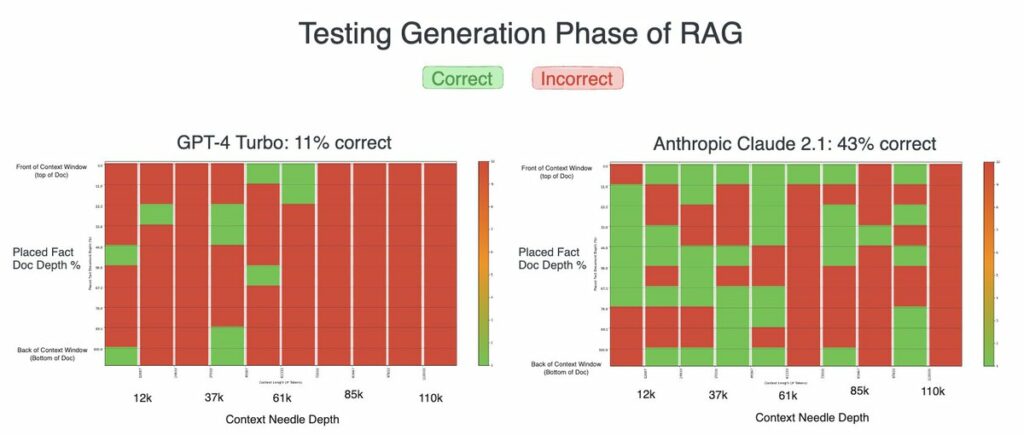
Evaluating the Generation Stage in RAG
In retrieval-augmented generation (RAG), retrieval often steals the spotlight, while the generation stage receives less attention. To address this gap, we conducted a series of tests to see… Aparna Dhinakaran February 15, 2024 4 min read -
 LLM Evals
Evaluate RAG with LLM Evals and Benchmarking
Recently, I attended a workshop organized by Arize AI titled “RAG Time! Evaluate RAG with LLM Evals and Benchmarking.” Hosted by Amber Roberts – ML Growth Lead at… Joel Bowman January 1, 2024 13 min read -
 LLM Evals
Why Enterprise Executives Should Be Hip To LLMOps Tools Heading Into the New Year
From better customer service to more rapid drug discovery, generative AI is quickly reshaping industries. According to a recent survey, 61.7% of enterprise engineering teams now have or… Cam Young December 20, 2023 3 min read -
 LLM Evals
Calling All Functions: Benchmarking OpenAI Function Calling and Explanations
This piece is co-authored by Roger Yang, Software Engineer at Arize AI Observability in third-party large language models (LLMs) is largely approached with benchmarking and evaluations since models… Amber Roberts December 7, 2023 11 min read -
 LLM Evals
Prompt Templates, Functions, and Prompt Window Management: Five Learnings From the Arize AI and PromptLayer Workshop
Introduction Prompt engineering is a crucial discipline that bridges the gap between raw model capabilities and practical, real-world applications. Recently, an enlightening event by Arize AI and PromptLayer… Shittu Olumide November 29, 2023 6 min read -
 LLM Evals
Ingesting Data for Semantic Searches in a Production-Ready Way
The current ecosystem around LLMs, semantic search and vector storage makes it easy to prototype but difficult to move into production. Ingesting large volumes of data specifically for… David Garnitz November 8, 2023 10 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

