-
 LLM Evals
Hamel Husain explains why AI evals fail before the evaluation begins
Hamel Husain explains why ambiguous inputs, generic metrics, and disconnected review workflows can make AI evaluations misleading, and how developers can build a better process around real production… Sara Verdi July 30, 2026 7 min read -
 LLM Evals
How do you make an LLM, anyway? Microsoft just published a textbook.
Microsoft published a 109-page technical report on MAI-Thinking-1. Here’s the abbreviated version of how a modern lab actually trains a frontier reasoning model — from scraping the web… Laurie Voss July 13, 2026 11 min read -
 LLM Evals
AI evals are a data science problem: What most teams get wrong
Hamel Husain explains why the best AI teams treat LLM judges like classifiers, not dashboards. Sara Verdi June 30, 2026 10 min read -
 LLM Evals
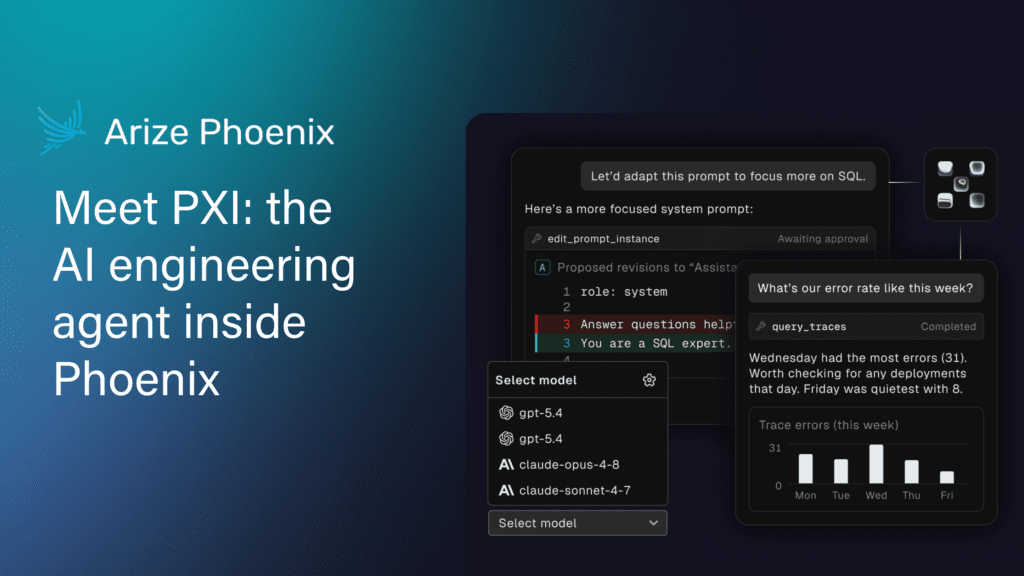
Meet PXI: the AI engineering agent inside Phoenix
An AI engineering agent built into Phoenix. It works like a coding agent, just point it at your telemetry instead of a source tree. Mikyo King Roger Yang Nancy Chauhan Anthony Powell June 18, 2026 17 min read -
 LLM Evals
How to ship a local LLM that matches frontier LLMs with evals and prompt engineering
Most production AI features don't need a frontier model. Here's how capability evals and prompt engineering can help ship a local SLM that matches frontier-model quality with lower… RL Nabors May 26, 2026 15 min read -
 LLM Evals
From First Eval to Autonomous AI Ops: A Maturity Model for AI Evaluation
Every team runs evals. Almost none have an evaluation practice. The difference is the gap between a one-off notebook and a system that continuously assesses, alerts, and acts… Cam Young April 3, 2026 6 min read -
 LLM Evals
14 best AI agent observability tools in 2026: A practical comparison
Compare 14 AI agent observability tools for tracing, evaluations, OpenTelemetry, self-hosting, pricing, and production monitoring. Updated July 2026. Aryan Kargwal February 27, 2026 29 min read -
 LLM Evals
AI Agent Debugging: Four Lessons from Shipping Alyx to Production
Building AI systems that actually work in production is harder than it sounds. Not demo-ware, not “it worked once in a notebook.” Real systems that keep working after… Laurie Voss February 25, 2026 22 min read -
 LLM Evals
ServiceNow’s Tara Bogavelli on AgentArch: Benchmarking AI Agents for Enterprise Workflows
In our latest AI research paper reading, we hosted Tara Bogavelli, Machine Learning Engineer at ServiceNow, to discuss her team’s recent work on AgentArch, a new benchmark designed… Julian Reeves October 24, 2025 4 min read -
 LLM Evals
What Are the Top LLM Evaluation Tools?
AI agents and real-world applications of generative AI are debuting at an incredible clip this year, narrowing the time from AI research paper to industry application and propelling… David Burch October 23, 2025 2 min read -
 LLM Evals
Should I Use the Same LLM for My Eval as My Agent? Testing Self-Evaluation Bias
Thanks to Aparna Dhinakaran and Elizabeth Hutton for their contributions to this piece. When building and testing AI agents, one practical question that arises is whether to use… Sanjana Yeddula October 8, 2025 10 min read -
 LLM Evals
Testing Binary vs Score Evals on the Latest Models
Thanks to Hamel Husain and Eugene Yan for reviewing this piece Evals are becoming the predominant approach for how AI engineers systematically evaluate the quality of the LLM… Aparna Dhinakaran Sri Chavali September 24, 2025 10 min read -
 LLM Evals
AI Evals Maven Course Homework: the Recipe Bot Workflow
AI Evals for Engineers & PMs is a popular, hands‑on Maven course led by Hamel Husain and Shreya Shankar. The course’s goal is simple: “teach a systematic workflow… Sri Chavali September 3, 2025 9 min read -
 LLM Evals
Evidence-Based Prompting Strategies for LLM-as-a-Judge: Explanations and Chain-of-Thought
When LLMs are used as evaluators, two design choices often determine the quality and usefulness of their judgments: whether to require explanations for decisions, and whether to use… Sri Chavali Elizabeth Hutton Aparna Dhinakaran August 20, 2025 8 min read -
 LLM Evals
Trace-Level LLM Evaluations with Arize AX
Most commonly, we hear about evaluating LLM applications at the span level. This involves checking whether a tool call succeeded, whether an LLM hallucinated, or whether a response… Sanjana Yeddula August 20, 2025 3 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

