LLM benchmarks, agent evaluations, and experiments.
-
 Research
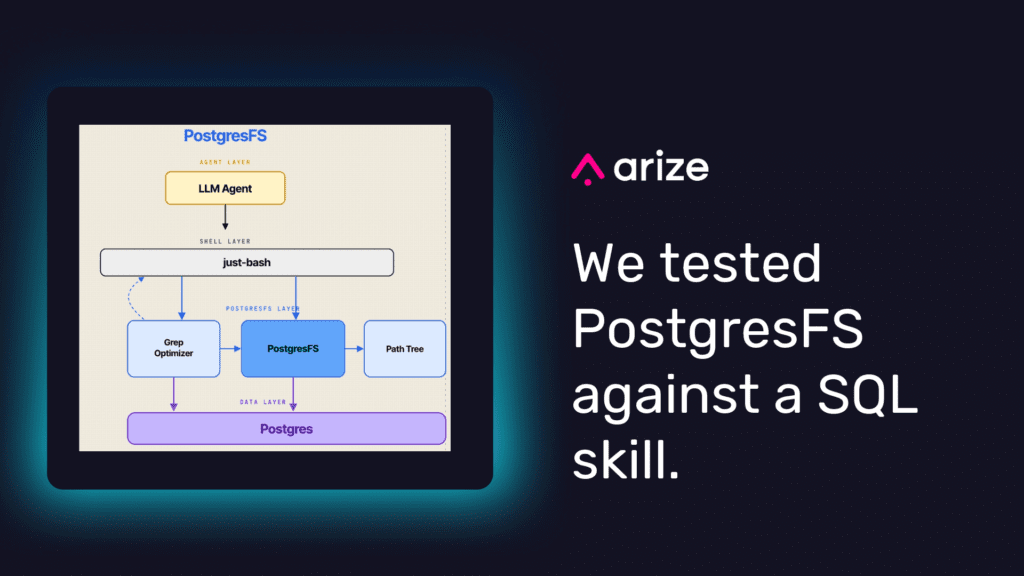
PostgresFS vs. SQL skills: should AI agents fake a filesystem?
Can an AI agent use a database as if it were a filesystem? Arize compared a Postgres-backed filesystem abstraction with a SQL skill and found that locality, accuracy,… Aparna Dhinakaran Sufjan Fana June 11, 2026 12 min read -
 Research
What we learned testing 7 models under the same agent harness
Model swaps look like configuration changes, but they behave more like product migrations. A new model may be cheaper, faster, easier to get capacity for, or stronger on… Nancy Chauhan May 20, 2026 10 min read -
 Research
Models got an order of magnitude better at following instructions in one year
A year ago, frontier models started losing track of instructions somewhere around 200–300 simultaneous constraints. With 2026 models, that ceiling is closer to 2,000 — an order-of-magnitude jump.… Laurie Voss May 12, 2026 11 min read -
 Research
Agent harnesses have an expiration date
A benchmark-driven look at why agent harnesses need adaptive finish logic as model behavior changes across Claude, GPT-4o, and Gemma. RL Nabors May 7, 2026 11 min read -
 Research
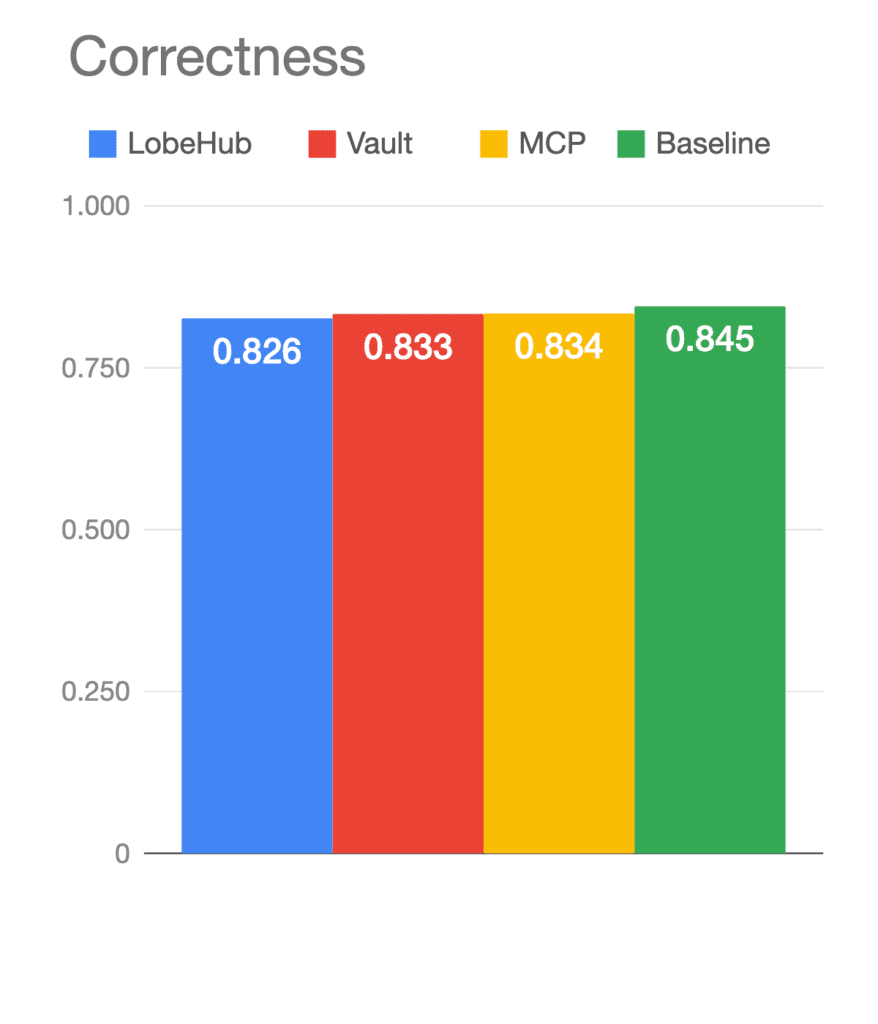
MCP vs. CLI Skills for agents: what our eval found (and which you should use)
Twitter said pick a side. The eval said the question was wrong. Six months ago, MCP (model context protocol) was the hot new thing: tool usage with a… Laurie Voss May 1, 2026 10 min read -
 Research
CLAUDE.md Best Practices for Claude Code
In our last post on Prompt Learning (our prompt optimization feature), we optimized Cline, a powerful coding agent, through its system prompt. This time, we used it on… Priyan Jindal November 20, 2025 9 min read -
 Research
GEPA vs Prompt Learning: Benchmarking Different Prompt Optimization Approaches
In June 2025, Andrej Karpathy introduced Software 3.0: the notion that software development is shifting from programming through code to prompting through natural language. When building programs, the… Priyan Jindal November 17, 2025 11 min read -
 Research
Meta AI Researcher Explains ARE and Gaia2: Scaling Up Agent Environments and Evaluations
In our latest paper reading, we had the pleasure of hosting Grégoire Mialon — Research Scientist at Meta Superintelligence Labs — to walk us through Meta AI’s groundbreaking… David Burch November 6, 2025 4 min read -
 Research
ServiceNow’s Tara Bogavelli on AgentArch: Benchmarking AI Agents for Enterprise Workflows
In our latest AI research paper reading, we hosted Tara Bogavelli, Machine Learning Engineer at ServiceNow, to discuss her team’s recent work on AgentArch, a new benchmark designed… Julian Reeves October 24, 2025 4 min read -
 Research
OpenAI’s Santosh Vempala Explains Why Language Models Hallucinate
In our latest AI research paper reading, we hosted Santosh Vempala, Professor at Georgia Tech and co-author of OpenAI’s paper, “Why Language Models Hallucinate.” This paper offers one… Julian Reeves October 24, 2025 4 min read -
 Research
Optimizing Coding Agent Rules (./clinerules) for Improved Accuracy
Coding agents have become the focal point of modern software development. Tools like Cursor, Claude Code, Codex, Cline, Windsurf, Devin, and many more are revolutionalizing how engineers write… Priyan Jindal October 14, 2025 10 min read -
 Research
Should I Use the Same LLM for My Eval as My Agent? Testing Self-Evaluation Bias
Thanks to Aparna Dhinakaran and Elizabeth Hutton for their contributions to this piece. When building and testing AI agents, one practical question that arises is whether to use… Sanjana Yeddula October 8, 2025 10 min read -
 Research
Sleep-time Compute: Beyond Inference Scaling at Test-time
We recently discussed “Sleep Time Compute: Beyond Inference Scaling at Test Time,” new research from the team at Letta. The paper addresses a key challenge in using powerful… Sarah Welsh May 7, 2025 5 min read -
 Research
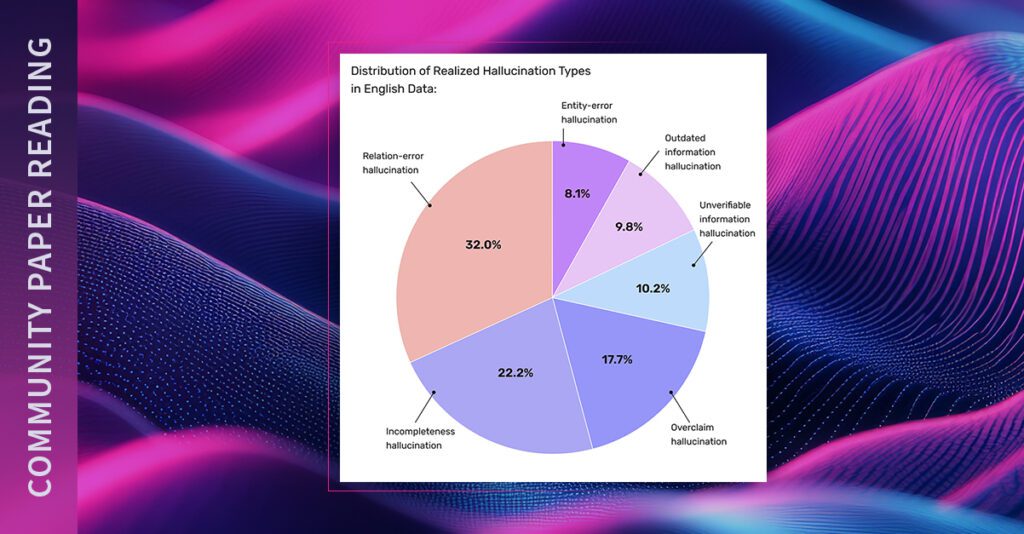
LibreEval: A Smarter Way to Detect LLM Hallucinations
Over the past few weeks, the Arize team has generated the largest public dataset of hallucinations, as well as a series of fine-tuned evaluation models. We wanted to… Sarah Welsh April 21, 2025 4 min read -
 Research
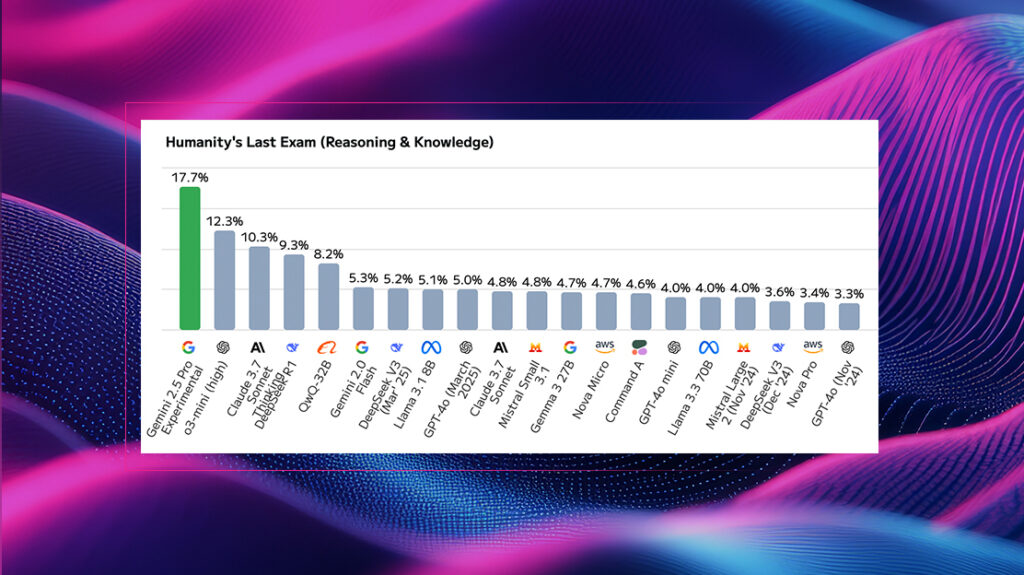
AI Benchmark Deep Dive: Gemini 2.5 and Humanity’s Last Exam
Our latest paper reading provided a comprehensive overview of modern AI benchmarks, taking a close look at Google’s recent Gemini 2.5 release and its performance on key evaluations,… Sarah Welsh April 4, 2025 6 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

