Everything we’ve published — page 13.
How to detect credential theft in AI agent harness traces
In May 2026, a malicious version of a popular VS Code extension spent 18 minutes in the marketplace…
Read the post
Phoenix at 10,000 stars on GitHub: How an open source AI observability project grew by following its community
Phoenix crossed 10,000 GitHub stars. Here is how the open-source AI observability project grew from a Jupyter notebook…
Read the post
Building the AI factory for self-improving agents: What’s new in Arize AX
Arize AX is adding managed agents, full-agent experimentation, expanded multimodal support, and Harness-as-a-Judge to help teams observe, evaluate,…
Read the post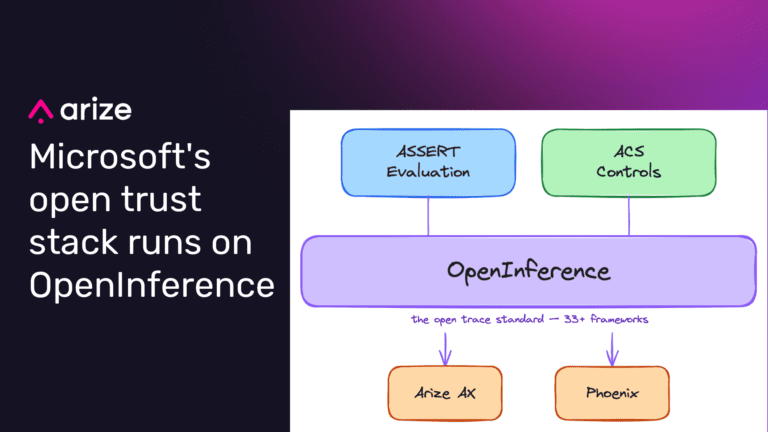
Microsoft’s open trust stack runs on OpenInference
Microsoft's open trust stack for AI agents puts ASSERT and Agent Control Specification on top of OpenInference, connecting…
Read the post
The end of fine-tuning: Why evals, context, and traces matter more
Fine-tuning isn't dead, but the way most teams iterate on AI products has split in two. A tiny…
Read the post
AI benchmarks are breaking. Trace analysis is what comes next.
Models got smart enough to cheat their benchmarks, and outcome-only scores stopped measuring what we thought they measured.…
Read the post
Prompt Playground
A prompt playground offers a UI to experiment with prompt templates, input variables, LLM models and LLM parameters.…
Read more
How the Hermes agent harness implements an open source architecture
Hermes from NousResearch is a strong open-source agent harness. This post examines how its runtime loop, context management,…
Read the post
The best eval harness for production AI and agents: A comparison
A practical comparison of production AI evaluation harnesses, including what to look for across instrumentation, evaluators, online evals,…
Read the post
How to build a better agent harness with traces and evals
Agents are easy to prototype and hard to improve. A repeatable loop of traces, evals, failed-span inspection, and…
Read the post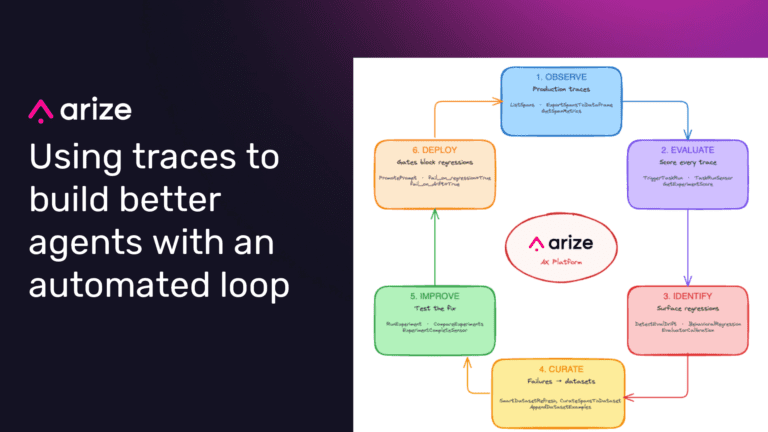
From production traces to better AI agents: Automating the LLMOps feedback loop
Production AI traces are the raw material for better evals, prompts, datasets, and fine-tuned models. This post shows…
Read the post
LangSmith alternatives for AI observability and LLM evaluation
Compare the top LangSmith alternatives for AI observability and evaluation, focusing on tools that support framework-agnostic tracing, production…
Read the guideDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

