Everything we’ve published — page 2.
How to test agent tool descriptions with Harbor and Phoenix
Build a reproducible benchmark, compare tool use across agents, and test whether a description change reduces unnecessary work…
Read the post
Alignment is a human-AI workflow: how Custom Views make agent review possible
Automated evals can score every agent session, but they do not automatically reflect what your team considers a…
Read the post
Cost Agent: find where your LLM and agent spend goes with your traces
AI costs don’t always scale predictably with traffic. A retry loop, oversized context window, or unnecessarily expensive model…
Read the post
Agent-as-a-Judge: A practical guide to agentic evaluation
Learn when to use an agent judge, how it differs from LLM-as-a-Judge, and how to write, validate, and…
Read the guide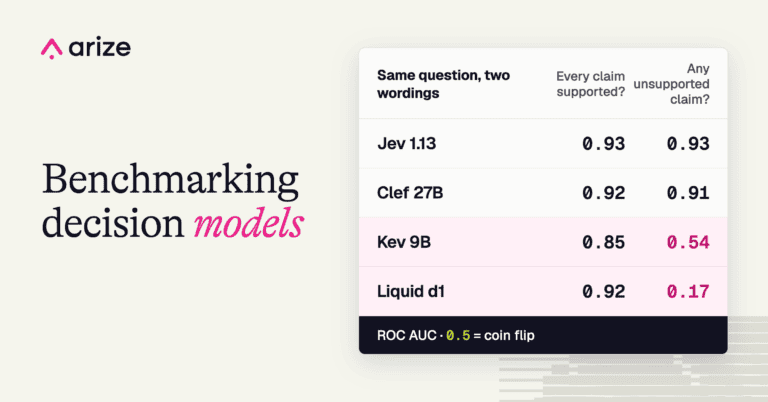
Decision model benchmark: Jev, Kev, Liquid d1, and more
On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that…
Read the post
Real-time intervention for supplier transfers with Wilma
See how Wayfair built Wilma, an LLM-powered system that monitors supplier support in real time, improving accuracy and…
Read the story
AI governance and security costs: what to budget for
Learn what drives AI governance and security costs, including controls, evaluation, human review, incidents, lifecycle changes, and production…
Read the guide
What agent traces can tell you without an LLM judge
Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI,…
Read the post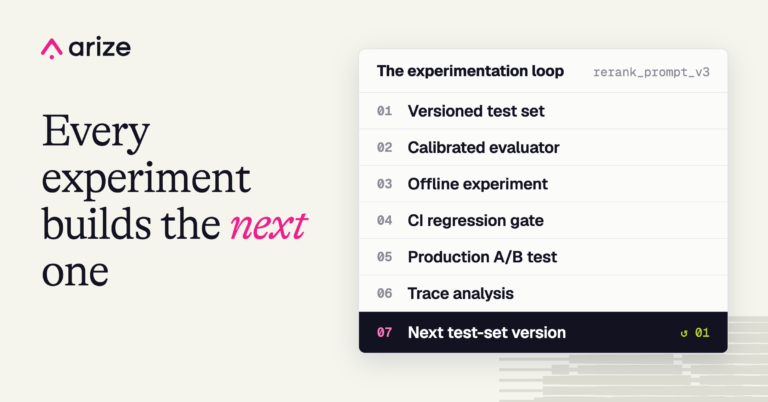
How to A/B test AI agents with an experimentation loop
Test agent changes with versioned test sets, calibrated evaluators, offline experiments, CI gates, production A/B tests, and trace-level…
Read the guide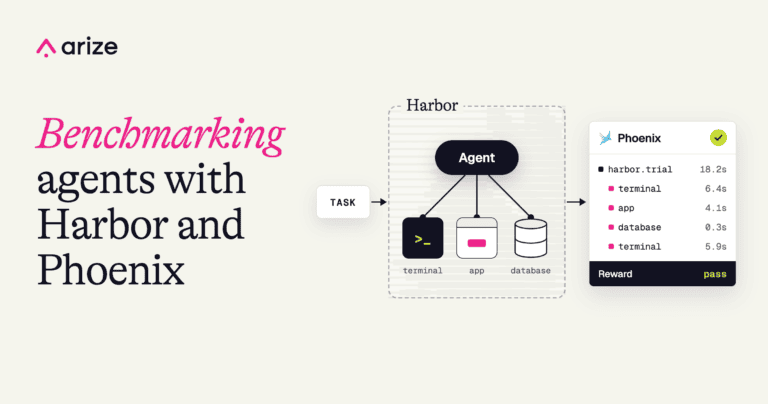
How we benchmark AI agents and tools with Harbor and Arize Phoenix
See how Arize uses Harbor and Phoenix to benchmark AI agents, MCP servers, skills, and CLIs in reproducible…
Read the post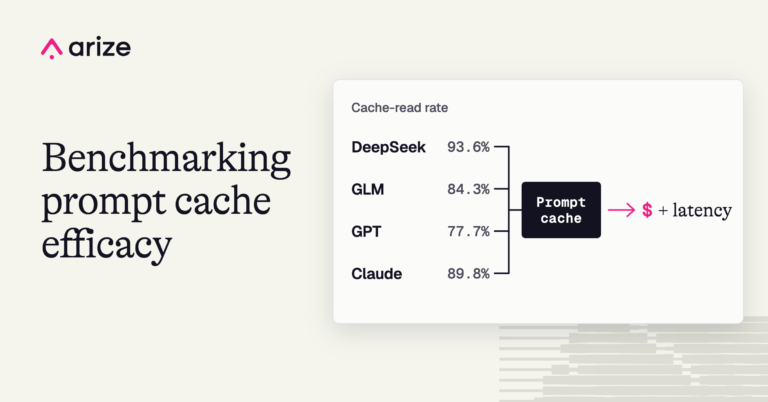
Prompt caching benchmark: high cache reuse doesn’t always mean lower cost
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we…
Read the post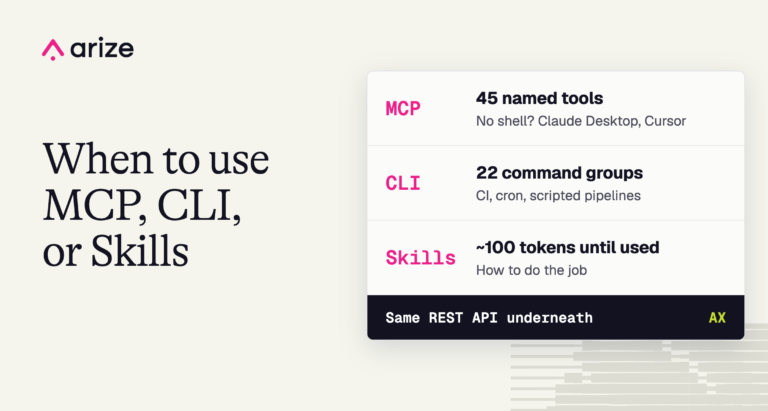
Introducing Arize AX MCP: When to use MCP, CLI, or skills
MCP, CLI, and skills are three ways to extend an agent with the same platform. The question is…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

