Everything we’ve published — page 3.
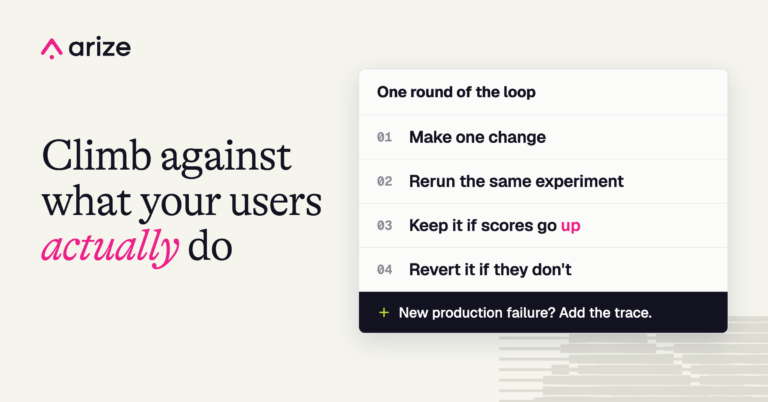
Claude’s hillclimb loop for AI agents: start with production traces
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run…
Read the post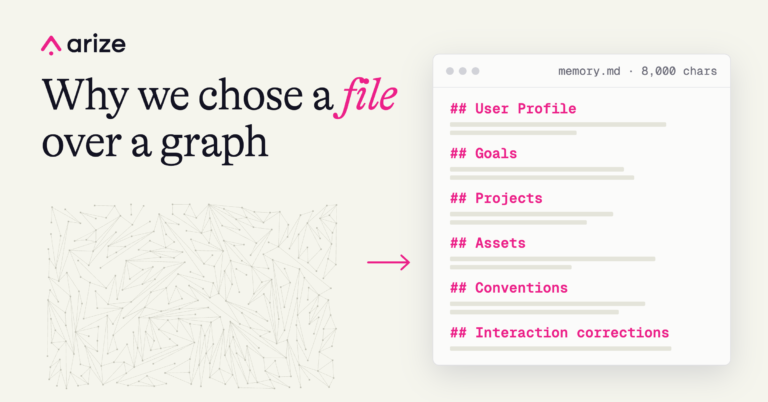
How we built long-term memory for Alyx: why we chose a file over a knowledge graph
How we built long-term memory for Alyx: why we chose one 8,000-character file over retrieval and knowledge graphs,…
Read the post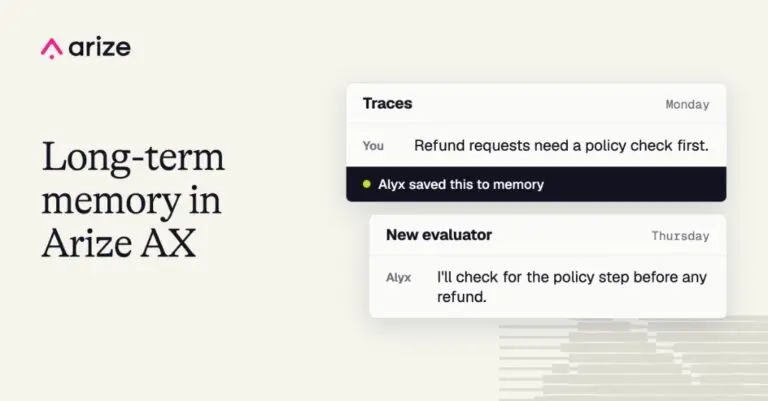
Alyx now remembers your work across sessions with long-term memory
Alyx now remembers project goals, conventions, and decisions across sessions in Arize AX, helping you continue work on…
Read the post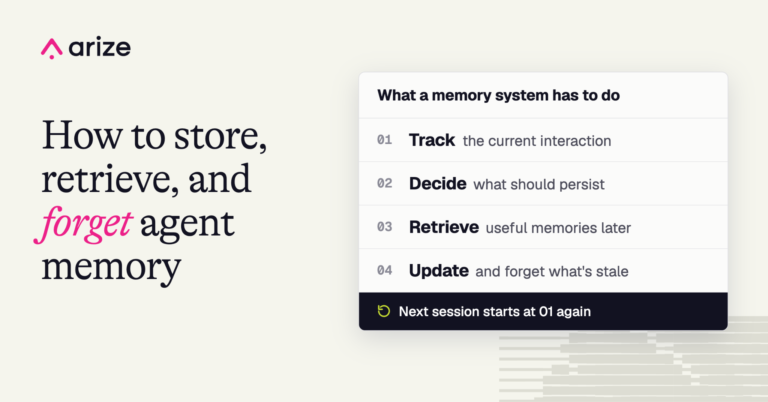
AI agent memory systems: how long-term memory works
Learn how AI agent memory works, including long-term memory, profiles, vector retrieval, knowledge graphs, memory architecture, tools, and…
Read the guide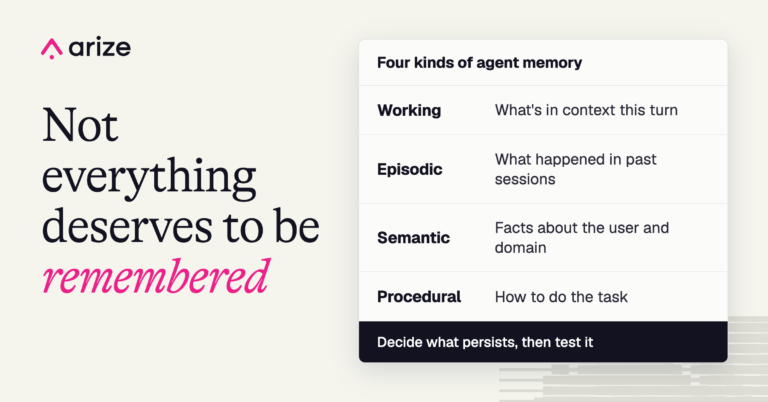
AI memory: types, architecture, and how memory works in AI agents
Learn how AI memory works in agents, including working, episodic, semantic, and procedural memory, architecture patterns, retrieval, updating,…
Read the guide
NVIDIA proposes an AI agent kill switch in silicon after a year of sandbox escapes
This year agents at OpenAI, Anthropic, and Google escaped environments meant to contain them. What decided severity was…
Read the post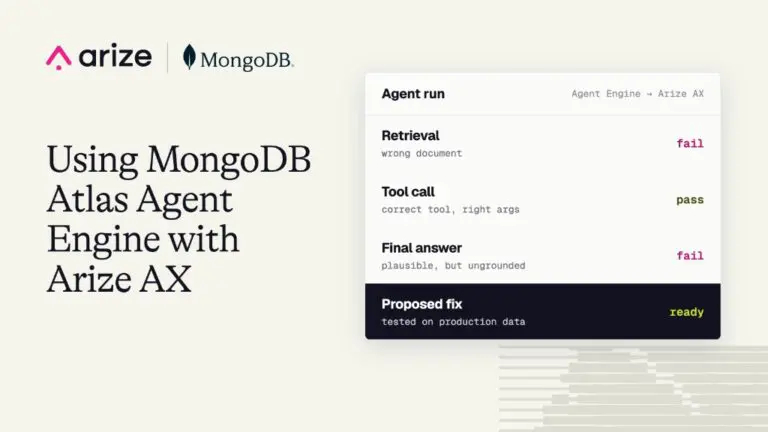
Building production-ready AI agents with Atlas Agent Engine and Arize AX
Agents built and deployed on MongoDB’s Atlas Agent Engine can export OpenTelemetry traces to Arize AX, where teams…
Read the post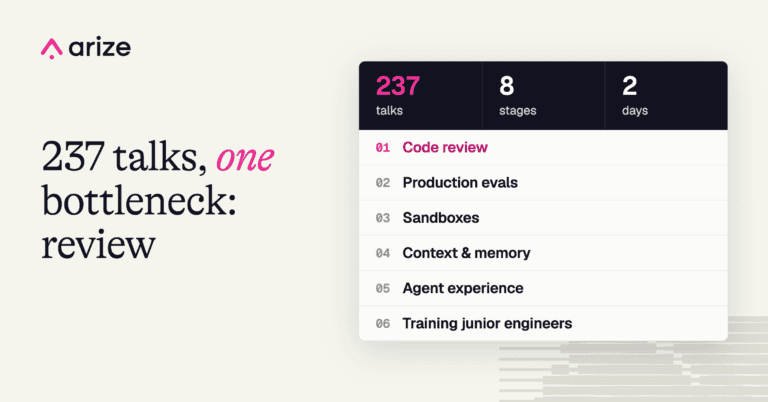
What everyone was talking about at WeAreDevelopers World Congress North America
After 237 talks across eight stages, code review emerged as the bottleneck for AI-generated code. Here are the…
Read the post
Are agent harnesses dying? What harness distillation changes
Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to…
Read the post
Anthropic says it fixed Claude’s writing. I ran the evals to check.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the…
Read the post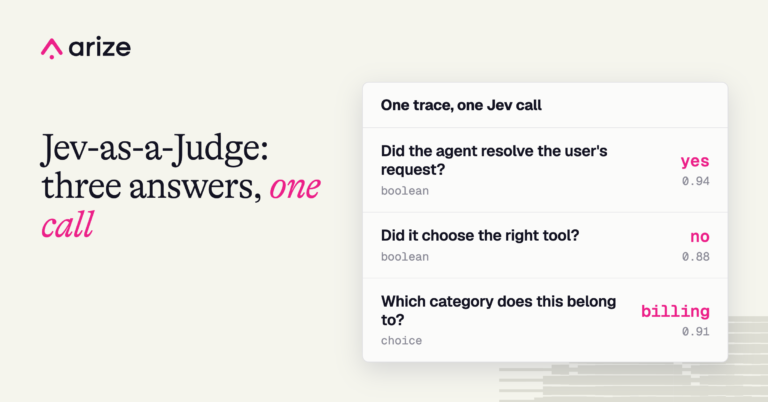
Evaluate production traces with Jev-as-a-Judge directly in Arize AX
Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow.
Read the post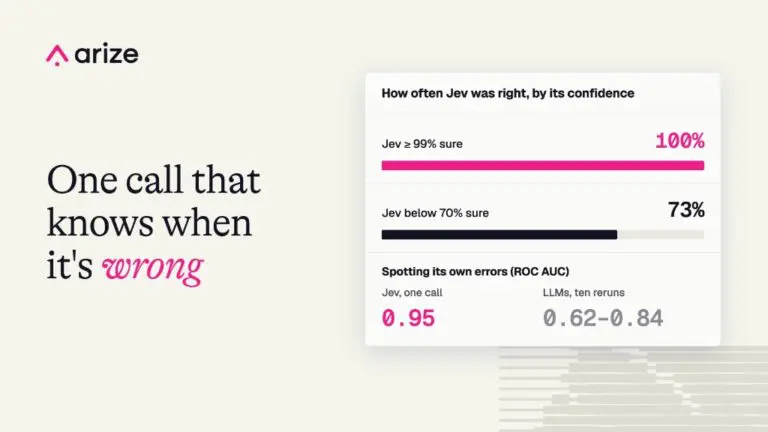
What Jev’s probabilities reveal that repeated LLM judgments miss
I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

