Everything we’ve published — page 4.
How we built UI Code Mode into Arize Phoenix
We replaced the 58 tools PXI used to drive the Phoenix UI with two tools and a JavaScript…
Read the post
How Atropos Health uses Arize AX for LLM observability in medical research
Principal Data Scientist Rebecca Hyde on moving beyond “good enough” AI and building a measurement framework for LLM-generated…
Read the story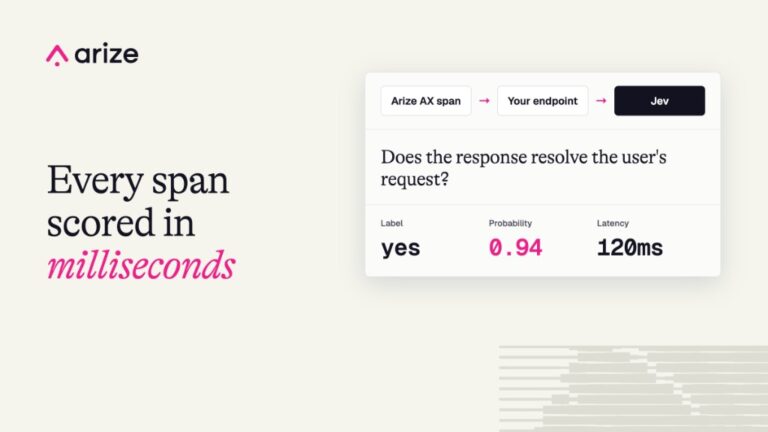
How to build a remote evaluator in Arize AX with Jev
Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and…
Read the post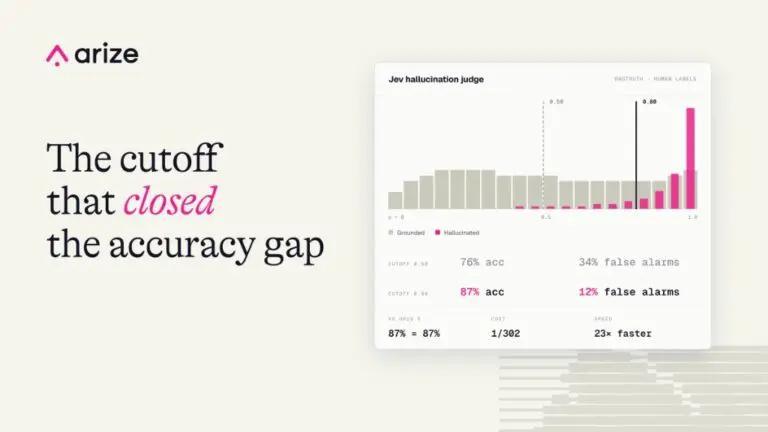
Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks
We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold…
Read the post
How to choose an AI observability platform
Learn how to choose an AI observability platform in 2026, with evaluation criteria for tracing, evals, monitoring, pricing…
Read the guide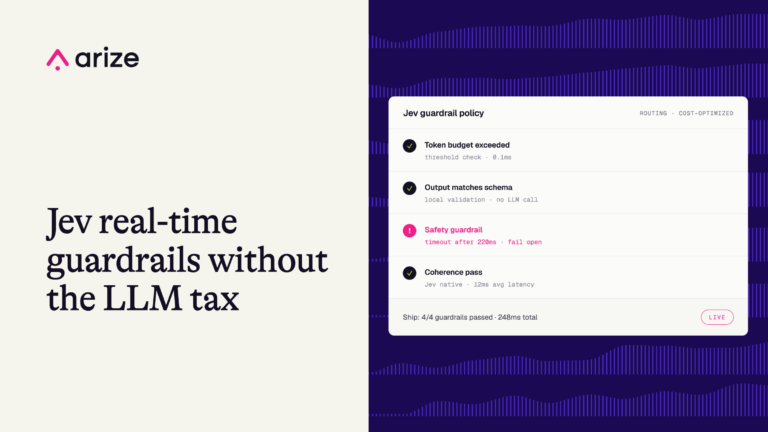
Real-time LLM guardrails with Jev: comparing latency and cost
Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on…
Read the post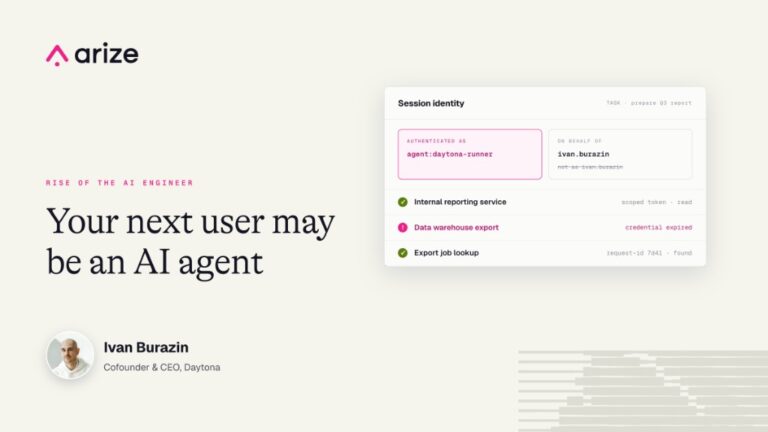
What changes when AI agents use your software
Daytona cofounder Ivan Burazin wants agents that can finish the job within the authority they have been given.…
Read the post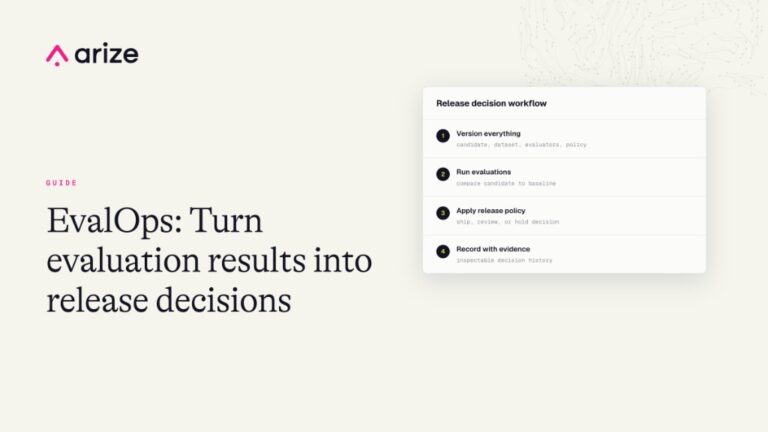
EvalOps: How to build AI evaluation release gates
Learn how to turn AI evaluations into release gates with a worked agent example, ship/review/hold criteria, and a…
Read the guide
Arize AX in September 2026: first-class sessions, Agent-as-a-Judge, and vision evals
Sessions are now a first-class unit of work in Arize AX. Annotate a whole conversation, queue it for…
Read the post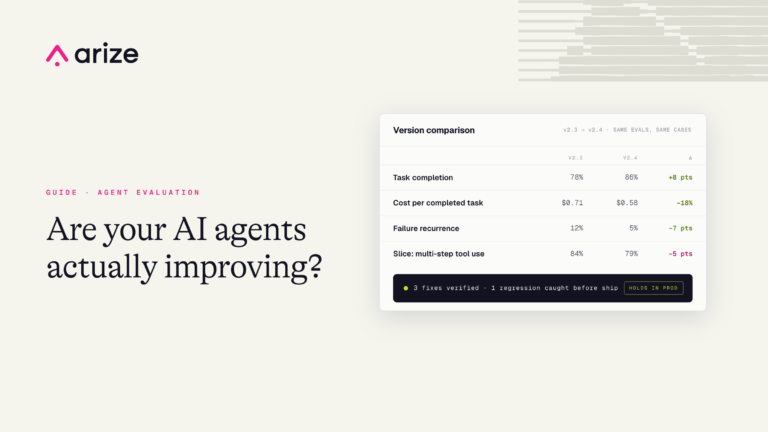
How to evaluate whether your AI agents are actually improving
Measure AI agent improvement with task completion, cost per completed task, regression checks, and consistent before-and-after evaluations.
Read the guide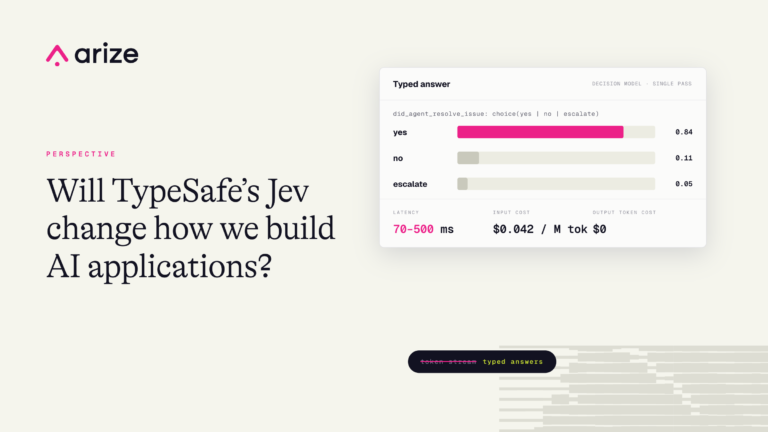
TypeSafe’s Jev: Can decision models replace LLM judges?
TypeSafe’s Jev classifies, scores, and routes without generating text — up to hundreds of times cheaper than an…
Read the post
AI governance in banking: How to scale AI agents
Banking agents can fail in ways that error dashboards miss: a credit memo cites the wrong figure, an…
Read moreDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

