All articles
Everything we’ve published — page 6.
-
 AI Evaluation
How to measure AI productivity: From LLM token costs to business value with Arize AX
AI productivity is best measured by connecting AI usage to validated downstream outcomes. Tokens, prompts, and generated lines show activity, but they do not prove value. A better… Duncan McKinnon Jitendra Yadav July 14, 2026 9 min read -
 AI Evaluation
How do you make an LLM, anyway? Microsoft just published a textbook.
Microsoft published a 109-page technical report on MAI-Thinking-1. Here’s the abbreviated version of how a modern lab actually trains a frontier reasoning model — from scraping the web… Laurie Voss July 13, 2026 11 min read -
 Agent Engineering
3 production patterns for AI agents and how to evaluate each one
A local coding agent, an in-app customer assistant, and an AI SRE triaging production logs may all use the same model class—but not the same harness, eval plan,… Sara Verdi July 10, 2026 9 min read -
 Agent Engineering
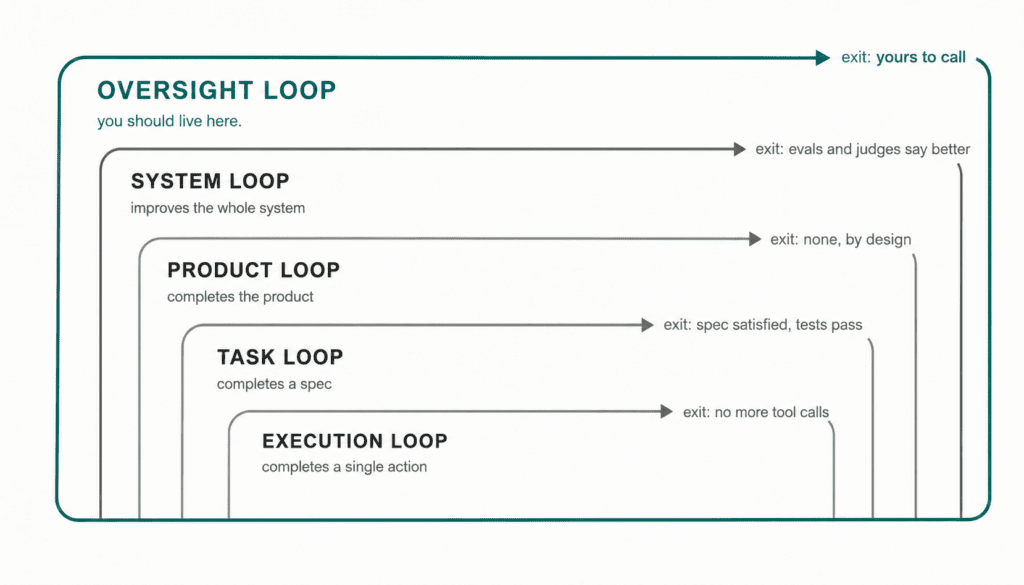
What is a loop in AI engineering, anyway?
The AI engineering world is using “loop” to describe several different agent architectures. This post maps execution loops, task loops, product loops, system loops, and the human oversight… Aparna Dhinakaran Laurie Voss July 10, 2026 10 min read -
 Agent Evaluation
Trace before you migrate: Measuring Kubernetes bottlenecks in AI agent sandboxes
Kubernetes is strong for long-lived services, but it is often a poor default for short-lived agent sandboxes. Trace sandbox creation, tool execution, eval latency, and full trajectory time… Sara Verdi July 9, 2026 7 min read -
 Agent Evaluation
The agent is the user now: lessons from the founder of WorkOS
WorkOS founder Michael Grinich explains why the next era of AI engineering depends on the systems around agents: identity, permissions, evals, memory, and feedback loops that keep autonomous… Aaron Winston July 8, 2026 9 min read -
 AI Evaluation
Evals in CI: How to write your LLM evals as tests with Arize Phoenix
If you're struggling to get started with evals, you're not alone. This post explains how to write LLM evals as ordinary tests in CI with Phoenix, pytest, and… Mikyo King July 7, 2026 17 min read -
 Agent Engineering
Own the loop: A field guide to agent harnesses
As models become cheaper and more interchangeable, the durable advantage shifts to the agent harness: the loop, tools, memory, permissions, and workflow you can own and refine. Aparna Dhinakaran July 6, 2026 8 min read -
 Agent Evaluation
How to evaluate AI agents, avoid reward hacking, and build better specs
Agent evals are repeatable tests that score whether AI agents completed a task correctly. Learn how to design rubrics, test suites, and trace-based evals that catch failures and… Sara Verdi July 2, 2026 9 min read -
 Agent Evaluation
Model subsidies are ending. What do you do now?
Flat-rate AI plans are subsidizing agentic workloads. Learn why LLM inference costs are moving to metered pricing and how evals reveal cost per successful task. Laurie Voss July 1, 2026 8 min read -
 AI Evaluation
AI evals are a data science problem: What most teams get wrong
Hamel Husain explains why the best AI teams treat LLM judges like classifiers, not dashboards. Sara Verdi June 30, 2026 10 min read -
 Agent Observability
Trace and evaluate TrueFoundry AI Gateway traffic in Arize AX
Learn how TrueFoundry AI Gateway exports OpenTelemetry traces to Arize AX so teams can trace, evaluate, and monitor production LLM and agent traffic without embedding a vendor SDK… Aaron Winston June 29, 2026 7 min read -
 Agent Evaluation
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
A field guide to the new wave of long-horizon agent benchmarks: what each one actually measures, the realism-versus-verifiability bargain it strikes, and the seam where its score leaks. Jim Bennett June 24, 2026 14 min read -
 Agent Observability
Project Rosetta Stone: a reference implementation for instrumenting agents in any framework
We've fielded the same question at every conference this year. An engineer has chosen a framework, CrewAI one week, LangGraph the next, Mastra the week after, and wants… Jim Bennett June 22, 2026 6 min read -
 Agent Engineering
Why AI token costs don’t tell you if your AI is working
Token spend does not prove AI is creating value. Teams need cost-per-outcome metrics that connect AI usage to resolved tickets, accepted code, shipped features, and other business results. Laurie Voss June 19, 2026 9 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

