-
 AI Evaluation
Mastering Production RAG with Google ADK and Arize AX for Enterprise Knowledge Systems
Introduction Retrieval Augmented Generation (RAG) has become the cornerstone of enterprise AI, yet most organizations struggle with a critical challenge: building RAG systems that work reliably in production.… Richard Young February 23, 2026 11 min read -
 AI Evaluation
Closing the Loop: Coding Agents, Telemetry, and the Path to Self-Improving Software
2025 marked the widespread adoption of coding agents — harnesses that autonomously write, test, and debug changes to software with minimal human intervention. Products like Claude Code, Codex,… Mikyo King February 17, 2026 9 min read -
 AI Evaluation
Inside Typeform’s AI Agent Stack
Typeform is building generative AI experiences to help customers create better forms faster and to make collecting insights feel more natural and useful end-to-end. In this Q&A, Marta… David Burch February 17, 2026 6 min read -
 AI Evaluation
CUGA Agent: From Benchmarks to Business Impact of IBM’s Generalist Agent
This paper reading features several of the researchers — including Segev Shlomov (PhD), Ido Levy, Asaf Adi, and Avi Yaeli — behind the widely acclaimed paper “From Benchmarks… David Burch February 11, 2026 1 min read -
 AI Evaluation
Top Generative AI Conferences In 2026 for Engineers
GenAI stacks are shifting fast enough that staying current is an ongoing project, not a quarterly refresh. The hard part is separating durable engineering practices (evals, reliability, cost… David Burch February 10, 2026 10 min read -
 AI Evaluation
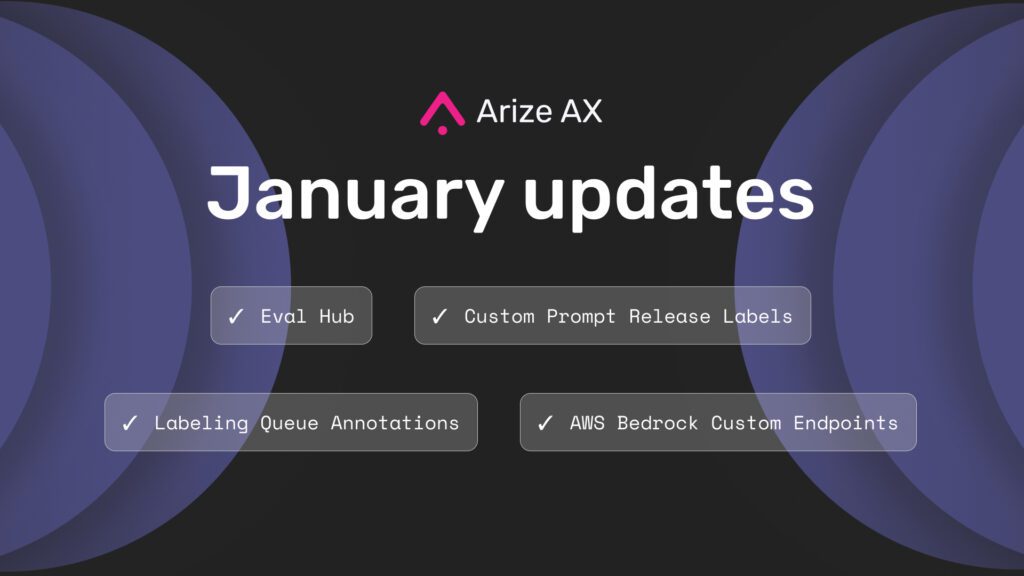
New In Arize AX: January 2026 Updates
Arize AX pushed out a lot of new updates in January 2026. From improved evaluator hub to custom prompt release labels, here are some highlights. Evaluator Hub: Reusable… Sanjana Yeddula February 2, 2026 8 min read -
 AI Evaluation
Evaluating and Improving AI Agents at Scale with Microsoft Foundry
The Case for Continuous AI Quality As generative and agentic systems mature, the question for enterprises is no longer simply “can we build it?” It is “can we… Richard Young November 18, 2025 13 min read -
AI Evaluation
Tracing, Evaluation, and Observability for Google ADK (How To)
Multi-agent systems are moving from research prototypes to production deployments. But there’s a gap between “it works in the demo” and “it works reliably at scale.” Google’s Agent… Richard Young November 14, 2025 11 min read -
 AI Evaluation
Meta AI Researcher Explains ARE and Gaia2: Scaling Up Agent Environments and Evaluations
In our latest paper reading, we had the pleasure of hosting Grégoire Mialon — Research Scientist at Meta Superintelligence Labs — to walk us through Meta AI’s groundbreaking… David Burch November 6, 2025 4 min read -
 AI Evaluation
8 top prompt testing & optimization tools (2026)
Your agent still returns HTTP 200. It also started choosing the wrong tool, passing malformed arguments, and skipping an escalation rule that worked last week. Prompt changes can… Trent Fowler October 28, 2025 23 min read -
 AI Evaluation
ServiceNow’s Tara Bogavelli on AgentArch: Benchmarking AI Agents for Enterprise Workflows
In our latest AI research paper reading, we hosted Tara Bogavelli, Machine Learning Engineer at ServiceNow, to discuss her team’s recent work on AgentArch, a new benchmark designed… Julian Reeves October 24, 2025 4 min read -
 AI Evaluation
OpenAI’s Santosh Vempala Explains Why Language Models Hallucinate
In our latest AI research paper reading, we hosted Santosh Vempala, Professor at Georgia Tech and co-author of OpenAI’s paper, “Why Language Models Hallucinate.” This paper offers one… Julian Reeves October 24, 2025 4 min read -
 AI Evaluation
What Are the Top LLM Evaluation Tools?
AI agents and real-world applications of generative AI are debuting at an incredible clip this year, narrowing the time from AI research paper to industry application and propelling… David Burch October 23, 2025 2 min read -
 AI Evaluation
Should I Use the Same LLM for My Eval as My Agent? Testing Self-Evaluation Bias
Thanks to Aparna Dhinakaran and Elizabeth Hutton for their contributions to this piece. When building and testing AI agents, one practical question that arises is whether to use… Sanjana Yeddula October 8, 2025 10 min read -
 AI Evaluation
New In Arize AX: Session and Trace Evals, Alyx’s Synthetic Data Generation, and more
September was a busy month product-wise for Arize AX, with updates to make AI agent engineering faster and easier. From session and trace evals to Alyx’s new synthetic… Sanjana Yeddula October 6, 2025 3 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

