-
 Open Source
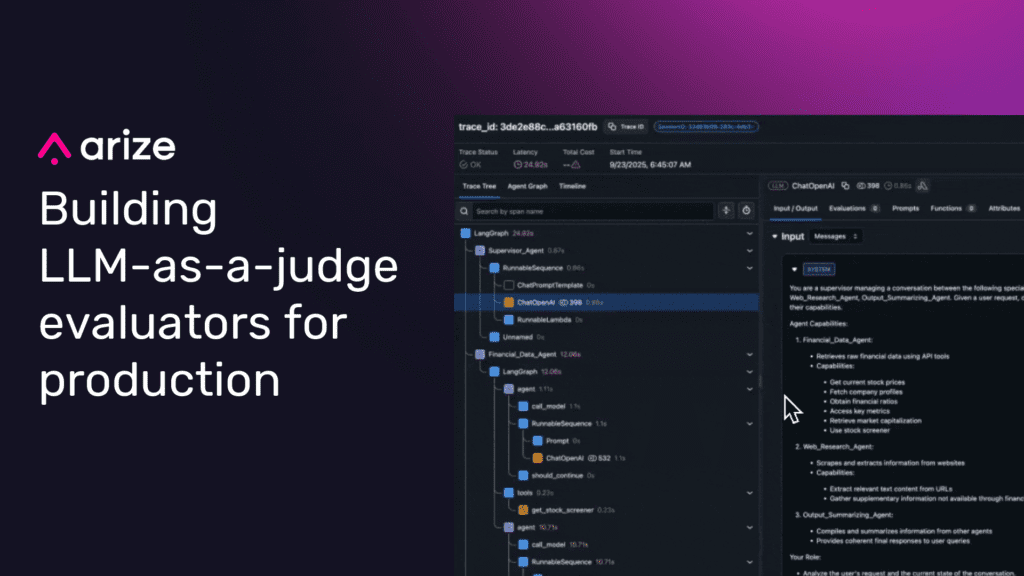
How to build LLM-as-a-Judge evaluators that hold up in production
Learn how to design, calibrate, and run LLM-as-a-judge evaluators with fixed labels, human agreement checks, trace context, and Phoenix Evals. Aaron Winston May 21, 2026 22 min read -
 Open Source
Coding agent tracing and evaluation: An open source tool to improve AI coding workflows
Announcing coding harness tracing for observing, evaluating, and improving coding agent workflows across Claude Code, Cursor, Codex, GitHub Copilot, and Gemini CLI. Duncan McKinnon Chris Cooning Fuad Ali May 18, 2026 5 min read -
 Open Source
From observability to context: What’s next for Arize Phoenix
As agents start changing software, they need a way to verify their work that includes traces, evals, feedback, and APIs. This is where Phoenix goes next — not… Mikyo King Elizabeth Hutton May 11, 2026 10 min read -
 Open Source
Why agent telemetry needs standards
Enterprise agents are moving from demos into production workflows, which creates a basic problem: teams need to understand what those agents actually did. Richard Young May 1, 2026 6 min read -
 Open Source
How We Used Evals (and an AI Agent) to Iteratively Improve an AI Newsletter Generator
We love building little AI-powered tools that accelerate our workflows. One we built recently is a tool that takes our recent tweets and uses Claude to create a… Laurie Voss March 10, 2026 10 min read -
 Open Source
Add Observability to Your Open Agent Spec Agents with Arize Phoenix
Open Agent Specification lets you define an agent once and run it on any compatible runtime: LangGraph, WayFlow, CrewAI, and others. That portability solves a real problem in… Laurie Voss February 27, 2026 7 min read -
 Open Source
How America First Credit Union Built a GenAI “Decision Explainer” — With Tracing That Scales
America First Credit Union is one of America’s largest independent credit unions, with 1.5 million members and more than $20 billion worth of deposits. As America First Credit… Greg Chase February 19, 2026 3 min read -
 Open Source
How Observability-Driven Sandboxing Secures AI Agents
AI agents become dangerous at the moment they gain the ability to execute actions. The moment an agent can touch the file system or invoke external tools, safety… Aryan Kargwal January 22, 2026 11 min read -
 Open Source
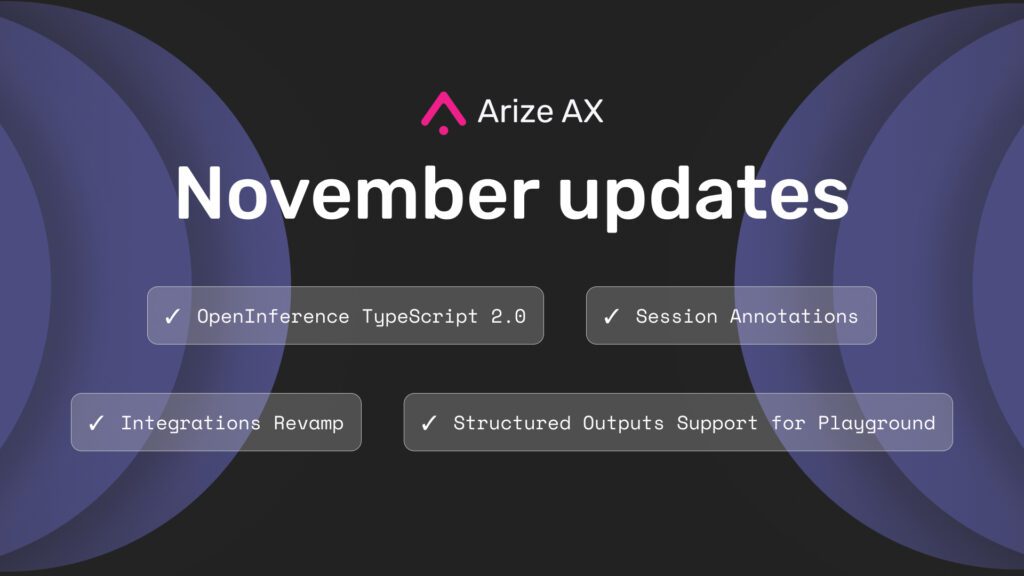
New In Arize AX: OpenInference TypeScript 2.0, Session Annotations, Integrations Revamp
Arize AX released a flurry of updates in November of 2025. From OpenInference TypeScript 2.0 to a revamp of integrations, there is a lot to catch up on.… Sanjana Yeddula December 4, 2025 3 min read -
 Open Source
ServiceNow’s Tara Bogavelli on AgentArch: Benchmarking AI Agents for Enterprise Workflows
In our latest AI research paper reading, we hosted Tara Bogavelli, Machine Learning Engineer at ServiceNow, to discuss her team’s recent work on AgentArch, a new benchmark designed… Julian Reeves October 24, 2025 4 min read -
 Open Source
New In Arize AX: Session and Trace Evals, Alyx’s Synthetic Data Generation, and more
September was a busy month product-wise for Arize AX, with updates to make AI agent engineering faster and easier. From session and trace evals to Alyx’s new synthetic… Sanjana Yeddula October 6, 2025 3 min read -
 Open Source
Orchestrator-Worker Agents: A Practical Comparison of Common Agent Frameworks
— Technical deep dive inspired by Anthropic’s “Building Effective Agents” In this piece, we’ll take a close look at the orchestrator–worker agent workflow. We’ll unpack its challenges and… Sanjana Yeddula Aparna Dhinakaran Sri Chavali September 9, 2025 11 min read -
 Open Source
Building a Multilingual Cypher Query Evaluation Pipeline
How to evaluate LLM performance across languages for complex cypher query generation using open source tools As organizations expand globally, the need for multilingual AI systems becomes critical.… Mohit Talniya September 9, 2025 12 min read -
 Open Source
Annotation for Strong AI Evaluation Pipelines
This post walks through how human annotations fit into your evaluation pipeline in Phoenix, why they matter, and how you can combine them with evaluations to build a… Sanjana Yeddula August 21, 2025 4 min read -
 Open Source
LLM-as-a-Judge: Example of How To Build a Custom Evaluator Using a Benchmark Dataset
When To Build Custom Evaluators Arize-Phoenix ships with pre-built evaluators that are tested against benchmark datasets and tuned for repeatability. They’re a fast way to stand up rigorous… Sanjana Yeddula August 12, 2025 2 min read
Don’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

