Everything we’ve published — page 10.
How to write effective AI agent skills: 6 data-backed practices
Three recent studies show what actually makes an AI agent skill effective: human expertise, compact procedures, tight routing,…
Read the post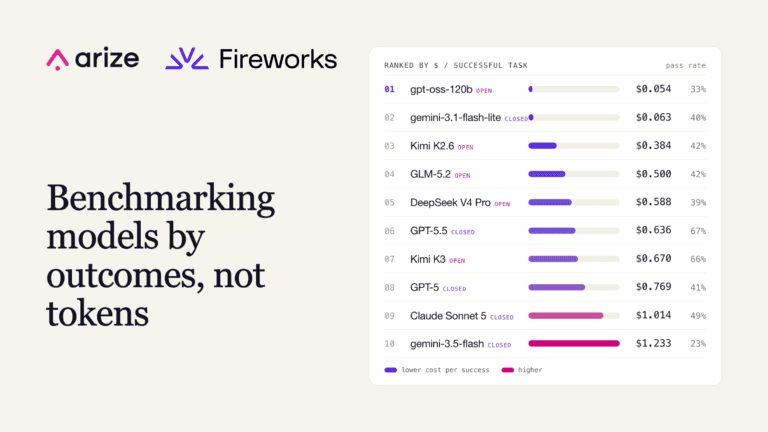
Cost per successful task: Benchmarking Kimi K3, GPT-5.5, and 8 more AI models
Arize and Fireworks benchmarked 10 AI models across 2,400 agent runs. Learn why cost per successful task beats…
Read the post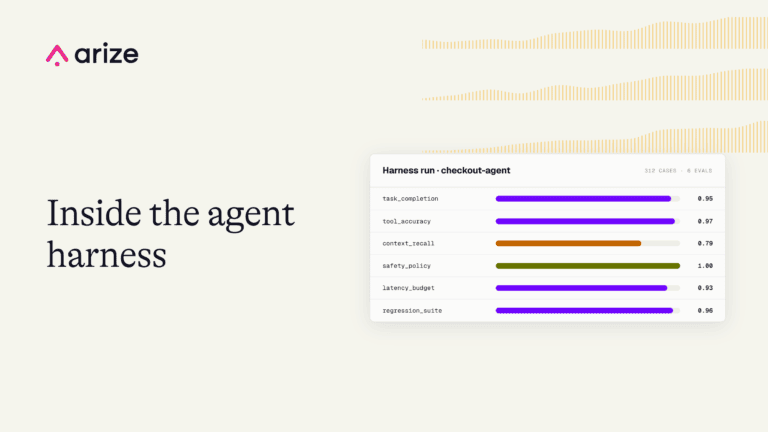
What is an agent harness? Architecture, controls, and evaluation
Learn how agent harnesses use tracing and evaluations to make AI agents observable, testable, safer, and easier to…
Read the guide
How to measure human-LLM judge alignment
No single metric proves an LLM judge is trustworthy. This field guide shows how to measure human–human agreement,…
Read the post
The definitive guide to LLM evaluations
LLM evaluation: Get from pre-production to deployment with our definitive guide to LLM evaluation. Includes LLM eval types,…
Read the guide
How OpenAI uses human feedback to evaluate and improve LLMs
At ChatGPT scale, user frustration arrives as support tickets, ratings, social posts, and corrections buried inside conversations. OpenAI…
Read the post
Inside Cursor’s agent factory: how it verifies AI-written code
As background agents take on more implementation work, Cursor is rebuilding the software development lifecycle around risk scores,…
Read the post
What is AI engineering?
AI engineering builds applications on top of models; it treats the model as a component rather than the…
Read the guide
LLM evaluation costs: Understanding hidden costs & budget models
Learn what drives LLM evaluation costs across offline tests and production, from judge tokens and trace volume to…
Read the guide
Kiro CLI observability: trace and evaluate agent changes with Arize Skills
Use Arize Skills with Kiro CLI to trace coding-agent changes, build datasets from failures, run experiments, and validate…
Read the post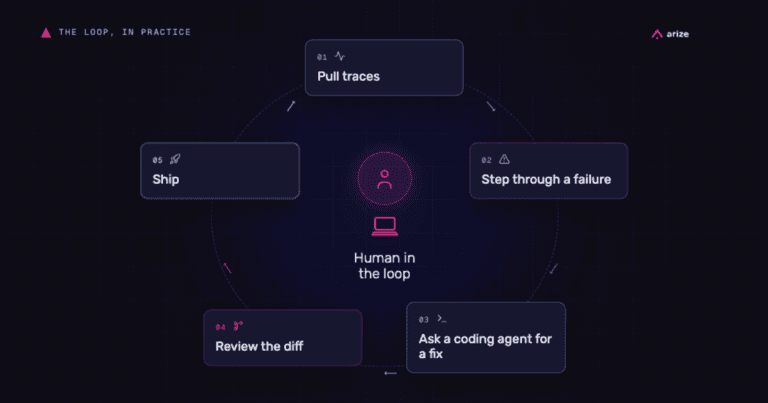
From human-operated agent development to systematic agent improvement
At Observe 2026, Jason Lopatecki and Aparna Dhinakaran described the shift from human-operated agent development to systematic agent…
Read the post
How to measure AI productivity: From LLM token costs to business value with Arize AX
AI productivity is best measured by connecting AI usage to validated downstream outcomes. Tokens, prompts, and generated lines…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

