Everything we’ve published — page 27.
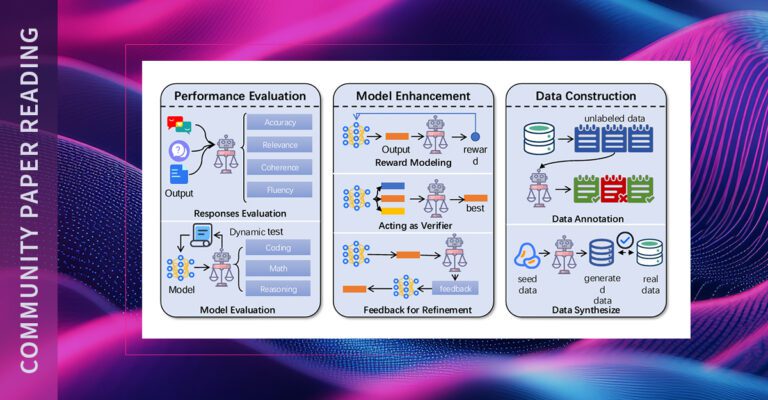
LLMs as Judges: A Comprehensive Survey on LLM-Based Evaluation Methods
We discuss a major survey of the LLMs-as-Judges paradigm: “LLMs-as-Judges: A Comprehensive Survey on LLM-based Evaluation Methods.” This…
Read the post
Arize Release Notes: Prompt Hub, Managed Code Evaluators and More
Welcome to our regular update on new releases, enhancements, and changes. What’s New Prompt Hub The Prompt Hub…
Read the post
How to Add LLM Evaluations to CI/CD Pipelines
In this post, we’ll explore how Continuous Integration and Continuous Deployment (CI/CD) can be used to evaluate large…
Read the post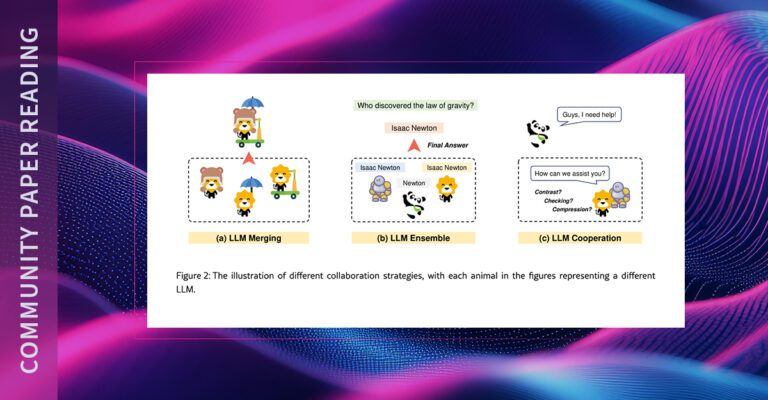
Merge, Ensemble, and Cooperate! A Survey on Collaborative LLM Strategies
LLMs have revolutionized natural language processing, showcasing remarkable versatility and capabilities. But individual LLMs often exhibit distinct strengths…
Read the post
Arize Release Notes: Copilot Enhancements, Experiment Projects, and More
Welcome to our regular update on new releases, enhancements, and changes. What’s New Copilot Enhancements Span Chat The…
Read the post
AI Agent Workflows and Architectures Masterclass
While popular imagination and industry discourse can paint AI agents as complex autonomous systems with a mind of…
Read the post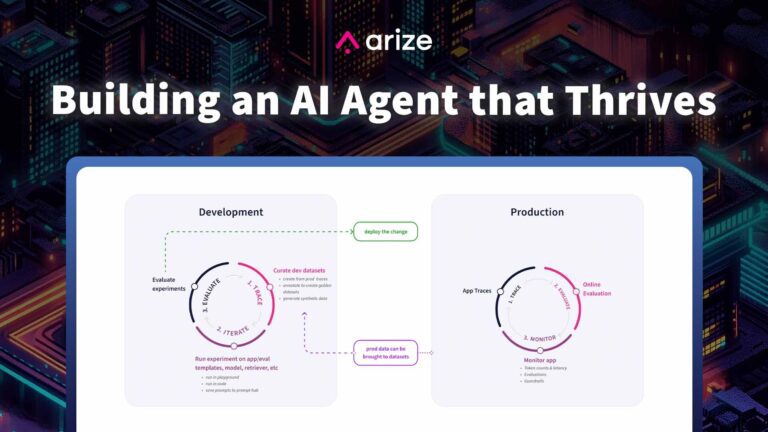
Building an AI Agent that Thrives in the Real World
Building an AI agent and keeping it running smoothly in production can feel like a daunting task. When…
Read the post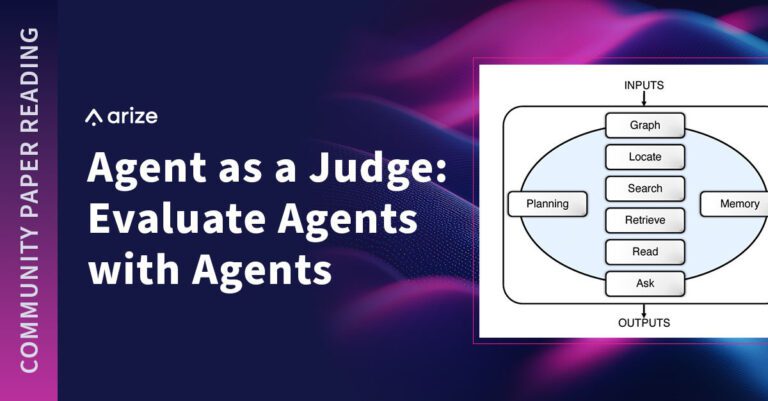
Agent-as-a-Judge: Evaluate Agents with Agents
This week we dive into a paper that presents the “Agent-as-a-Judge” framework, a new paradigm for evaluating agent…
Read the post
Instrumenting Your LLM Application: Arize Phoenix and Vercel AI SDK
Instrumentation is an important tool for developers building with LLMs. It provides insight into application performance, behavior, and…
Read the post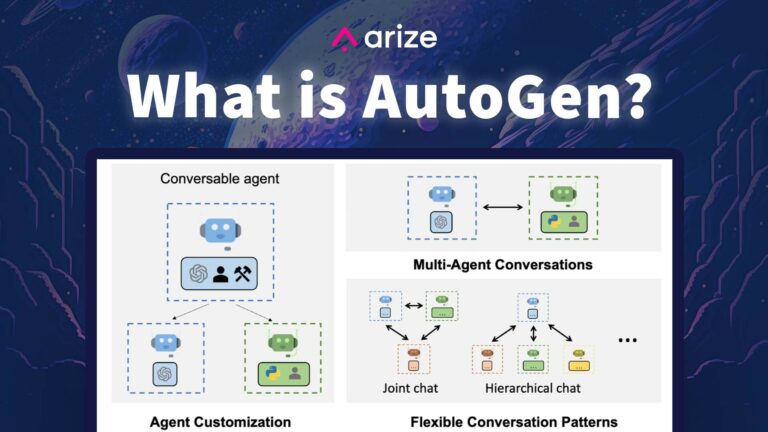
What is AutoGen?
Thanks to Ali Saleh for his contributions to this piece. AutoGen is a framework that helps you easily…
Read the post
Introduction to OpenAI’s Realtime API
We break down OpenAI’s realtime API. Sally-Ann DeLucia and Aparna Dhinakaran cover how to seamlessly integrate powerful language…
Read the post
o1-preview Time Series Evaluations
Time series anomaly detection is one of the most challenging tasks we tackle at Arize. Using large language…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

