

Overview
In this tutorial, you’ll build a retrieval-augmented generation (RAG) application with LlamaIndex, trace it in Arize AX, then evaluate, diagnose, and improve its retrieval quality. The application is a simple question-answering chatbot that answers from a single sample document. This tutorial is intended for AI engineers building RAG systems. It assumes you have basic knowledge of:- Python, and running scripts from a terminal
- How RAG works at a high level (retrieval + generation)
- LLM application concepts (embeddings, vector stores, prompts)
- Instrument a RAG application and send traces to Arize AX
- Evaluate retrieval relevance and answer correctness with LLM-as-a-judge
- Diagnose the three common retrieval failure modes using embeddings
- Run experiments to improve retrieval across chunk size, overlap, and
k
Background: how RAG retrieval works and where it fails
RAG connects your own data to an LLM. A user asks a question, an embedding is generated from the query, the most relevant context in your knowledge base is retrieved, and that context is added to the prompt sent to the LLM.
- Bad response. The end answer is wrong or unhelpful, often surfaced by negative user feedback or low eval scores. This is usually a symptom of one of the failures below.
- Missing context. The retriever couldn’t find any documents close enough to the query, meaning users are asking about topics missing from your corpus.
- Most similar is not most relevant. A document had the closest embedding to the query but wasn’t actually the most relevant one to answer it.

Before you start
Before you begin, you should have:- An Arize AX account. Sign up here and get your space ID and API key
- An OpenAI API key
- An LLM provider configured in Arize AX, required to run no-code evaluations in Step 2
- The required packages installed:
Step 1: Trace your RAG app
Arize AX auto-instruments many RAG stacks, including LlamaIndex and LangChain, and supports manual instrumentation for custom ones. This tutorial uses LlamaIndex. First, set your API keys as environment variables. Every step below reads credentials from here, so set them once before you start:data/ folder:

Step 2: Evaluate retrieval quality and correctness
Now that traces are flowing into Arize AX, evaluate them so you don’t have to manually inspect every trace. We’ll score two things:- Retrieval relevance: is the retrieved context relevant to the question? This is judged on the retriever span, which carries both the query (
input) and the retrieved documents. - Answer correctness: is the final answer correct given the retrieved context? This draws on two spans: the query and context come from the retriever span, and the answer comes from the LLM span.
Option A: Run a no-code evaluation task (recommended)
Create a task that runs an evaluator from the Eval Hub directly on your traces, with no export and no dataframe. You can do this from the UI, from Alyx, or theax CLI. In the UI, go to the Evaluators page, click New Task, and pick a prebuilt template in Add Evaluator. The Task Configuration screen then opens, where you set the scope, choose your rag-cookbook project as the data source, and map the template’s variables.
The filter box builds each condition as a chip: type a field, pick it from the list, choose an operator, then enter the value without quotes. Add one chip per condition. IS NOT NULL is the exists operator.
Retrieval relevance (span-level). Search for and pick the RAG Relevancy template, and keep the scope at Span. Filter to retriever spans that carry documents, using two chips:
attributes.openinference.span.kindequalsRETRIEVERattributes.retrieval.documentsexists
Answer correctness (trace-level). Correctness needs the question, the retrieved context, and the answer, which live on different spans. Search for “correct” and pick the Q&A template, then set the scope to Trace. Use a multi-span query so each variable reads from the right span. Click Add Filter to add a second span query, then fill in both:
Set Find Traces Matching to
A -> B, meaning the retriever runs before the LLM span. Don’t use A => B, which requires a direct parent-child link: in LlamaIndex the LLM span sits under the response synthesizer rather than the retriever, so A => B matches no traces. Then map each variable, using its from selector to pick the span query it reads from:
The Data preview under each variable shows what it reads from the latest matching trace, so check it shows the documents, the question, and the answer.
To try an evaluator before you run it, select a row in Matching results and click Test Evaluator On Spans. Then set how the task runs: give it a name, set the sampling rate, and choose Run Continuously, One-Time Backfill, or both. Run Continuously is on by default. Click Save on the evaluator, then Run Evaluator(s). Span-level results attach to the retriever spans, and trace-level results attach to each trace’s root span in the Tracing view. For the full task workflow, sampling guidance, and multi-span queries, see Run online evals on traces.
Option B: Run evaluations in code
Use this when you need to run evals on large datasets, incorporate external data, or want full control over execution and cost. Export your spans, run evals with Phoenix Evals, and log the results back onto your spans. First, export your spans and split them by role:{input}, {reference}) are filled from same-named columns in each row, so map the span attributes onto those column names first:
to_annotation_dataframe explodes the scores into label, score, and explanation columns and carries the context.span_id through; update_evaluations expects those under the eval.<name>.* convention:
context.trace_id so each row has the question, context, and answer together, then run a correctness classifier with a {question} / {context} / {answer} template and log it the same way. For the full column conventions and the 14-day span window, see Run online evals on traces.
Step 3: Diagnose retrieval failures with embeddings
With evals in place, use Arize AX to trace bad responses back to their root cause. These embedding-based diagnostics are most useful at production scale, comparing your live queries against your full document corpus. Here’s how Arize AX surfaces each of the three failure modes introduced earlier. Issue 1: Bad response. Arize AX automatically surfaces clusters of traces with low scores, using the retrieval relevance and correctness evals you logged in Step 2. You can also add user feedback on spans as another signal. A bad response is usually a symptom of one of the retrieval failures below. Issue 2: Missing context. The retriever couldn’t find documents close enough to the query, meaning users ask about topics missing from your corpus. Visualize query density to find topics you need to add documentation for: set your production data as user queries and your corpus as the baseline, then look for clusters of query embeddings with no nearby context embeddings.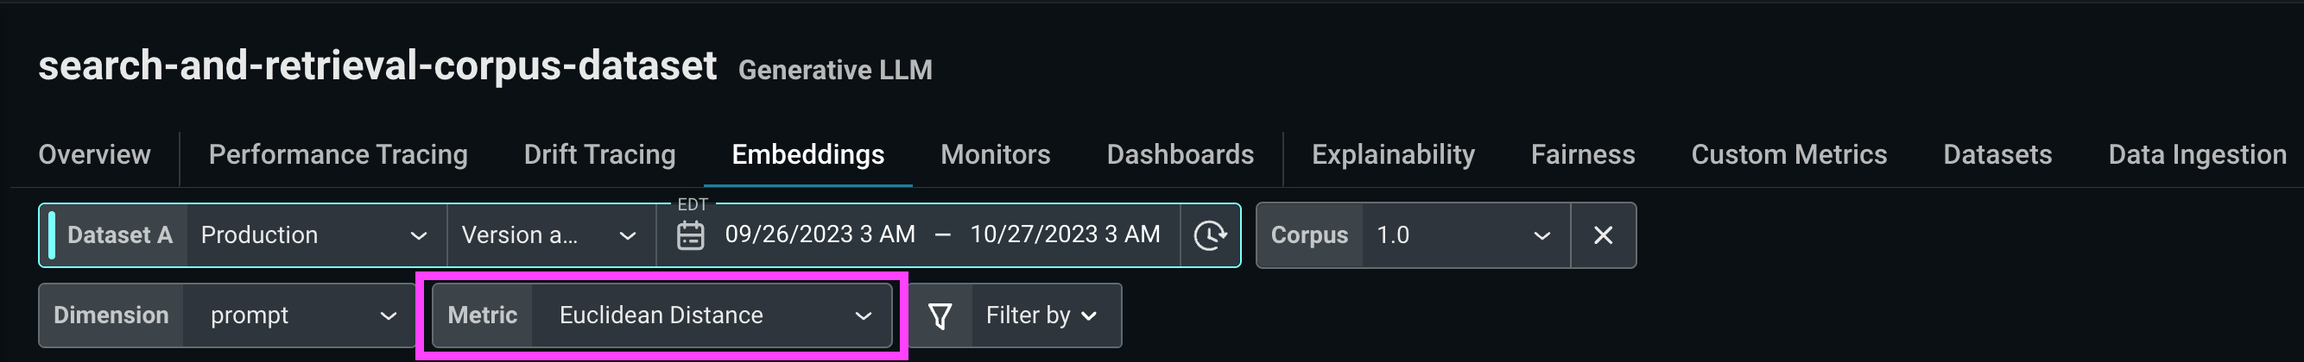

Step 4: Improve retrieval with experiments
Once you can measure quality, experiment to improve it. Generate a benchmark question set, then compare retrieval settings (chunk size, chunk overlap, and the number of documents retrieved,k) as experiments in Arize AX.
First, generate a synthetic set of test questions from the essay and put them in a dataframe with an input column:
EvaluationResult with a label, score, and explanation. An evaluator receives the task’s output and the dataset_row, so it can read the question, retrieved context, and answer:
client.experiments.run executes the task across every example, applies the evaluators, and logs the results to Arize AX so you can compare how chunk size, overlap, and k affect retrieval quality in the UI:

Summary
In this tutorial, you built a RAG application and used Arize AX to:- Trace retrieval, embeddings, and LLM calls end to end
- Score retrieval relevance and answer correctness with LLM-as-a-judge
- Diagnose missing-context and irrelevant-retrieval failures using embeddings
- Run experiments to improve retrieval across chunk size, overlap, and
k
Next steps
- Manually create retriever spans that log your retriever inputs and outputs
- Evaluate across more dimensions such as hallucination, citation, and user frustration with prebuilt evaluators
- Go deeper on datasets and experiments