Blog — page 17.
How DeepSeek is Pushing the Boundaries of AI Development
How do you train an AI model to think more like a human? That’s the challenge DeepSeek is…
Read the post
Arize AI Raises $70M Series C to Build the Gold Standard for AI Evaluation & Observability
In 2020, we founded Arize with a clear mission: to give teams the tools they need to understand,…
Read the post
How to Build An AI Agent
An agent is a software system that orchestrates multiple processing steps— including calls to large language models—to achieve…
Read the post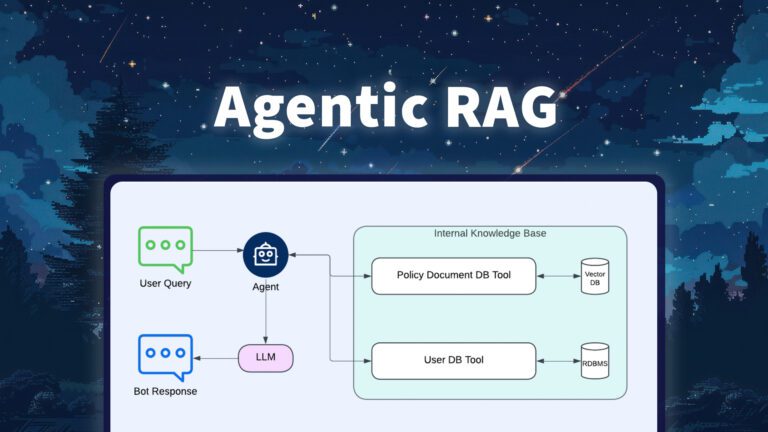
Understanding Agentic RAG
Retrieval-Augmented Generation (RAG) has become a cornerstone in AI applications, and as our needs grow, more complex, traditional…
Read the post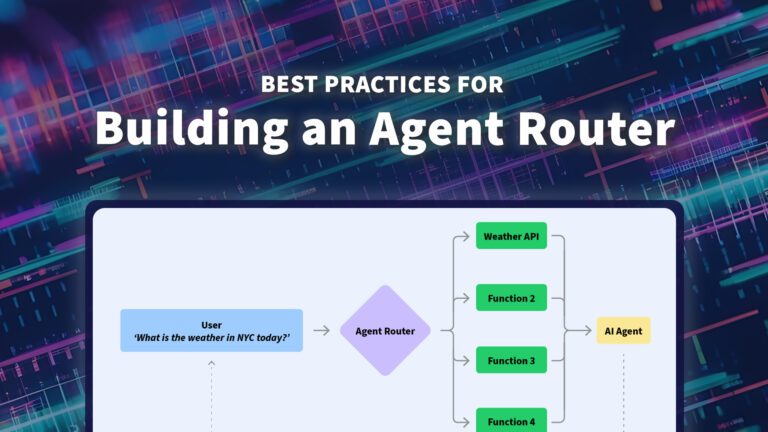
How to Build an AI Agent Router: Best Practices
Best practices for building an AI agent router including routing strategies, model selection, and evaluation patterns to send…
Read the post
Quick Guide to the EU AI Act for AI Teams
The EU AI Act is the world’s first comprehensive AI regulation, meant to promote responsible AI development and…
Read the post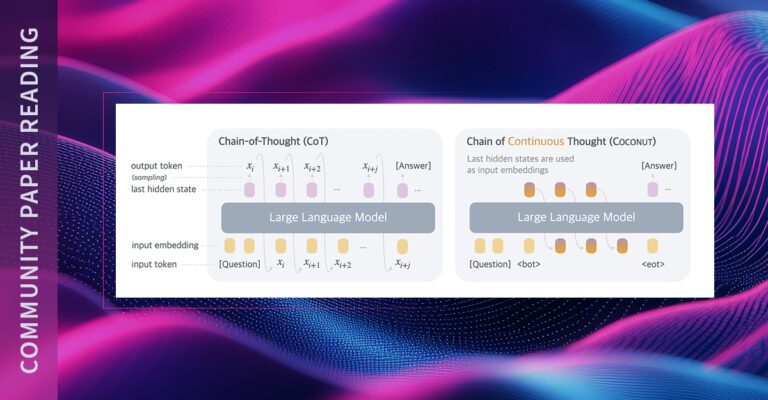
Training Large Language Models to Reason in Continuous Latent Space
LLMs have traditionally been restricted to reason in the “language space,” where chain-of-thought (CoT) is used to solve…
Read the post
Building Audio Support with OpenAI: Insights from our Journey
Introduction In early October last year, OpenAI launched the beta version of their Realtime API, which introduced an…
Read the post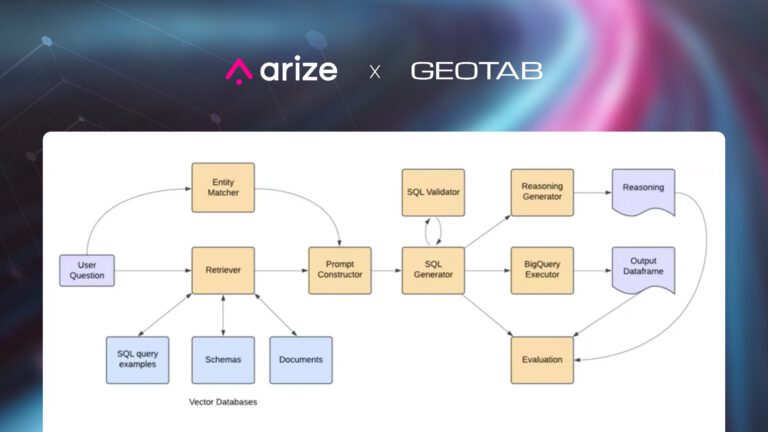
How Geotab and Arize AI Revolutionized Fleet Management with Generative AI
Geotab, a leader in fleet telematics, has taken a bold step forward in simplifying complex fleet data management.…
Read the post
Arize Phoenix: 2024 in Review
2024 was Arize Phoenix‘s biggest year ever. Granted, it was also Phoenix’s first full year ever, but given…
Read the post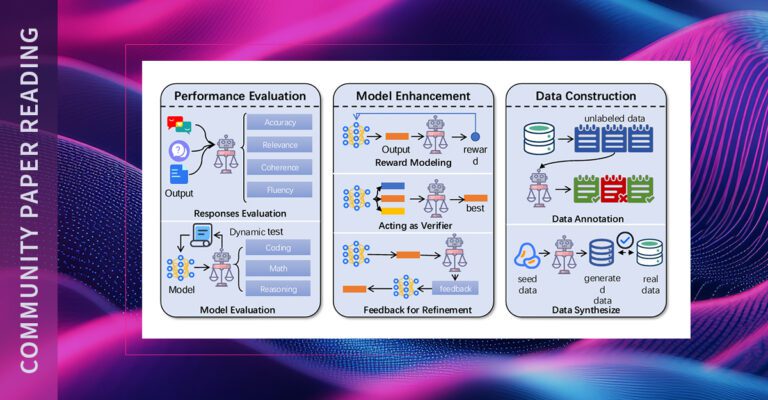
LLMs as Judges: A Comprehensive Survey on LLM-Based Evaluation Methods
We discuss a major survey of the LLMs-as-Judges paradigm: “LLMs-as-Judges: A Comprehensive Survey on LLM-based Evaluation Methods.” This…
Read the post
Arize Release Notes: Prompt Hub, Managed Code Evaluators and More
Welcome to our regular update on new releases, enhancements, and changes. What’s New Prompt Hub The Prompt Hub…
Read the postDon’t ship vibes.
Arize gives AI teams observability and evals to understand and improve agent performance.

