Docker Sandboxes for Code Evaluators
October 8, 2026 Available in arize-phoenix 20.20.0+ Docker Sandboxes gives code evaluators a hosted runtime when your team already has Docker Agentic Platform access. Add your Docker credentials in Settings → Sandboxes, then choose Docker Sandboxes on the sandbox configuration you use for Python or TypeScript evaluators. Phoenix still owns the evaluator flow: it sends the run to Docker, applies the network setting, and cleans up when the run finishes.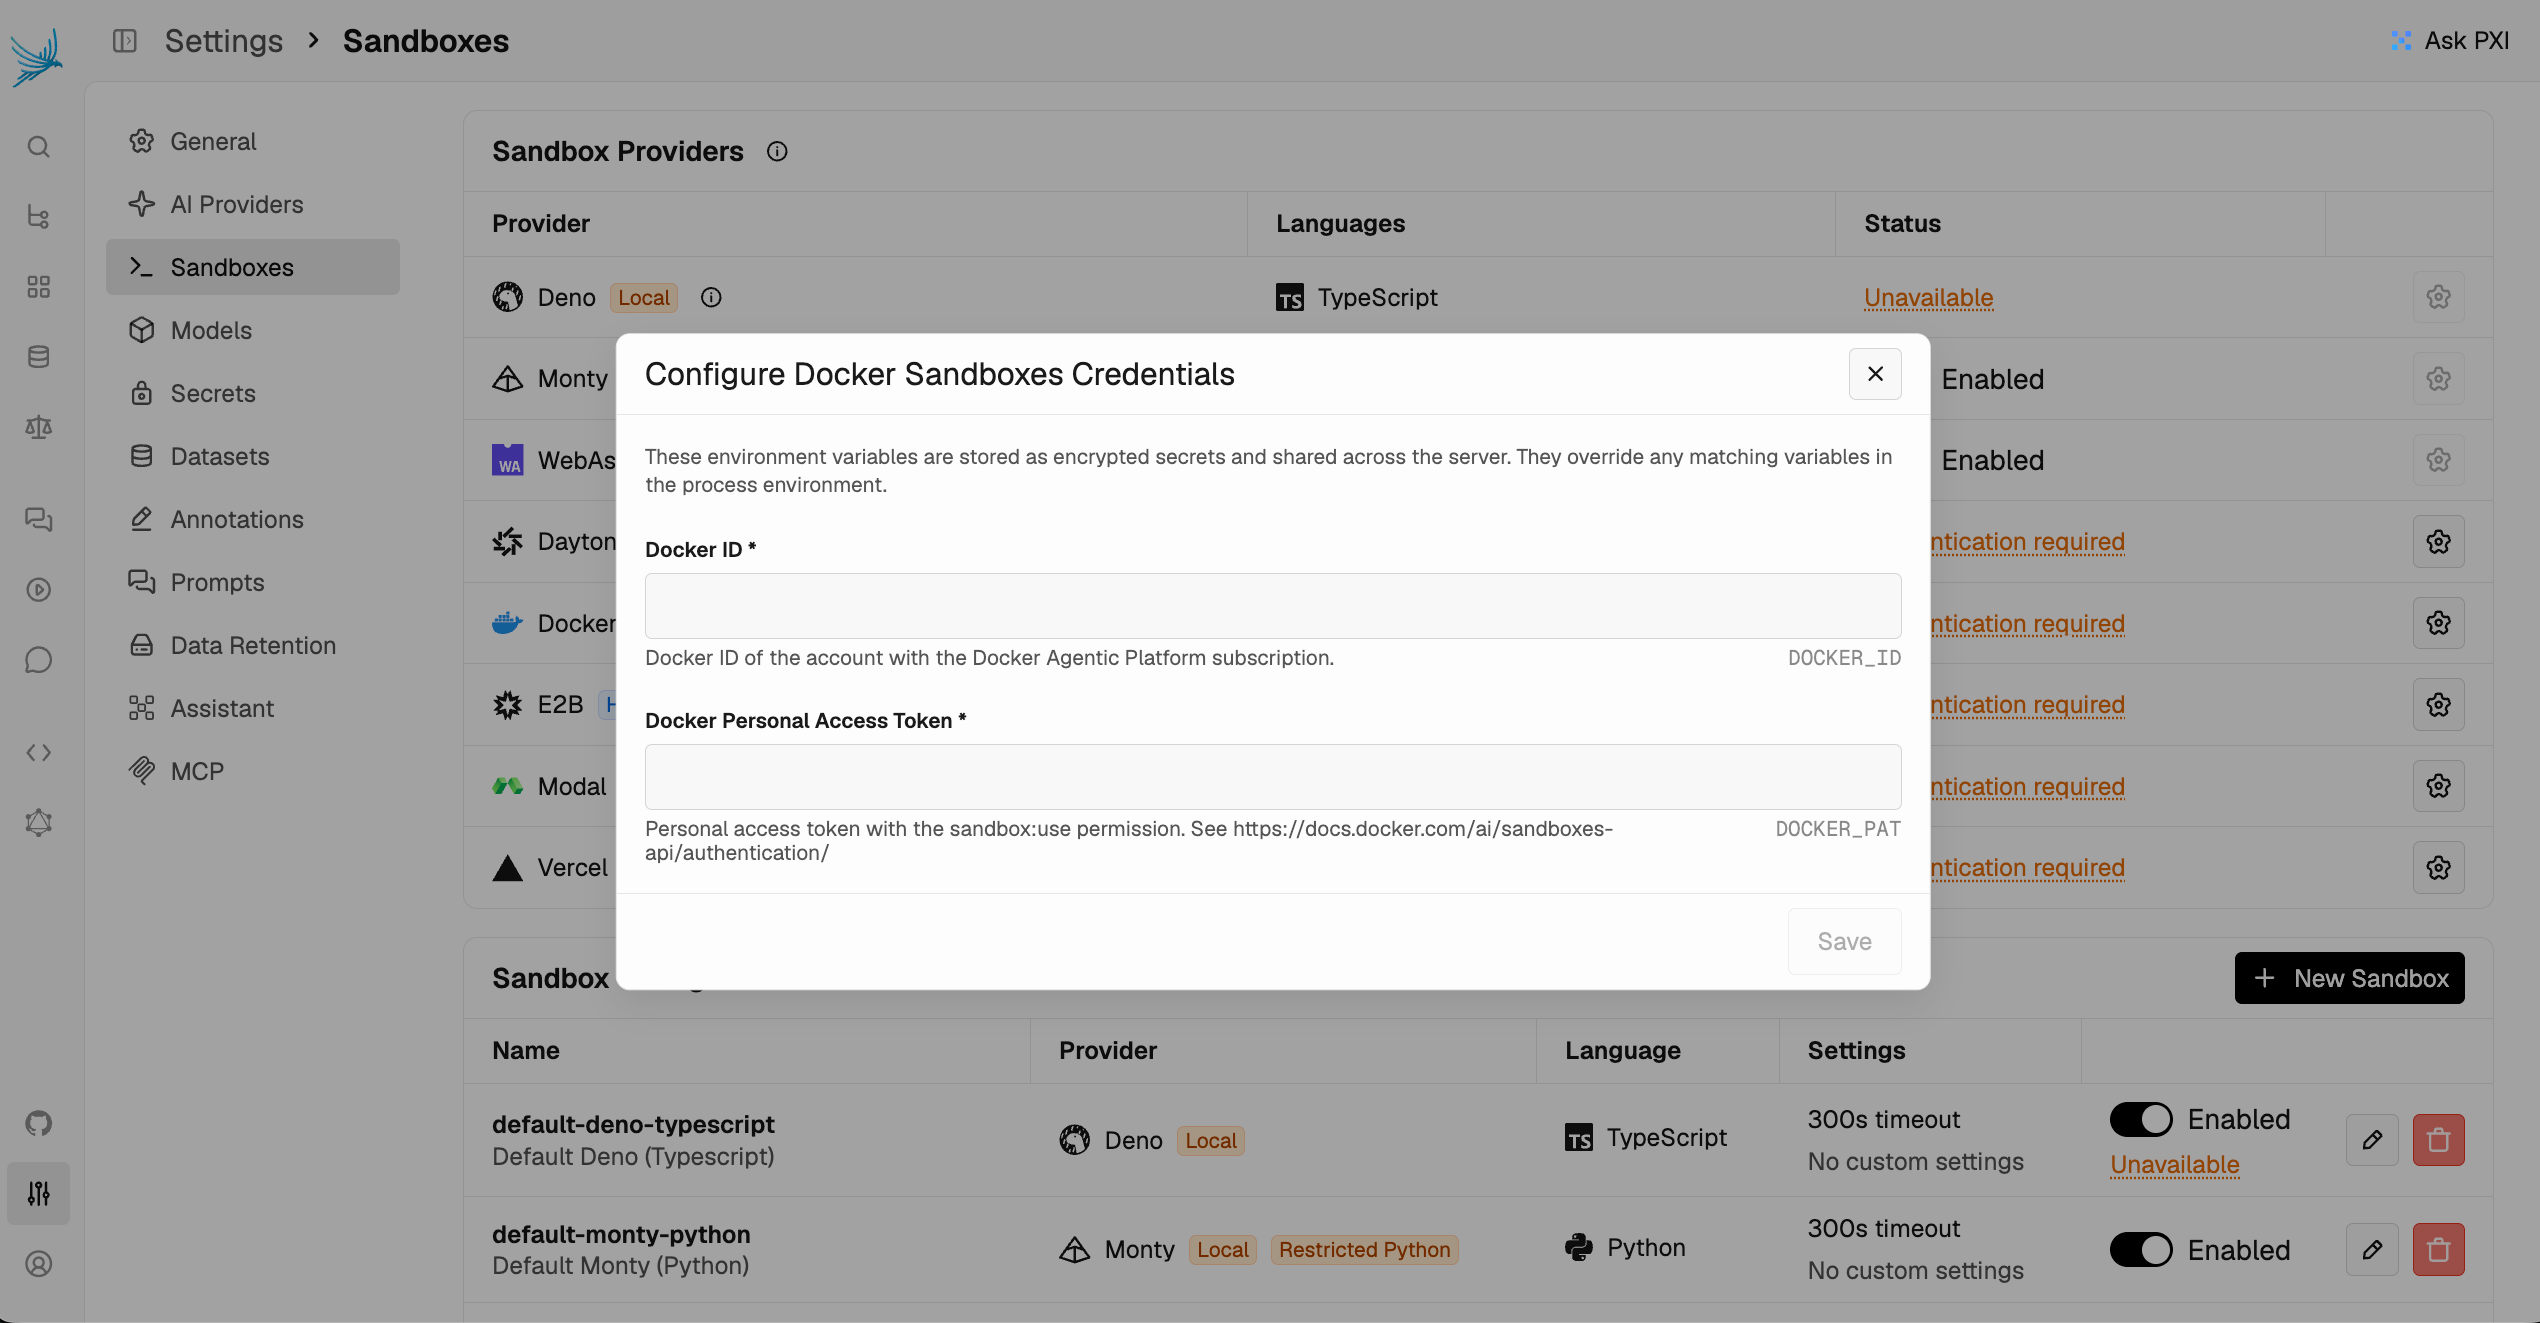
Configure Docker Sandboxes once, then use it for Python and TypeScript code evaluators
- Run both evaluator languages. Python runs on
python:3.13-slimand TypeScript onnode:24-slim. - Authenticate once. Add your Docker ID as
DOCKER_IDand a personal access token with thesandbox:usepermission asDOCKER_PAT, either in Settings or as server environment variables. - Control network access. Deny attaches a
phoenix-deny-all-egressnetwork policy that stops sandbox traffic from leaving the environment. - Clean up automatically. Phoenix deletes each sandbox when the evaluator finishes. Docker also expires every sandbox after 10 minutes.
Docker Sandboxes
Requirements, setup, and sandbox behavior
Code Evaluators
Write Python and TypeScript evaluators that run on the server
Claude Haiku 5.5 and Mistral Cost Tracking
October 8 to 11, 2026 Available in arize-phoenix 20.20.0+ (Claude Haiku 5.5) and 20.21.0+ (Mistral pricing) You can test Claude Haiku 5.5 in the playground and see token cost on Mistral spans without adding custom pricing.- Claude Haiku 5.5 is in the playground for the Anthropic and Amazon Bedrock providers, with adaptive thinking support.
- Retired Anthropic models no longer appear in model lists. Phoenix removes Claude Opus 4.1, Sonnet 3.7, Sonnet 3.5, Haiku 3.5, and Haiku 3.
- Mistral AI calls now show a cost. Phoenix prices Mistral spans from the built-in model price list, the same way it handles other providers.
Cost Tracking
How Phoenix prices tokens on your spans
MCP Server: GraphQL Tools and More SQL Tables
October 8, 2026 Available in arize-phoenix 20.20.0+ Use GraphQL when an MCP client needs structured Phoenix data that REST does not expose. The agent can inspect the schema and run authorized queries from the MCP server, instead of falling back to shell access or one-off scripts.- Discover and query the schema.
describeGraphqlSchemasearches by free text or exact type names, andexecuteGraphqlQueryruns read-only queries with the caller’s permissions. - Run permitted mutations when writes are enabled.
executeGraphqlMutationcan run any mutation the caller’s role allows. Phoenix does not expose this tool on read-only deployments. - Ask SQL questions over more Phoenix tables.
executeSqlcan query trace annotations, evaluators, prompts and prompt versions, dataset splits and labels, experiment tags, jobs and logs, sandbox configs, and trace retention policies. - PXI uses analytics SQL for data questions, so it spends fewer turns answering aggregate questions about your traces.
MCP Server
Connect an MCP client and see the full tool list
Additional Improvements
October 8 to 13, 2026 Available in arize-phoenix 20.20.0–20.21.3, arize-phoenix-evals 3.9.1+, and @arizeai/phoenix-client 7.16.1+- Evaluator metadata stays attached. The server keeps metadata nested under
result, and the TypeScript client sends metadata at the top level. - Stale input mappings no longer break evaluator runs when you remove a variable from the
template or
evaluate()signature. - Experiment resume cleans up replaced runs by dropping evaluations from an errored run when a new run takes its place.
- Experiment metric comparisons are consistent because Phoenix measures the base experiment and compare experiment the same way.
- Span ingestion recovers from database failures more reliably and reports failed spans and the last successful insert as Prometheus metrics.
- Projects from span ingestion are easier to scan because Phoenix gives each new project a random gradient.
arize-phoenixinstalls fewer heavy dependencies because SciPy and scikit-learn are no longer included by default.- Synchronous eval runs retry rate-limit errors instead of failing the whole run on the first 429.